WO2010098178A1 - 情報推薦装置、情報推薦方法および情報推薦プログラム - Google Patents
情報推薦装置、情報推薦方法および情報推薦プログラム Download PDFInfo
- Publication number
- WO2010098178A1 WO2010098178A1 PCT/JP2010/051436 JP2010051436W WO2010098178A1 WO 2010098178 A1 WO2010098178 A1 WO 2010098178A1 JP 2010051436 W JP2010051436 W JP 2010051436W WO 2010098178 A1 WO2010098178 A1 WO 2010098178A1
- Authority
- WO
- WIPO (PCT)
- Prior art keywords
- keyword
- document
- interest
- interest keyword
- subject
- Prior art date
- Legal status (The legal status is an assumption and is not a legal conclusion. Google has not performed a legal analysis and makes no representation as to the accuracy of the status listed.)
- Ceased
Links
Images




Classifications
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F16/00—Information retrieval; Database structures therefor; File system structures therefor
- G06F16/30—Information retrieval; Database structures therefor; File system structures therefor of unstructured textual data
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F16/00—Information retrieval; Database structures therefor; File system structures therefor
- G06F16/90—Details of database functions independent of the retrieved data types
- G06F16/95—Retrieval from the web
- G06F16/951—Indexing; Web crawling techniques
Definitions
- the present invention relates to an interest extraction apparatus and an interest extraction method for determining which part a user viewing text information such as a web page or a manuscript is interested in and recommending information suitable for the user.
- keywords included in the page may simply be extracted, and different search results such as homonyms may be presented only by searching. Also, even when looking at the same document, depending on the context up to that point, it may be different which content you are focusing on. In addition, because the attention point can not be determined properly, it can not be guessed at the time of presentation how much the recommendation content is in line with the user's interest.
- the conventional proposal there is a technology that focuses on the term pointed to in the page and searches related documents, but on the basis of the interest in the previous document, the technology that indicates the recommended content from the current document to the next Not proposed.
- the present invention has been made in view of the above, and is to more appropriately perform content service recommendation in accordance with the user's interest. For example, if the user is looking at the page of "Franish restaurant in Kawasaki" just before looking at the page regarding "Kawasaki chicken wings shop” in relation to the page browsed just before, "Kawasaki” will be focused It is a point, and it can be seen that "Toba” is a point of interest when looking at the "Yokohama chicken wings” page. Therefore, the information to be presented next is the user's interest rather than the important keywords derived from the text currently being browsed, by the search (continuation of interest) taking into consideration the attention point, or the recommendation and search of related keywords based on the transition of interest. You will be able to make content recommendations based on the keywords that fit your needs.
- An object of the present invention is to appropriately recommend content and services that are in the interest of the user.
- An information recommendation apparatus includes: an input unit for inputting a plurality of documents; a subject keyword extraction unit for extracting a subject keyword from a predetermined document and a document immediately preceding the predetermined document; An interest keyword extraction unit for extracting an interest keyword from the subject keyword of the previous document and the subject keyword of the predetermined document, an interest keyword history storage unit for storing the interest keyword, and the interest keyword extraction unit A next interest keyword that the user is likely to be interested next is extracted based on the information specifying the document, the interest keyword, and the subject keyword of the predetermined document, and the next interest keyword of the predetermined document is extracted based on the next interest keyword.
- An acquisition unit for acquiring a document, and a presentation unit for presenting the next document.
- web pages are mainly targeted as information or documents to be browsed.
- the web page in addition to text information, a web page including still images and moving images is treated in the same manner.
- FIG. 1 is a functional block diagram showing an interest extraction apparatus 100 according to the present embodiment.
- the interest extraction apparatus 100 receives the URL or display content of the document being browsed by the browse information input unit 101 from the information presentation apparatus 200.
- the subject keyword extraction unit 102 extracts the subject keyword of the document from the text information input by the browsing information input unit 101.
- the interest keyword extraction unit 103 extracts an interest keyword that is a keyword representing the current interest of the user from the text information and the subject keyword extracted by the subject keyword extraction unit, and corresponds the pair of the extracted interest keyword and the URL.
- a chaining rule storage unit 105 is stored in the chaining rule storage unit 105, which is a means for searching for the next document according to the interest keyword.
- the linkage rule application unit 106 applies a linkage rule stored in the linkage rule storage unit 105 to the interest keyword extracted by the interest keyword extraction unit 103 to generate a search query.
- the recommendation information acquisition unit 107 searches for a content candidate to be recommended next using the search query generated by the linkage rule application unit 106.
- the information presentation apparatus 200 includes the recommendation information presented by the information selection unit 202 and information to be browsed next Select according to the user's input.
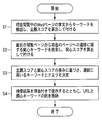
- FIG. 2 is a flowchart showing the operation of the interest extraction apparatus according to the present embodiment.
- keywords are extracted from the text of the web page (URL (t)) currently being browsed by the user, and the subject score is calculated and attached (step S1).
- the position of the keyword in the web page is used. For example, the keyword in front of the title or body has a high score. However, it is considered that correction by the display area is also possible. For example, if you move to the bottom of a web page, keywords that originally had a low score appear higher on the display, the higher the score for that keyword.
- an interest keyword related to the transition from the web page (URL (t-1)) just browsed to the current web page is retrieved, and an interest score is calculated and attached (step S2).
- a keyword of interest for example, when a hyperlink in the text is clicked, keywords in the vicinity of the hyperlink are regarded as a keyword of interest.
- the interest score the closer the user clicks or focuses on a keyword or hyperlink, the higher the score.
- step S3 based on the calculated weight of the subject score and the interest score, keywords and queries to be used in the chain are determined.
- a query search method and a presentation method are determined with reference to the linkage rules stored in the linkage rule storage unit 105 using the subject score and the interest score. Chaining rules will be explained later.
- the search result is presented with a reason, the pair of the URL of the web page and the interest keyword is stored in the interest keyword history storage unit (step S4), and the process ends.
- the reason it is to use the chain rule presentation method to insert and display the keywords of interest.
- the user browses a web page by the information selection unit 202 using the information presentation apparatus 200.
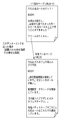
- An example of text included in the browsing information is shown in FIG.
- the browsing information input unit inputs text information included in the selected web page.
- TITLE means the title of the page
- BODY means the text of the page.
- the subject keyword extraction unit extracts subject keywords included in the text and assigns a score.
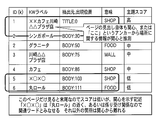
- FIG. 4 shows the subject keywords extracted when the URL (t-1) immediately before the currently viewed web page is browsed. Extraction of keywords is performed using morphological analysis and specific expression extraction, ID as a serial number for each keyword, label of extracted keyword, appearance position indicating the origin of the extraction source such as TITLE, BODY, etc., extraction The keyword label, the keyword semantic classification, and the subject score which is the score of the keyword are extracted and calculated.
- ID a serial number for each keyword
- label of extracted keyword label of extracted keyword
- appearance position indicating the origin of the extraction source such as TITLE, BODY, etc.
- extraction The keyword label, the keyword semantic classification, and the subject score which is the score of the keyword are extracted and calculated.
- the subject score is higher in the front of the title and the main text, and higher in the appearance of both the title and the main text, a higher score is given.
- the interest keyword extraction unit 103 associates the keyword included in the page being browsed with the URL of the next page as the interest keyword.
- the notation "here” is a hyperlink to URL (t), but as shown in FIG. "Roll cake” "cream” can be considered as a term that indicates an interest in URL (t).
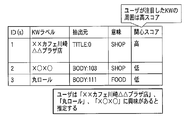
- a list of interest keywords corresponding to the transition from URL (t-1) to URL (t) is shown in FIG.
- the keyword is extracted using subject keyword extraction, and an ID as a serial number, a label of the extracted keyword, an origin of extraction source, a semantic classification of the keyword, and an interest score are extracted and calculated for each keyword.
- the interest score is higher as it is closer to the anchor text.
- the set of URLs corresponding to the transition and the interest keyword are stored in the interest keyword history storage unit 104.
- the interest keyword extraction unit 103 is a keyword that appears in the vicinity of the interest keyword “circle roll” indicating the transition taken this time, which is the keyword “XX cafe ⁇ Kawasaki plaza store” having a high subject score, and A set of (round roll, X ⁇ X ⁇ ) is extracted as a new interest keyword for searching and presenting recommendation information.
- the extracted query interest keywords are shown in FIG.
- the linkage rule application unit 106 uses the linkage rules stored in the linkage rule storage unit 105, and selects an applicable linkage rule based on the subject score of the interest keyword, the interest score, and the semantic classification.
- FIG. 8 shows an example of a chaining rule stored in the chaining rule storage unit 105.
- the rule ID which shows the serial number of each rule, the semantic classification of a keyword, the subject score of a keyword, the interest score of a keyword, the search method selected, and a presentation method are shown.
- a search method a search service such as a specific web service or a search with a target domain specified is assumed.
- the presentation method is a template of header information at the time of final recommendation.
- the rule ID 1 is described as " ⁇ ⁇ is such a store!, A specific interest keyword is inserted in ⁇ ⁇ , for example, "X ⁇ X ⁇ is this store! Is displayed on.
- a combination of the food "round roll” and the store “X ⁇ X ⁇ ” is a query for the store information search service called "X ⁇ X ⁇ AND round roll” based on rule 1 Is searched.
- the recommendation information acquisition unit 107 actually executes the search query generated by the linkage rule application unit 106.
- search means other than the web service such as a database search such as a dictionary stored in the interest extraction apparatus 100 itself may be used.
- the URL which is the result acquired by the recommendation information acquisition unit 107 is stored in the interest keyword history storage unit 104 in combination with the interest keyword which is the source of the query.
- the result acquired by the recommendation information acquisition unit 107 is presented to the user in the information presentation apparatus 200 by the recommendation information presentation unit 201 in combination with the presentation method described in the linkage rule stored in the linkage rule storage unit 105.
- a web page corresponding to the URL of the recommendation result is displayed as a browse page of the information presentation device 200.
- An example of the final presentation content is shown in FIG.
- selecting the information presentation content presented by the recommendation information presentation unit 201 while browsing a certain web page is always the same as when selecting a hyperlink in the web page corresponding to the URL (t).
- the browsing is performed in a state where the keyword of interest and the URL are paired, and the interest extraction apparatus 100 can recommend information while tracking the user's interest.
- keywords included in the page viewed immediately before are used as the keywords of interest, but a keyword such as n pages before is used while leaving the score attenuated by a function of n such as 1 / n. You may
- a keyword representing a situation where the user is currently placed may be additionally input.
- a word such as "Kawasaki” as a keyword indicating the current position.
- the interest extraction apparatus 100 includes a control device such as a CPU, a storage device such as a ROM or a RAM, an external storage device such as an HDD, a display device such as a display device, and an input device such as a keyboard or a mouse. It can also be applied to general computers.
- the interest extraction apparatus of the above embodiment can be realized, for example, by using a general-purpose computer device as basic hardware.
- the program to be executed has a module configuration including the above-described functions.
- the program is a file in an installable format or an executable format and recorded on a computer readable recording medium such as CD-ROM, floppy (registered trademark) disk, CD-R, DVD, etc. May be provided in advance.
- this interest extraction device can also be realized, for example, by using a general-purpose computer device as basic hardware. That is, the browse information input unit 101, the subject keyword extraction unit 102, the interest keyword extraction unit 103, the linkage rule application unit 106, the recommendation information acquisition 107, the recommendation information presentation unit 201, and the information selection unit 202 are installed in the above computer device. It can be realized by causing the processor to execute the program.
- the interest extraction apparatus may be realized by installing the above program into a computer device in advance, or may be stored in a storage medium such as a CD-ROM, or distributed through a network. The program may be implemented by installing this program on a computer device as appropriate.
- the interest keyword history storage unit 104 and the chain rule storage unit 105 are memory built in or externally attached to the above-mentioned computer apparatus, storage media such as a hard disk or CD-R, CD-RW, DVD-RAM, DVD-R, etc. And so on as appropriate.
- an input unit for inputting a plurality of documents, a subject keyword extraction unit for extracting a subject keyword from a predetermined document and a document immediately preceding the predetermined document, and a subject of the immediately preceding document
- An interest keyword extraction unit for extracting an interest keyword from keywords and subject keywords of the predetermined document
- an interest keyword history storage unit for storing the interest keyword
- the interest keyword extraction unit for specifying the predetermined document
- An acquisition unit that extracts a next interest keyword that the user is likely to be interested next based on the interest keyword and the subject keyword of the predetermined document, and acquires a next document of the predetermined document based on the next interest keyword
- a presentation unit that presents the next document.
- the second invention is the information according to the first invention, wherein the interest keyword extraction unit extracts the interest keyword in consideration of the transition from the subject keyword of the immediately preceding document to the predetermined document. It is a recommendation device.
- a third invention is the information recommendation device according to the first invention, wherein the input unit acquires the document itself based on the information specifying the predetermined document.
- a fourth invention is the information recommendation device according to the first invention, wherein the input unit acquires only the title, the summary, and the text area from the predetermined document.
- a chain rule storage unit storing a search rule for chaining to the next content based on the type of the interest keyword extracted by the interest keyword extraction unit, the interest keyword and the chain rule. It is an information recommendation device according to the first invention, further comprising: a chain rule application unit that generates a search query based on the above.
- the sixth invention is the information recommendation device according to the first invention, further comprising an information selection unit for selecting the next document presented by the presentation unit.
- the seventh invention is the information recommendation device according to the first invention, wherein the interest keyword extraction unit additionally inputs an additional keyword representing a user's own situation such as a place where the user is or action of the user. is there.
- the eighth invention is the information recommendation according to the first invention, wherein the keyword-of-interest extraction unit extracts a keyword of interest included in a document browsed up to a plurality of times for which a range has been determined in advance with a weight. It is an apparatus.
- the ninth invention is the information recommendation device according to the first invention, wherein, when the interest keyword extraction unit browses the read document again, the score for the interest keyword included in the document read immediately before is lowered. is there.
- 100 ... interest extraction device, 101 ... browsing information input unit, 102 ... subject keyword extraction unit, 103 ... interest keyword extraction unit, 104 ... interest keyword history storage unit, 105 ... linkage rule storage unit, 106 ... linkage rule application unit, 107 ... Recommendation information acquisition unit, 200 ... Information presentation device, 201 ... Recommendation information presentation unit, 202 ... Information selection unit,
Landscapes
- Engineering & Computer Science (AREA)
- Theoretical Computer Science (AREA)
- Databases & Information Systems (AREA)
- Data Mining & Analysis (AREA)
- Physics & Mathematics (AREA)
- General Engineering & Computer Science (AREA)
- General Physics & Mathematics (AREA)
- Information Retrieval, Db Structures And Fs Structures Therefor (AREA)
- Management, Administration, Business Operations System, And Electronic Commerce (AREA)
Abstract
関心抽出装置(100)は、閲覧中の文書のURLが閲覧情報入力部(101)によって受けて、本文情報から文書の主題キーワードを主題キーワード抽出部(102)で抽出する。抽出された主題キーワードとからユーザの現在の関心を表すキーワードである関心キーワードを関心キーワード抽出部(103)で抽出して関心キーワード履歴格納部(104)に格納する。関心キーワードに応じて、連鎖ルール格納部105に格納する連鎖ルールを用いて、検索クエリを連鎖ルール適用部(106)で生成する。連鎖ルール適用部(106)によって生成された検索クエリを用いて次に推薦するコンテンツの候補を推薦情報取得(107)で検索して、推薦情報提示部(201)に提示する。
Description
本発明は、ウェブページや原稿などのテキスト情報を閲覧中のユーザがどの部分に興味を持っているか判断し、ユーザにとって適切な情報を推薦する関心抽出装置および関心抽出方法に関する。
従来、ウェブページや原稿などのテキスト情報(以下、文書)を閲覧中のユーザがどの部分に興味を持っているか判断し、ユーザにとって適切な情報を簡単に推薦したいという要求がある。この種の装置としては、ページ中のキーワードへの操作によりその周囲の重要度を更新する技術が提案されている(例えば特許文献1参照)。
しかしながら、上記の方法では、単純にそのページに含まれるキーワードを抽出し、検索するだけでは同音異義語などで異なる検索結果を提示する場合がある。また、同じ文書を見る場合でもそれまでの文脈によってどの内容に注目しているか異なる場合がある。また、注目点が適切に判断できないことにより、推薦内容がユーザの関心にどれだけ沿っているか提示時に推測することができない。従来提案では、そのページ内でポイントした用語の周辺に注目し、関連文書を検索する技術はあるが、直前の文書における関心に基づき、現在の文書から次の文書への推薦内容を示す技術は提案されていない。
本発明は、上記に鑑みてなされたものであって、ユーザの関心にあったコンテンツ・サービス推薦をより適切に行うことである。例えば、直前に閲覧したページとの関係により「川崎の手羽先屋」に関するページを見ている時に、ユーザが直前に「川崎のフランス料理屋」のページを見ている場合は「川崎」が注目ポイントであり、「横浜の手羽先屋」のページを見ている場合は「手羽先」が注目ポイントであることが分かる。したがって、次に提示する情報は注目ポイントを考慮した検索(関心の継続)、あるいは関心の推移に基づく関連キーワードの推薦および検索により、現在閲覧中の本文単独で導かれる重要キーワードよりもユーザの関心に合ったキーワードに基づくコンテンツ推薦ができるようになる。
本発明の目的は、ユーザの関心にあったコンテンツやサービスを適切に推薦することである。
本発明の一態様に係る情報推薦装置は、複数の文書を入力する入力部と、所定の文書と前記所定の文書の一つ前の文書から主題キーワードを抽出する主題キーワード抽出部と、前記一つ前の文書の主題キーワードと前記所定の文書の主題キーワードから関心キーワードを抽出する関心キーワード抽出部と、前記関心キーワードを格納する関心キーワード履歴格納部と、前記関心キーワード抽出部は、前記所定の文書を特定する情報と前記関心キーワードと前記所定の文書の主題キーワードとに基づき次にユーザが関心を示しそうな次関心キーワードを抽出し、前記次関心キーワードに基づき、前記所定の文書の次の文書を取得する取得部と、前記次の文書を提示する提示部と、を備える。
本発明によれば、ユーザの関心にあったコンテンツ・サービス推薦をより適切に行えるようになる。
以下、本発明の実施の形態について図面を参照しながら説明する。
本実施形態では、サーバにおいて関心抽出装置100が使用され、ユーザが所有する端末において情報提示装置200が使用されることを想定しているが、関心抽出装置100および情報提示装置200が同じ端末において使用される場合も同様である。また、本実施形態においては、閲覧する情報あるいは文書として主にウェブページを対象とする。ここで、ウェブページとしてはテキスト情報に加え、静止画像や動画像を内部に含むものも同様に扱われる。
図1は本実施形態に係る関心抽出装置100を示す機能ブロック図である。図1において、関心抽出装置100は、情報提示装置200より、閲覧情報入力部101によって閲覧中の文書のURLあるいは表示内容を受ける。主題キーワード抽出部102は、閲覧情報入力部101によって入力された本文情報から文書の主題キーワードを抽出する。関心キーワード抽出部103は、本文情報と主題キーワード抽出部によって抽出された主題キーワードとからユーザの現在の関心を表すキーワードである関心キーワードを抽出して、抽出された関心キーワードとURLの組を対応付けて関心キーワード履歴格納部104に格納する。関心キーワードに応じて次の文書を検索する手段である連鎖ルールを連鎖ルール格納部105に格納する。連鎖ルール適用部106は、関心キーワード抽出部103により抽出された関心キーワードに対して連鎖ルール格納部105に格納された連鎖ルールを適用して検索クエリを生成する。推薦情報取得部107は、連鎖ルール適用部106によって生成された検索クエリを用いて次に推薦するコンテンツの候補を検索する。また、情報提示装置200は、推薦情報取得部107によって取得された推薦情報が推薦情報提示部201に提示されると、ユーザは情報選択部202によって提示された推薦情報を含め次に閲覧する情報についてユーザの入力にしたがって選択する。
次に、図2について説明する。図2は、本実施形態に係る関心抽出装置の動作を示すフローチャートである。
まず、現在ユーザが閲覧中のウェブページ(URL(t))の本文からキーワードを抽出して、主体スコアを算出して付ける(ステップS1)。本実施形態では、主体スコアを算出するために、キーワードのウェブページ中の位置を使う。例えば、タイトルや本文の前の方にあるキーワードのスコアが高い。但し、表示領域による補正も可能と考える。例えば、ウェブページの下に移動すると、元々したにある低いスコアを持っているキーワードは表示の上方に映ったら、そのキーワードのスコアが高くなる。
次に、直前の閲覧したウェブページ(URL(t-1))から現在のウェブページへの遷移に関する関心キーワードを検索して、関心スコアを算出して付ける(ステップS2)。関心キーワードの検出方法としては、例えば、本文中のあるハイパーリンクをクリックすると、そのハイパーリンクの周辺にあるキーワードは関心キーワードと見なす。関心スコアの算出方法としては、ユーザがクリックしたまたは注目したキーワード若しくはハイパーリンクに近ければ近いほど、スコアが高くなる。
次に、算出された主題スコアと関心スコアの重みに基づき、連鎖に用いるキーワードとクエリを決定する(ステップS3)。この場合、主題スコアや関心スコアを用いて、連鎖ルール格納部105に格納された連鎖ルールを参照しながら、クエリの検索方法と提示方法を定める。連鎖ルールはあとで説明する。そして、検索結果を理由付きで提示して、ウェブページのURLと関心キーワードの組を関心キーワード履歴格納部に格納して(ステップS4)、処理終了になる。ここでの理由付きに関しては、連鎖ルールの提示方法を用いて、関心キーワードを差し入れて表示することである。
次に図1および図2を用いて、本実施形態に係る関心抽出装置の動作について説明する。
まず、ユーザが情報提示装置200を用いて情報選択部202によりあるウェブページを閲覧する。閲覧情報に含まれるテキストの例を図3に示す。ここでは、1つ前のページURL(t-1)に含まれる文章のうち、「ここ」という単語を含むアンカーリンクを選択することで現在のページURL(t)を閲覧しているものとする。閲覧情報入力部は、選択されたウェブページに含まれるテキスト情報を入力する。ここで、TITLEはそのページのタイトルを、BODYはそのページの本文を意味する。
次に、主題キーワード抽出部は本文に含まれる主題キーワードを抽出し、スコアを付与する。図4に、現在閲覧中ウェブページの一つ手前のURL(t-1)の閲覧時に抽出された主題キーワードを示す。キーワードの抽出は形態素解析および固有表現抽出を用い、キーワード毎に通し番号としてのID、抽出されたキーワードのラベル、TITLE、BODYなど抽出元の出自と何文字目に出現したかを示す出現位置、抽出されたキーワードのラベル、キーワードの意味分類、およびキーワードのスコアである主題スコアが抽出・算出される。ここで、主題スコアはタイトルや本文の前の方にあるものほど高スコアとなり、またタイトル、本文両方に出現するものはさらに高いスコアが付与される。
次に、関心キーワード抽出部103は、閲覧中のページに含まれるキーワードと次のページのURLとを関心キーワードとして対応付ける。例えば、図3のURL(t-1)の本文中、「ここ」という表記はURL(t)へのハイパーリンクであるが、図5に示すようにこの周辺に存在するキーワードである「丸ロール」「ロールケーキ」「クリーム」はURL(t)に対する関心を示す語であると考えることができる。URL(t-1)からURL(t)への遷移に対応する関心キーワードの一覧を図6に示す。キーワードは主題キーワード抽出によって抽出されたキーワードを用い、キーワード毎に通し番号としてのID、抽出されたキーワードのラベル、抽出元の出自、キーワードの意味分類、および関心スコアが抽出・算出される。ここで、関心スコアはアンカーテキストの近くにあるほど高スコアとなる。これら遷移に対応するURLの組と関心キーワードは、関心キーワード履歴格納部104に格納される。
前段落の関心キーワードが関心キーワード履歴格納部に格納された状態でURL(t)のウェブページを閲覧している状況を考える。このとき、直前のURL(t-1)のページからURL(t)に移った時の関心が持続していればURL(t)のページの主題でなくても「丸ロール」や「ロールケーキ」という単語の周辺に存在する記述にも関心があると考えられる。あるいは、ページを閲覧した結果ページの主題である「XXカフェ △△川崎プラザ店」に新たな興味を抱くとも考えられる。関心キーワード抽出部103は主題スコアの高いキーワードである「XXカフェ △△川崎プラザ店」や今回辿った遷移を示す関心キーワード「丸ロール」の付近に出現するキーワードである「X○X○」および(丸ロール、X○X○)の組を、推薦情報を検索・提示するための新たな関心キーワードとして抽出する。抽出されたクエリ作成用関心キーワードは図7に示す。
その後、抽出された関心キーワードから、連鎖ルール適用部106を用いて検索クエリが生成される。連鎖ルール適用部106は、連鎖ルール格納部105に格納された連鎖ルールを用い、関心キーワードの主題スコア、関心スコア、意味分類に基づき適用可能な連鎖ルールを選択する。
図8に、連鎖ルール格納部105に格納された連鎖ルールの例を示す。各ルールの通し番号を示すルールID、キーワードの意味分類、キーワードの主題スコア、キーワードの関心スコア、選択される検索方法、および提示方法を示す。検索方法としては、具体的なウェブサービスなどの検索サービスや、対象ドメインを指定した検索などが想定される。また、提示方法は、最終的に推薦する際の見出し情報のテンプレートとなる。例えば、ルールID1については「○△はこんなお店です!」と記載されているが、○△に具体的な関心キーワードが挿入され、例えば「X○X○はこんなお店です!」のように表示される。
図6から抽出されたキーワードに関しては、例えば食べ物「丸ロール」と店舗「X○X○」の組からはルール1に基づき「X○X○ AND 丸ロール」という、店舗情報検索サービス向けのクエリが検索される。
連鎖ルール適用部106により生成された検索クエリは、推薦情報取得部107によって実際に検索が実行される。本実施形態では、ウェブサービスを用いた検索が想定されるが、関心抽出装置100自身に格納された辞書などのデータベース検索など、ウェブサービス以外の検索手段を用いても構わない。
推薦情報取得部107により取得された結果であるURLは、クエリの元となった関心キーワードと組にして関心キーワード履歴格納部104に格納される。
推薦情報取得部107により取得された結果は、連鎖ルール格納部105に格納された連鎖ルールに記載の提示方法と組にして推薦情報提示部201により情報提示装置200においてユーザに提示される。ユーザが提示内容のうち1つを選択すると、情報提示装置200の閲覧ページとして推薦結果のURLに対応するウェブページが表示される。最終的な提示内容の例を図9に示す。
本実施形態において、あるウェブページの閲覧中に推薦情報提示部201により提示される情報提示内容を選択することは、URL(t)に対応するウェブページにおいてハイパーリンクを選択する場合と同様、常に関心キーワードとURLとが組になった状態で閲覧を行うことになり、関心抽出装置100はユーザの関心を追跡しながら情報を推薦することが可能となる。
このように、ユーザがウェブページを閲覧している時に、関心情報の抽出と関心に沿った情報の推薦を行うことができる。
なお、本実施形態では、関心キーワードとして直前に閲覧したページに含まれるキーワードのみ用いたが、nページ前のキーワードはスコアを1/nなどnの関数で減衰させつつ残す、などの方法を利用してもよい。
また、閲覧情報入力部では、ウェブページの他に、現在ユーザが置かれている状況を表すキーワードを追加で入力してもよい。例えば、ウェブブラウザが携帯端末に搭載されている場合は、現在地を表すキーワードとして「川崎」などの単語を入力することが考えられる。
本実施形態では、サーバにおいて関心抽出装置100が使用され、ユーザが所有する端末において情報提示装置200が使用されることを想定しているが、これは関心抽出装置100および情報提示装置200が一体に構成されてもよい。関心抽出装置100は、CPUなどの制御装置と、ROMやRAMなどの記憶装置と、HDDなどの外部記憶装置と、ディスプレイ装置などの表示装置と、キーボード、マウスなどの入力装置とを備えた、一般的なコンピュータに適用することもできる。
また、上記実施形態の関心抽出装置は、例えば、汎用のコンピュータ装置を基本ハードウェアとして用いることでも実現することが可能である。実行されるプログラムは、上述した各機能を含むモジュール構成となっている。プログラムはインストール可能な形式又は実行可能な形式のファイルでCD-ROM、フロッピー(登録商標)ディスク、CD-R、DVD等のコンピュータで読み取り可能な記録媒体に記録されて提供しても、ROM等に予め組み込んで提供してもよい。
なお、この関心抽出装置は、例えば、汎用のコンピュータ装置を基本ハードウェアとして用いることでも実現することが可能である。すなわち、閲覧情報入力部101、主題キーワード抽出部102、関心キーワード抽出部103、連鎖ルール適用部106、推薦情報取得107、推薦情報提示部201、および情報選択部202は、上記のコンピュータ装置に搭載されたプロセッサにプログラムを実行させることにより実現することができる。このとき、関心抽出装置は、上記のプログラムをコンピュータ装置にあらかじめインストールすることで実現してもよいし、CD-ROMなどの記憶媒体に記憶して、あるいはネットワークを介して上記のプログラムを配布して、このプログラムをコンピュータ装置に適宜インストールすることで実現してもよい。また、関心キーワード履歴格納部104および連鎖ルール格納部105は、上記のコンピュータ装置に内蔵あるいは外付けされたメモリ、ハードディスクもしくはCD-R、CD-RW、DVD-RAM、DVD-Rなどの記憶媒体などを適宜利用して実現することができる。
以下に、請求項に係る発明を付記する。
第1の発明は、複数の文書を入力する入力部と、所定の文書と前記所定の文書の一つ前の文書から主題キーワードを抽出する主題キーワード抽出部と、前記一つ前の文書の主題キーワードと前記所定の文書の主題キーワードから関心キーワードを抽出する関心キーワード抽出部と、前記関心キーワードを格納する関心キーワード履歴格納部と、前記関心キーワード抽出部は、前記所定の文書を特定する情報と前記関心キーワードと前記所定の文書の主題キーワードとに基づき次にユーザが関心を示しそうな次関心キーワードを抽出し、前記次関心キーワードに基づき、前記所定の文書の次の文書を取得する取得部と、前記次の文書を提示する提示部と、を備える情報推薦装置である。
第1の発明は、複数の文書を入力する入力部と、所定の文書と前記所定の文書の一つ前の文書から主題キーワードを抽出する主題キーワード抽出部と、前記一つ前の文書の主題キーワードと前記所定の文書の主題キーワードから関心キーワードを抽出する関心キーワード抽出部と、前記関心キーワードを格納する関心キーワード履歴格納部と、前記関心キーワード抽出部は、前記所定の文書を特定する情報と前記関心キーワードと前記所定の文書の主題キーワードとに基づき次にユーザが関心を示しそうな次関心キーワードを抽出し、前記次関心キーワードに基づき、前記所定の文書の次の文書を取得する取得部と、前記次の文書を提示する提示部と、を備える情報推薦装置である。
また、第2の発明は、前記関心キーワード抽出部が前記一つ前の文書の主題キーワードから前記所定の文書に至る遷移を考慮して、前記関心キーワードを抽出する第1の発明に記載の情報推薦装置である。
また、第3の発明は、前記入力部が前記所定の文書を特定する情報に基づき文書自体を取得する第1の発明に記載の情報推薦装置である。
また、第4の発明は、前記入力部が前記所定の文書からタイトル、要約文、本文領域のみを取得する第1の発明に記載の情報推薦装置である。
また、第5の発明は、前記関心キーワード抽出部により抽出された関心キーワードの種類に基づき次のコンテンツに連鎖するための検索ルールを格納する連鎖ルール格納部と、前記関心キーワードと前記連鎖ルールに基づき検索クエリを生成する連鎖ルール適用部とをさらに備える第1の発明に記載の情報推薦装置である。
また、第6の発明は、前記提示部により提示された前記次の文書を選択する情報選択部をさらに備える第1の発明に記載の情報推薦装置である。
また、第7の発明は、前記関心キーワード抽出部が、ユーザが存在する場所やユーザの行動などユーザ自身の状況を表す追加のキーワードを追加で入力する第1の発明に記載の情報推薦装置である。
また、第8の発明は、前記関心キーワード抽出部が、予め範囲が決められた複数回前までに閲覧された文書に含まれる関心キーワードを重み付きで抽出する第1の発明に記載の情報推薦装置である。
また、第9の発明は、前記関心キーワード抽出部が、閲覧された文書を再度閲覧した場合、直前に閲覧した文書に含まれる関心キーワードに対するスコアを下げる第1の発明に記載の情報推薦装置である。
100…関心抽出装置、101…閲覧情報入力部、102…主題キーワード抽出部、103…関心キーワード抽出部、104…関心キーワード履歴格納部、105…連鎖ルール格納部、106…連鎖ルール適用部、107…推薦情報取得部、200…情報提示装置、201…推薦情報提示部、202…情報選択部、
Claims (11)
- 複数の文書を入力する入力部と、
所定の文書と前記所定の文書の一つ前の文書から主題キーワードを抽出する主題キーワード抽出部と、
前記一つ前の文書の主題キーワードと前記所定の文書の主題キーワードから関心キーワードを抽出する関心キーワード抽出部と、
前記関心キーワードを格納する関心キーワード履歴格納部と、
前記関心キーワード抽出部は、前記所定の文書を特定する情報と前記関心キーワードと前記所定の文書の主題キーワードとに基づき次にユーザが関心を示しそうな次関心キーワードを抽出し、
前記次関心キーワードに基づき、前記所定の文書の次の文書を取得する取得部と、
前記次の文書を提示する提示部と、
を備える情報推薦装置。 - 前記関心キーワード抽出部は、前記一つ前の文書の主題キーワードから前記所定の文書に至る遷移を考慮して、前記関心キーワードを抽出する請求項1記載の情報推薦装置。
- 前記入力部は、前記所定の文書を特定する情報に基づき文書自体を取得する請求項1記載の情報推薦装置。
- 前記入力部は、前記所定の文書からタイトル、要約文、本文領域のみを取得する請求項1記載の情報推薦装置。
- 前記関心キーワード抽出部により抽出された関心キーワードの種類に基づき次のコンテンツに連鎖するための検索ルールを格納する連鎖ルール格納部と、
前記関心キーワードと前記連鎖ルールに基づき検索クエリを生成する連鎖ルール適用部とをさらに備える請求項1記載の情報推薦装置。 - 前記提示部により提示された前記次の文書を選択する情報選択部をさらに備える請求項1記載の情報推薦装置。
- 前記関心キーワード抽出部は、ユーザが存在する場所やユーザの行動などユーザ自身の状況を表す追加のキーワードを追加で入力する請求項1記載の情報推薦装置。
- 前記関心キーワード抽出部は、予め範囲が決められた複数回前までに閲覧された文書に含まれる関心キーワードを重み付きで抽出する請求項1記載の情報推薦装置。
- 前記関心キーワード抽出部は、閲覧された文書を再度閲覧した場合、直前に閲覧した文書に含まれる関心キーワードに対するスコアを下げる請求項1記載の情報推薦装置。
- 文書を入力する入力ステップと、
所定の文書と前記所定の文書の一つ前の文書から主題キーワードを抽出する主題キーワード抽出ステップと、
前記一つ前の文書の主題キーワードと前記所定の文書の主題キーワードから関心キーワードを抽出する関心キーワード抽出ステップと、
前記関心キーワードを格納する関心キーワード履歴格納ステップと、
前記関心キーワード抽出ステップでは、前記文書を特定する情報と前記関心キーワードと前記文書の主題キーワードとに基づき次にユーザが関心を示しそうな次関心キーワードを抽出し、
前記次関心キーワードに基づき、前記所定の文書の次の文書を取得する取得ステップと、
前記次の文書を提示する提示ステップと、
を備える情報推薦方法。 - コンピュータに閲覧中の文書に基づく関心キーワードを抽出させる関心抽出プログラムであって、
文書を入力する入力機能と、
所定の文書と前記所定の文書の一つ前の文書から主題キーワードを抽出する主題キーワード抽出機能と、
前記一つ前の文書の主題キーワードと前記文書の主題キーワードから関心キーワードを抽出する関心キーワード抽出機能と、
前記関心キーワードを格納する関心キーワード履歴格納機能と、
前記関心キーワード抽出機能では、前記所定の文書を特定する情報と前記関心キーワードと前記所定の文書の主題キーワードとに基づき次にユーザが関心を示しそうな次関心キーワードを抽出し、
前記次関心キーワードに基づき、前記所定の文書の次の文書を取得する取得機能と、
前記次の文書を提示する提示機能と、
を備える情報推薦プログラム。
Priority Applications (1)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| US13/217,875 US20120036144A1 (en) | 2009-02-27 | 2011-08-25 | Information and recommendation device, method, and program |
Applications Claiming Priority (2)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| JP2009-046795 | 2009-02-27 | ||
| JP2009046795A JP5395461B2 (ja) | 2009-02-27 | 2009-02-27 | 情報推薦装置、情報推薦方法および情報推薦プログラム |
Related Child Applications (1)
| Application Number | Title | Priority Date | Filing Date |
|---|---|---|---|
| US13/217,875 Continuation US20120036144A1 (en) | 2009-02-27 | 2011-08-25 | Information and recommendation device, method, and program |
Publications (1)
| Publication Number | Publication Date |
|---|---|
| WO2010098178A1 true WO2010098178A1 (ja) | 2010-09-02 |
Family
ID=42665388
Family Applications (1)
| Application Number | Title | Priority Date | Filing Date |
|---|---|---|---|
| PCT/JP2010/051436 Ceased WO2010098178A1 (ja) | 2009-02-27 | 2010-02-02 | 情報推薦装置、情報推薦方法および情報推薦プログラム |
Country Status (3)
| Country | Link |
|---|---|
| US (1) | US20120036144A1 (ja) |
| JP (1) | JP5395461B2 (ja) |
| WO (1) | WO2010098178A1 (ja) |
Cited By (1)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN116661634A (zh) * | 2022-02-18 | 2023-08-29 | 腾讯科技(深圳)有限公司 | 一种互动内容的显示方法、相关装置、设备以及存储介质 |
Families Citing this family (15)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| JP5156047B2 (ja) | 2010-03-31 | 2013-03-06 | 株式会社東芝 | キーワード提示装置、方法及びプログラム |
| JP5691735B2 (ja) * | 2011-03-29 | 2015-04-01 | ソニー株式会社 | コンテンツ推薦装置、推薦コンテンツの検索方法、及びプログラム |
| KR20130065802A (ko) * | 2011-11-30 | 2013-06-20 | 삼성전자주식회사 | 키워드를 이용한 애플리케이션 추천 시스템 및 방법 |
| KR101464044B1 (ko) * | 2012-09-28 | 2014-11-20 | 주식회사 엘지유플러스 | 관심 키워드 제공 장치 및 방법 |
| GB201308541D0 (en) * | 2013-05-13 | 2013-06-19 | Qatar Foundation | Social media news portal |
| KR101387704B1 (ko) * | 2013-10-07 | 2014-04-21 | 김수현 | 과거 검색어를 이용한 추천문장 제공시스템 및 제공방법 |
| JP5522813B1 (ja) * | 2013-10-18 | 2014-06-18 | 株式会社エーエヌラボ | 情報抽出装置及び情報抽出プログラム |
| CN105912549A (zh) * | 2015-12-15 | 2016-08-31 | 乐视网信息技术(北京)股份有限公司 | 一种内容推荐方法及其装置 |
| CN107784029B (zh) * | 2016-08-31 | 2022-02-08 | 阿里巴巴集团控股有限公司 | 生成提示关键词、建立索引关系的方法、服务器和客户端 |
| JP6943113B2 (ja) | 2017-09-26 | 2021-09-29 | 富士フイルムビジネスイノベーション株式会社 | 情報処理装置及び情報処理プログラム |
| CN110059256B (zh) * | 2019-04-26 | 2023-11-07 | 北京沃东天骏信息技术有限公司 | 用于展示信息的系统、方法及装置 |
| CN112802454B (zh) * | 2020-12-31 | 2023-02-21 | 大众问问(北京)信息科技有限公司 | 一种唤醒词的推荐方法、装置、终端设备及存储介质 |
| CN113177160B (zh) * | 2021-05-25 | 2024-04-23 | 上海众源网络有限公司 | 一种推送文案生成方法、装置、电子设备及存储介质 |
| CN113360753A (zh) * | 2021-05-26 | 2021-09-07 | 平安国际智慧城市科技股份有限公司 | 基于用户历史行为的信息推荐方法、装置、设备及介质 |
| JP2023114014A (ja) * | 2022-02-04 | 2023-08-17 | 富士フイルムビジネスイノベーション株式会社 | 情報処理装置及びプログラム |
Citations (5)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| JP2001290843A (ja) * | 2000-02-04 | 2001-10-19 | Fujitsu Ltd | 文書検索装置及びその方法並びに文書検索プログラム及びそのプログラムを記録した記録媒体 |
| JP2003167907A (ja) * | 2001-12-03 | 2003-06-13 | Dainippon Printing Co Ltd | 情報提供方法およびシステム |
| JP2003242176A (ja) * | 2001-12-13 | 2003-08-29 | Sony Corp | 情報処理装置および方法、記録媒体、並びにプログラム |
| JP2007272872A (ja) * | 2006-03-08 | 2007-10-18 | Ricoh Co Ltd | 情報検索方法、情報検索装置、情報検索システム、及び情報検索プログラム |
| JP2008257655A (ja) * | 2007-04-09 | 2008-10-23 | Sony Corp | 情報処理装置及び方法、並びにプログラム |
Family Cites Families (9)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US7720723B2 (en) * | 1998-09-18 | 2010-05-18 | Amazon Technologies, Inc. | User interface and methods for recommending items to users |
| US6591261B1 (en) * | 1999-06-21 | 2003-07-08 | Zerx, Llc | Network search engine and navigation tool and method of determining search results in accordance with search criteria and/or associated sites |
| AUPR894801A0 (en) * | 2001-11-20 | 2001-12-13 | Unisearch Limited | A system and method for searching data sources |
| US20050221843A1 (en) * | 2004-03-30 | 2005-10-06 | Kimberley Friedman | Distribution of location specific advertising information via wireless communication network |
| DE602005003449T2 (de) * | 2004-07-22 | 2008-10-02 | Barefruit Ltd. | Verbesserte benutzerschnittstelle |
| US20060080292A1 (en) * | 2004-10-08 | 2006-04-13 | Alanzi Faisal Saud M | Enhanced interface utility for web-based searching |
| US7644101B2 (en) * | 2005-09-07 | 2010-01-05 | Ricoh Co., Ltd. | System for generating and managing context information |
| US7668821B1 (en) * | 2005-11-17 | 2010-02-23 | Amazon Technologies, Inc. | Recommendations based on item tagging activities of users |
| US20080288439A1 (en) * | 2007-05-14 | 2008-11-20 | Microsoft Corporation | Combined personal and community lists |
-
2009
- 2009-02-27 JP JP2009046795A patent/JP5395461B2/ja not_active Expired - Fee Related
-
2010
- 2010-02-02 WO PCT/JP2010/051436 patent/WO2010098178A1/ja not_active Ceased
-
2011
- 2011-08-25 US US13/217,875 patent/US20120036144A1/en not_active Abandoned
Patent Citations (5)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| JP2001290843A (ja) * | 2000-02-04 | 2001-10-19 | Fujitsu Ltd | 文書検索装置及びその方法並びに文書検索プログラム及びそのプログラムを記録した記録媒体 |
| JP2003167907A (ja) * | 2001-12-03 | 2003-06-13 | Dainippon Printing Co Ltd | 情報提供方法およびシステム |
| JP2003242176A (ja) * | 2001-12-13 | 2003-08-29 | Sony Corp | 情報処理装置および方法、記録媒体、並びにプログラム |
| JP2007272872A (ja) * | 2006-03-08 | 2007-10-18 | Ricoh Co Ltd | 情報検索方法、情報検索装置、情報検索システム、及び情報検索プログラム |
| JP2008257655A (ja) * | 2007-04-09 | 2008-10-23 | Sony Corp | 情報処理装置及び方法、並びにプログラム |
Cited By (1)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN116661634A (zh) * | 2022-02-18 | 2023-08-29 | 腾讯科技(深圳)有限公司 | 一种互动内容的显示方法、相关装置、设备以及存储介质 |
Also Published As
| Publication number | Publication date |
|---|---|
| JP5395461B2 (ja) | 2014-01-22 |
| US20120036144A1 (en) | 2012-02-09 |
| JP2010204735A (ja) | 2010-09-16 |
Similar Documents
| Publication | Publication Date | Title |
|---|---|---|
| JP5395461B2 (ja) | 情報推薦装置、情報推薦方法および情報推薦プログラム | |
| CN101031915B (zh) | 增强第一文档的方法和系统 | |
| CN101263493B (zh) | 用于提供搜索结果的系统和方法 | |
| CN102906744B (zh) | 无限浏览 | |
| US8001135B2 (en) | Search support apparatus, computer program product, and search support system | |
| JP5572596B2 (ja) | 検索結果内におけるプレーストコンテンツの順序付けのパーソナライズ | |
| JP5224868B2 (ja) | 情報推薦装置および情報推薦方法 | |
| US9262766B2 (en) | Systems and methods for contextualizing services for inline mobile banner advertising | |
| JP4805929B2 (ja) | インラインのコンテキストクエリを用いた検索システムおよび方法 | |
| EP3529714B1 (en) | Animated snippets for search results | |
| US7783644B1 (en) | Query-independent entity importance in books | |
| US20090144240A1 (en) | Method and systems for using community bookmark data to supplement internet search results | |
| US20130006914A1 (en) | Exposing search history by category | |
| US8484179B2 (en) | On-demand search result details | |
| US20090089278A1 (en) | Techniques for keyword extraction from urls using statistical analysis | |
| AU2004304285B2 (en) | Methods and systems for information extraction | |
| US20100114874A1 (en) | Providing search results | |
| US20130054356A1 (en) | Systems and methods for contextualizing services for images | |
| KR20070039072A (ko) | 검색 엔진에서의 결과물 기반의 광고 개인화 | |
| US20130054672A1 (en) | Systems and methods for contextualizing a toolbar | |
| US8782049B2 (en) | Keyword presenting device | |
| TWI399657B (zh) | A provider, a method of providing information, a program, and an information recording medium | |
| KR101421819B1 (ko) | 온라인 환경에서의 벌룬을 이용한 키워드 검색 결과 제공 방법 | |
| JP5416023B2 (ja) | 閲覧端末及び方法 | |
| US8131752B2 (en) | Breaking documents |
Legal Events
| Date | Code | Title | Description |
|---|---|---|---|
| 121 | Ep: the epo has been informed by wipo that ep was designated in this application |
Ref document number: 10746059 Country of ref document: EP Kind code of ref document: A1 |
|
| NENP | Non-entry into the national phase |
Ref country code: DE |
|
| 122 | Ep: pct application non-entry in european phase |
Ref document number: 10746059 Country of ref document: EP Kind code of ref document: A1 |