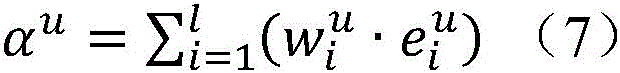Detailed Description
The present invention will be described in further detail with reference to the drawings and examples, in order to make the objects, technical solutions and advantages of the present invention more apparent. It should be understood that the detailed description is presented by way of example only and is not intended to limit the scope of the invention.
FIG. 1 is a general flow diagram of an activity and user identification method based on deep multitasking learning provided by an embodiment; fig. 2 is an overall architecture diagram of an activity and user recognition method based on deep multitasking learning provided in an embodiment, in fig. 2, conv1D and Pool1D represent a one-dimensional convolutional network layer and a one-dimensional max-pooling layer, respectively, U represents a bidirectional long-short-time memory network element, attNet represents an attention network, which outputs a weight vector w to distinguish the importance of a feature r,
representing Hadamard sum, ">
Representing the hadamard product.
Referring to fig. 1 and 2, the activity and user recognition method based on deep multitasking learning provided in the embodiment includes a data set construction stage, a hidden parameter initialization stage, and a model training stage.
Data set construction phase
The data set construction stage mainly collects sensor data, preprocesses the collected sensor data, and constructs a training data set, and the specific process is as follows:
step 1-1, acquiring sensor data of each user when different activities are performed by using a wearable sensor;
in this step, wearable sensor data is recorded as the user performs different activities. Common wearable sensors include accelerometers, gyroscopes, magnetometers, and the like. In order to ensure the recognition accuracy, the number, the type and the placement orientation of the sensors are required to be consistent when the training data set is constructed and when the training data set is actually used.
And step 1-2, carrying out outlier elimination and normalization processing on the acquired data, and dividing the processed data by utilizing a sliding window to obtain a data sample.
In this step, the processing of the acquired data mainly includes:
a) Abnormal value detection is carried out on the original sensor data, and invalid values (such as values exceeding a normal range and missing values) in the abnormal value detection are removed or mean filling is carried out.
b) Carrying out dispersion standardization processing on sensor data according to channels, so that the processed data are standardized to be within an [ -1,1] interval, and the conversion formula is as follows:
wherein X is the original value, X min To be the minimum value of the channel where the value is located, X max For the maximum value of the channel in which the value is located, x' is the value after normalization.
c) The processed data was divided using a fixed length sliding window, the sliding window length was set manually according to experience, and the overlap was set to 50%.
And step 1-3, taking each data sample, the corresponding active label and the user label as a training sample, and constructing a training data set. One training sample may be denoted (x, a, u), where x represents the data sample, a represents the active tag, and u represents the user tag.
Step 1-4, the training data set is batched according to a fixed size, and the total number of batches is N.
In this step, the batch size is manually set according to experience, and the total number of batches N is calculated as follows:
wherein M is total To train the total number of samples in the dataset, M batch Is of a batch size.
Hidden parameter initialization stage
The specific process is as follows:
step 2-1, sequentially selecting a batch of training samples from the training dataset, and repeating steps 2-2 to 2-5 for each training sample (x, a, u) in the batch.
Step 2-2, respectively processing the data sample x by using two independent convolutional neural networks in the active recognition network and the user recognition network to obtain an intermediate layer characteristic representation r of the sample a And r u 。
In this step, the two convolutional neural networks have the same network architecture and are respectively composed of three convolutional network layers and one max-pooling layer, as shown in fig. 3, wherein the convolutional operation and the max-pooling operation are performed along the time dimension. In fig. 3, conv1D and Pool1D represent a one-dimensional convolutional network layer and a one-dimensional max-pooling layer, respectively, the numbers before @ represent the size of the convolutional kernel or pooling region, the numbers after @ represent the number of generated feature maps, and ReLU represents the activation function.
Step 2-3, representing the intermediate layer characteristics as r
a And r
u The vector sequence with the length of l is expanded and is respectively input into two independent bidirectional long-short-time memory networks in the activity recognition network and the user recognition network to extract the time dependency relationship to obtain the characteristic representation vector sequence
And->
In this step, the intermediate layer features represent r a And r u The time dimension of (c) remains unchanged and the other dimensions are expanded. The two bidirectional long-short-time memory networks have the same network architecture, and each bidirectional long-short-time memory network layer comprises a bidirectional long-short-time memory network layer which is shown in a time expansion schematic diagram in fig. 4. In FIG. 4, L f And L b Respectively representing a forward long-short time memory network unit and a backward long-short time memory network unit, wherein the two long-short time memory network layers are opposite in directionThe short-time memory network layer is connected to the same output, one long-time memory network layer processes the input sequence in the forward direction, the other one processes in the backward direction, and the output can acquire the time dependence relationship between the forward direction and the backward direction at the same time.
Step 2-4, using two independent attention networks in the activity recognition network and the user recognition network to represent the feature vector sequence e
a Mapping to weight vectors
Representing the vector sequence e for the feature
u Each part is given weight; representing the feature by a vector sequence e
u Mapping to weight vector->
Representing the vector sequence e for the feature
a Each portion is given a weight.
In this step, the two attention networks have the same network architecture, and each includes a fully connected network layer, and the output of the fully connected network layer is normalized by a softmax function to obtain a weight vector, and the process is as shown in formulas (3) - (8):
ω a =AttNet a (e u ) (3)
ω u =AttNet u (e a ) (6)
wherein the method comprises the steps of,AttNet u (. Cndot.) and AttNet a (. Cndot.) represents the attention network, ω u And omega a Representing non-normalized weight vector, alpha a And alpha u Is a weighted sum of the feature representations.
Step 2-5, utilizing an activity classification output layer formed from fully-connected network layer and softmax function in the activity recognition network, according to the weighted sum alpha of characteristic representation a Obtaining an activity prediction result a'; using a user classification output layer in the user identification network, which consists of a fully connected network layer and a softmax function, a weighted sum alpha of feature representations is used u Obtaining a user prediction result u'.
In this step, the activity and user classification layer outputs probability distributions of different activity labels and different user labels, and the calculation formula is as follows:
wherein alpha is a And alpha u Representing the input of the last step, θ a And theta u Parameters representing the fully connected network layer, |a| represents the number of active labels, |u| represents the number of user labels, a ′ i Representing the probability of predicting an active tag as i, u ′ i Representing the probability of predicting the user tag as i.
And 2-6, calculating activity classification loss according to the activity prediction and the activity label for all training samples of the batch, calculating user classification loss according to the user prediction and the user label, and updating parameters of each part of the network according to the loss.
In this step, the loss is calculated using a cross entropy loss function, the calculation formula is as follows:
wherein L is a And L u All representing loss of a single sample, M batch Indicating the batch size, loss indicates the joint Loss of a batch of samples. Adam algorithm is used for network parameter update.
Step 2-7, if the specified iteration times are reached, entering step 2-8, otherwise returning to step 2-1.
And 2-8, stacking convolution kernels of the updated two convolution neural networks corresponding to the convolution network layers to form a high-order tensor, and decomposing by a Tucker to obtain an initial hidden parameter.
In this step, the convolution kernel of each convolution network layer may be represented as a d 1 ×d 2 ×d 3 The convolution kernels of the corresponding convolution network layers of the two convolution neural networks are stacked to form d by the dimension third-order tensor 1 ×d 2 ×d 3 ×d 4 (d 4 =2) a four-dimensional tensor T, which is subjected to a Tucker decomposition to obtain the initial hidden parameters, as shown in equation (14):
T=S· (1,2) R (1) · (1,2) R (2) · (1,2) R (3) · (1,2) R (4) (14)
wherein S is a v 1 ×v 2 ×v 3 ×v 4 Dimension fourth-order tensor, R (i) Is d i ×v i The dimension matrix, S and R are initial hidden parameters, R (4) Hidden parameters, S, R, specific to the identification network of the activity and the identification network of the user (1) ,R (2) And R is (3) Hidden parameters representing the sharing of an active identification network and a user identification network, subscript · (i,j) Representing coordinate axes for performing tensor dot product operations。
Model training stage
Step 3-1, sequentially selecting a batch of training samples from the training dataset, and repeating steps 3-2 to 3-3 for each training sample (x, a, u) in the batch.
Step 3-2, respectively processing the data sample x by using two convolutional neural networks sharing part of hidden parameters in the active recognition network and the user recognition network to obtain an intermediate layer characteristic representation r of the sample a And r u . The hidden parameters are stored and updated instead of the convolution kernels, specifically, in forward propagation, the hidden parameters are firstly used for generating the convolution kernels, and then the generated convolution kernels are used for carrying out convolution operation; in back propagation, hidden parameters are updated.
In this step, a corresponding convolution kernel is generated from the hidden parameter by inverse operation of the Tucker decomposition, and a convolution operation is performed using the generated convolution kernel. Wherein, part of hidden parameters are shared by the activity recognition network and the user recognition network, and when one network is trained, the updating of the shared hidden parameters also affects the convolution kernel generated by the other network, thereby realizing the cross-task sharing of knowledge.
Step 3-3, obtaining an activity prediction result a 'and a user prediction result u' according to the steps 2-3-2-5; namely, specifically comprises:
step 3-3-1, r
a And r
u Expanded into a vector sequence with the length of l, and respectively input into two independent bidirectional long-short-time memory networks in the activity recognition network and the user recognition network to obtain a characteristic representation vector sequence
And
the implementation details of the step are consistent with those of the step 2-3 in the hidden parameter initialization stage.
Step 3-3-2, using two independent attention networks of the activity recognition network and the user recognition network, e
a Mapping to weight vectors
E is
u Each part is given weight; will e
u Mapping to weight vector->
E is
a Each portion is given a weight.
The implementation details of the step are consistent with those of the step 2-4 in the hidden parameter initialization stage.
Step 3-3-3, obtaining an activity prediction result a' by using an activity classification output layer which is formed by a fully connected network layer and a softmax function in an activity recognition network; and obtaining a user prediction result u' by using a user classification output layer in the user identification network, wherein the user classification output layer consists of a fully connected network layer and a softmax function.
The implementation details of the step are consistent with those of the step 2-5 in the hidden parameter initialization stage.
And 3-4, updating parameters of each part of the network according to the steps 2-6.
In this step, for all training samples of the batch, activity classification losses are calculated according to the activity predictions and the activity labels, user classification losses are calculated according to the user predictions and the user labels, and parameters of each part of the network are updated according to the losses.
The implementation details of the step are consistent with those of the step 2-6 in the hidden parameter initialization stage.
And 3-5, if the specified training iteration times are reached, finishing training, obtaining an active recognition model and a user recognition model with determined parameters, and otherwise, returning to the step 3-1.
After the network parameters of the activity recognition model and the user recognition model are determined through the data set construction stage, the hidden parameter initialization stage and the model training stage, the activity recognition model and the user recognition model can be utilized for carrying out activity and user recognition, and the specific process is as follows:
for the acquired sensor data, performing outlier elimination and normalization processing on the data according to the steps 1-2 in the data set construction stage, and dividing the processed data to obtain a data sample;
processing the data sample by using an activity recognition model determined by the network parameters to obtain an activity recognition result;
and processing the data sample by using the user identification model determined by the network parameters to obtain a user identification result.
The invention jointly builds the activity recognition and user recognition models, utilizes hidden parameters to share information between the two models, further utilizes the commonality and the difference between the two tasks to realize mutual promotion, introduces a mutual attention mechanism, enables the two models to mutually utilize the knowledge learned by the other party to give weight to each part of the feature, thereby adapting to the change of the user and the activity scene, and has wide application prospect in the fields of health support, skill evaluation, biological recognition and the like.
The foregoing detailed description of the preferred embodiments and advantages of the invention will be appreciated that the foregoing description is merely illustrative of the presently preferred embodiments of the invention, and that no changes, additions, substitutions and equivalents of those embodiments are intended to be included within the scope of the invention.