WO2023225235A1 - Method for predicting depth map via multi-view stereo system, electronic apparatus and storage medium - Google Patents
Method for predicting depth map via multi-view stereo system, electronic apparatus and storage medium Download PDFInfo
- Publication number
- WO2023225235A1 WO2023225235A1 PCT/US2023/022791 US2023022791W WO2023225235A1 WO 2023225235 A1 WO2023225235 A1 WO 2023225235A1 US 2023022791 W US2023022791 W US 2023022791W WO 2023225235 A1 WO2023225235 A1 WO 2023225235A1
- Authority
- WO
- WIPO (PCT)
- Prior art keywords
- index field
- depth map
- index
- feature
- cost volume
- Prior art date
- Legal status (The legal status is an assumption and is not a legal conclusion. Google has not performed a legal analysis and makes no representation as to the accuracy of the status listed.)
- Ceased
Links
Classifications
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/045—Combinations of networks
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/044—Recurrent networks, e.g. Hopfield networks
- G06N3/0442—Recurrent networks, e.g. Hopfield networks characterised by memory or gating, e.g. long short-term memory [LSTM] or gated recurrent units [GRU]
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/0464—Convolutional networks [CNN, ConvNet]
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06T—IMAGE DATA PROCESSING OR GENERATION, IN GENERAL
- G06T7/00—Image analysis
- G06T7/50—Depth or shape recovery
- G06T7/55—Depth or shape recovery from multiple images
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06T—IMAGE DATA PROCESSING OR GENERATION, IN GENERAL
- G06T7/00—Image analysis
- G06T7/50—Depth or shape recovery
- G06T7/55—Depth or shape recovery from multiple images
- G06T7/593—Depth or shape recovery from multiple images from stereo images
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06V—IMAGE OR VIDEO RECOGNITION OR UNDERSTANDING
- G06V10/00—Arrangements for image or video recognition or understanding
- G06V10/70—Arrangements for image or video recognition or understanding using pattern recognition or machine learning
- G06V10/82—Arrangements for image or video recognition or understanding using pattern recognition or machine learning using neural networks
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06V—IMAGE OR VIDEO RECOGNITION OR UNDERSTANDING
- G06V20/00—Scenes; Scene-specific elements
- G06V20/60—Type of objects
- G06V20/64—Three-dimensional [3D] objects
- G06V20/647—Three-dimensional [3D] objects by matching two-dimensional images to three-dimensional objects
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06T—IMAGE DATA PROCESSING OR GENERATION, IN GENERAL
- G06T2207/00—Indexing scheme for image analysis or image enhancement
- G06T2207/20—Special algorithmic details
- G06T2207/20081—Training; Learning
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06T—IMAGE DATA PROCESSING OR GENERATION, IN GENERAL
- G06T2207/00—Indexing scheme for image analysis or image enhancement
- G06T2207/20—Special algorithmic details
- G06T2207/20084—Artificial neural networks [ANN]
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06T—IMAGE DATA PROCESSING OR GENERATION, IN GENERAL
- G06T2207/00—Indexing scheme for image analysis or image enhancement
- G06T2207/30—Subject of image; Context of image processing
- G06T2207/30248—Vehicle exterior or interior
- G06T2207/30252—Vehicle exterior; Vicinity of vehicle
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04N—PICTORIAL COMMUNICATION, e.g. TELEVISION
- H04N13/00—Stereoscopic video systems; Multi-view video systems; Details thereof
- H04N2013/0074—Stereoscopic image analysis
- H04N2013/0081—Depth or disparity estimation from stereoscopic image signals
Definitions
- the disclosure relates to a three-dimensional (3D) reconstruction technology, and in particular to a method for predicting depth map via the multi-view stereo system, an electronic apparatus and a non-transitory computer readable storage medium.
- Multi-view stereo aims to recover dense 3D geometry from multiple images captured from different viewpoints with calibrated cameras. It is a fundamental problem in computer vision and has wide applications ranging from autonomous driving, remote sensing, augmented reality, to robotics. Following the seminal MVSNet, many learning-based methods have been proposed, achieving great improvements against their traditional counterparts, in terms of accuracy or efficiency. [0003] Most of learning-based MVS methods rely on traditional plane-sweeping approach to generate a cost volume by comparing the convolutional neural network (CNN) features of reference image and source images at several depth planes, and then apply 2D or 3D convolutional encoder-decoder architectures to aggregate and regularize the cost volume.
- CNN convolutional neural network
- the 2D CNN methods use multi-level features as the skip connections to help decode the cost volume for depth regression. Even though the skip-connections improve the depth maps, they weaken the role of cost volume and the geometry knowledge embedded therein to some extent. Hence, 2D CNN methods suffer from degraded generalization when testing on unseen domains.
- the 3D CNN methods use soft-argmin to regress the depth map as the expectation from the cost volume distribution, and hence cannot predict the best candidate but instead an averaged one when dealing with a flat or multi-modal distribution caused by textureless, repeated, or occluded regions, etc.
- the disclosure provides a method for predicting depth map via a multi-view stereo system, electronic apparatus and storage medium to predict the depth accurately.
- a method for predicting depth map via a multi-view stereo system performed on an electronic apparatus comprises: extracting source features from a plurality of source images, and extracting an aggregated reference feature from a reference image, wherein the reference image is one of a plurality of captured images of the same scene with different camera poses, and the source images are remaining captured images; constructing a cost volume based on the source features and the aggregated reference feature; performing an iterative estimation having a plurality of iterations based on the cost volume to obtain a series of index fields, the iterative estimation comprising: for each of iterations, predicting a residual value through a recurrent neural network by using an index field obtained last time, and obtaining an index field of current iteration according to the residual value and the index field obtained last time; and estimating a first depth map based on the index field obtained finally in the series of index fields.
- An electronic apparatus comprises: a storage, configured to store a program; and a processor, coupled to the storage, and configured to execute the program to: extract source features from a plurality of source images, and extracting an aggregated reference feature from a reference image, wherein the reference image is one of a plurality of captured images of the same scene with different camera poses, and the source images are remaining captured images; construct a cost volume based on the source features and the aggregated reference feature; perform an iterative estimation having a plurality of iterations based on the cost volume to obtain a series of index fields, the iterative estimation comprising: for each of iterations, predicting a residual value through a recurrent neural network by using an index field obtained last time, and obtaining an index field of current iteration according to the residual value and the index field obtained last time; and estimate a first depth map based on the index field obtained finally in the series of index fields.
- FIG. 1 is a block diagram of a user equipment according to an embodiment of the disclosure.
- FIG. 1 is a block diagram of a user equipment according to an embodiment of the disclosure.
- FIG. 2 is a flowchart of a method for predicting depth map via the multi-view stereo system according to an embodiment of the disclosure.
- FIG.3 is a schematic diagram illustrating feature extraction and cost volume construction according to an embodiment of the disclosure.
- FIG. 4 is a schematic diagram illustrating depth prediction using iterative estimation according to an embodiment of the disclosure.
- FIG.5 is a schematic diagram illustrating depth prediction using iterative estimation and residual pose estimation according to an embodiment of the disclosure.
- FIG. 1 is a block diagram of a user equipment according to an embodiment of the disclosure. Please refer to FIG. 1, an electronic apparatus 100 is an apparatus having an arithmetic capability.
- the electronic apparatus 100 may be, for example, a server, a desktop computer, a laptop computer, a network computer, a workstation, a personal digital assistant (PDA), a tablet personal computer (PC), and the like.
- the electronic apparatus 100 comprises a processor 110 and a storage 120.
- the processor 110 is coupled to the storage 120.
- the processor 110 is, for example, a central processing unit (CPU), a physics processing unit (PPU), a programmable microprocessor, an embedded control chip, a digital signal processor (DSP), an application specific integrated circuit (ASIC), or other similar devices.
- CPU central processing unit
- PPU physics processing unit
- DSP digital signal processor
- ASIC application specific integrated circuit
- the storage 120 is, for example, any type of fixed or removable random-access memory (RAM), read-only memory (ROM), flash memory, hard disk drive, other similar apparatuses, or a combination of the apparatuses.
- the storage 120 stores a plurality of code fragments, and the code fragments are executed by the processor 110 after being installed, so as to execute the method for predicting depth map via the multi-view stereo system.
- depth prediction is implemented by learning to optimize the cost volume directly to iteratively estimate a series of index fields. To facilitate the optimization, the cost volume in pixel- and frame levels are improved respectively.
- FIG. 2 is a flowchart of a method for predicting depth map via the multi-view stereo system according to an embodiment of the disclosure. In the embodiment, the method for predicting depth map would be roughly divided into feature extraction, cost volume construction and depth estimation. Details will be discussed below. [0022] Please refer to FIG. 1 and FIG. 2.
- the processor 110 extracts source features from a plurality of source images, and extracts an aggregated reference feature from a reference image.
- One of the captured images is used as the reference image, and other remaining captured images are used as the source images.
- the reference image is the first captured image denoted by I 0 and the source images are other captured images I 1 to I N-1 denoted by .
- FIG.3 is a schematic diagram illustrating feature extraction and cost volume construction according to an embodiment of the disclosure. Please refer to FIG.3, a feature extractor 310 is configured for the source features, and a feature extractor 320 and a transformer layer 330 are configured for the reference image.
- the feature extractors 310 and 320 are based on PairNet.
- the PairNet is a lightweight feature pyramid network (FPN) on top of first fourteen layers of MnasNet.
- the transformer layer 330 may be implemented by four-head self- attention with positional encoding.
- the feature extractor 310 is used for extracting source features from the source images I S .
- the feature extractor 320 is used for extracting a matching feature f 0 from the reference image I 0 and the transformer layer 330 is used to construct the aggregated reference feature based on the matching feature f 0 .
- a fusion layer G is provided to aggregate 1/2 scale feature f 0,2 and other features (f 0,4 , f 0,8 , f 0,16 ) into the matching feature f 0 at 1/4 scale, as: .
- the fusion layer G is a sequence of operation of Conv 3 ⁇ 3 function, batch normalization, rectified linear unit (ReLU), and Conv 1 ⁇ 1 .
- the feature extractor 310 (with shared weights as that for I 0 ) is also applied to source images I S to extract a set of source features f S .
- the transformer layer 330 is used to leverage global long-range information to better guide the feature matching.
- the final output (reference feature ) of the transformer layer 330 contains both local and global information, which are balanced by the scalar weight ⁇ ⁇ , to enhance the following cost volume construction.
- the transformer layer 330 is only applied to the reference image I 0 , while the source features still possess the local representations from the feature extractor 310.
- the asymmetric employment of the transformer layer 330 provides the capability to better balance the high-frequency features (by high-pass CNNs) and the low-frequency features by self-attention.
- the high-frequency features are beneficial to image matching at local and structural regions, while the low-frequency ones, with noisy information suppressed by spatial smoothing (serving as a low-pass filter) of the transformer layer 330, provides more global context cues for robust matching, especially for the areas full of low-texture, repeated patterns, and occlusion, etc.
- the network architecture containing the feature extractor 320 and the transformer layer 330 can learn where to rely on global features over local features, and vice versa.
- the source features f S and the aggregated reference feature are used to construct the cost volume C 0 .
- dmin and dmax are the near and far planes of the 3D frustum respectively.
- R 0.i represents a rotation matrix between the reference image I0 and the source images I i
- t 0,i represents a translation vector between the reference image I 0 and the source images I i .
- ⁇ 1 represents the relative pose the reference image I0 and the source image I 1
- ⁇ 2 represents the relative pose the reference image I0 and the source image I 2
- ⁇ N-1 represents the relative pose the reference image I 0 and the source image I N-1 .
- a cost map is computed by warping source feature fi into the reference image I0 and calculating the similarity between the aggregated reference feature and the warped feature .
- a homography is used as a backward 2D grid sampling to generate the warped feature .
- B0 represents a set of depth planes, represents the original set of relative poses.
- a pixel in the reference image I0 will be warped to its counterpart in source image I i as equation (2): [0031] Then the warped feature is bilinearly sampled from as Given the warped feature and the aggregated reference feature , the cost volume is formulated as equation (3): [0032] The cost volume C 0 is constructed for all depth planes , resulting in a 3D tensor, denoted as [0033] After constructing the cost volume C 0 , in step S215, the processor 110 performs an iterative estimation having a plurality of iterations based on the cost volume C 0 to obtain a series of index fields.
- step S220 the processor 110 estimates a first depth map based on the index field obtained finally in the series of index fields.
- a residual value is predicted through a recurrent neural network (ex. gated recurrent unit (GRU)) by using an index field obtained last time, and an index field of current iteration is obtained according to the residual value and the index field obtained last time.
- GRU gated recurrent unit
- an updated index filed for the current iteration is obtained using the predicted residual value and the initial index field.
- an updated index filed for the current iteration is obtained using the predicted residual value and the index field from last iteration.
- the index field of the current iteration is obtained by adding the residual value and the index field obtained last time.
- the processor 110 learns to index the cost volume C 0 by approaching correct depth planes per pixel via an index field.
- the proposed iterative estimate of index field (a grid of indices to identify the depth planes) enables the learning to be anchored at the cost volume domain. Specifically, it recurrently predicts the residual value, so as to retrieve cost features for the next iteration in a descent direction of cost volume, but also to directly index (i.e., sampling via linear interpolation) depth planes to render a depth map, which is iteratively optimized to approach the ground truth depth, making the system end-to-end trainable.
- FIG. 4 is a schematic diagram illustrating depth prediction using iterative estimation according to an embodiment of the disclosure.
- SGM semi-global matching
- the architecture for predicting depth map further includes a context feature network 410 and a GRU-based module 420.
- the context feature network 410 is used to extract a context feature from the reference image I 0 .
- the context feature network 410 consists of several residual blocks.
- the GRU-based module 420 is used to implicitly optimize the cost volume C 0 .
- a sequence of index fields are estimated by unrolling the optimization problem to iterative updates.
- a four-layer matching pyramid is built by repeated pooling the cost volume C 0 along the depth dimension with kernel 2.
- lookup operator L is defined for retrieving cost features from the cost volume C 0 according to the index field obtained last time. For example, in the iteration 1, the lookup operator L retrieves cost features from the cost volume C 0 according to the index field , in the iteration 2 the lookup operator L retrieves cost features from the cost volume C 0 according to the index field and in the iteration T the lookup operator L retrieves cost features from the cost volume C 0 according to the index field .
- the index field , the retrieved cost features and the context feature are concatenated, and fed into the GRU module 420, together with a latent hidden state h t .
- the GRU module 420 outputs a residual value ⁇ t-1 and a new hidden state h t+1 :
- the first depth map D T at iteration T is estimated by sampling the depth hypotheses via linear interpolation given the index field ⁇ T obtained finally.
- a upsampling operator U (ex. a convex combination of a 3 ⁇ 3 neighbors) is used to upsample the index field to full resolution.
- weight mask is predicted from the hidden state ht using two convolutional layers and softmax is performed over the weights of those 9 neighbors.
- the final high resolution index field (upsampled index field ) is obtained by taking a weighted combination over the 9 neighbors, and reshaping to the resolution H ⁇ W.
- Convex combination can be implemented using the einsum function in PyTorch.
- a set of depth planes is used to construct the cost volume C 0 .
- a small M 0 helps reduce the computation and space.
- the spatial upsampling is performed for the depth planes B 0 to obtain depth planes .
- the depth index fields are adjusted by a scale .
- a similar weighted summation is applied along the depth dimension when sampling depth from depth planes B 1 .
- another mask W 1 ⁇ predicted from the hidden state using three convolutional layers, and further reshaped to .
- the iterative estimate of the index field enables the learning to be directly anchored at the cost volume domain.
- This indexing paradigm differentiates our approach from other depth estimation methods, such as the convolution-based depth regression which fuses cost volume and the skipped multi-level features by 2D CNNs, or soft-argmin based depth regression after cost volume aggregation and regularization by 3D CNNs.
- an accurate cost volume benefits the GRU-based iterative optimization.
- the quality of the generated cost volume C 0 is not only determined by the aggregated reference feature and the source features f S (for which an asymmetric employment of the transformer layer is proposed), but also by the homography warping.
- FIG.5 is a schematic diagram illustrating depth prediction using iterative estimation and residual pose estimation according to an embodiment of the disclosure.
- the embodiment shown in FIG. 5 is based on the architecture of FIG. 4.
- the system architecture including feature extractors 310 and 320, the transformer layer 330, context feature extractor 410, GRU-based iterative optimization layers 420, and the residual pose network 520, etc. are trained to minimize the loss between the predicted depth maps and the ground truth depth.
- a residual pose network 520 is incorporated to correct the relative poses. This essentially rectifies the cost volume in the frame-level. Another round of GRU-based iterative updates will be performed based on the new cost volume and the depth maps will be predicted as the final output. [0046] After estimating the first depth map D T (for details, please refer to FIG.4), an updated cost volume C1 is constructed based on a residual pose adjusted by the first depth map DT.
- the iterative estimation based on the updated cost volume C 1 is re-performed to obtain another series of index fields and a second depth map is estimated based on the index field ( ⁇ " T ) obtained finally in the another series of index fields.
- the evaluation of the second depth map is analogous to the evaluation of the first depth map D T .
- the source images I S are warped respectively to obtain a plurality of warped source images (i.e., warped , and the residual pose network 520 is used to encode the reference image I 0 and the warped source images with at least one of the first depth map DT, a camera pose (i.e. the original relative poses ) and a ground truth depth , and obtaining the residual pose .
- the residual pose network 520 can be implemented using an image-net pre-trained residual neural network (ResNet) backbone.
- ResNet residual neural network
- the input to the residual pose network 520 is the concatenated result obtained by concatenating the reference image I 0 and warped source images , and the output is an axis-angle representation, which is further converted to a residual rotation matrix (residual pose) for an updated relative pose ⁇ .
- the collection of updated poses is used to implement an updated homography ( , ), and a more accurate cost volume, i.e. updated cost volume C 1 is obtained using the updated homography based on the equations (2) and (3).
- updated cost volume C 1 is obtained using the updated homography based on the equations (2) and (3).
- the iterative estimation is re-performed based on the updated cost volume C 1 to obtain another series of index fields. Similar to that described in shown in FIG.4, an initial value is determined from the updated cost volume C 1 by the sof-argmin function as the initial index field .
- T iterative updates, t 1, 2, ...
- a residual value is obtained through the GRU-based module 420 by inputting the cost features, retrieved from the updated cost volume C 1 according to the index field ⁇ " t-1 obtained last time, and the context feature . Afterwards, the index field ⁇ " t is estimated by adding the residual value and the index field obtained last time. [0050] Extensive experiments on real-world MVS datasets are conducted to show that the disclosure achieves state-of-the-art performance in terms of both within-dataset evaluation and cross-dataset generalization. [0051] The disclosure is implemented in PyTorch, and trained end-to-end with a mini-batch size of 8 per NVIDIA RTX A6000 GPU.
- the AdamW optimizer is used and gradients are clipped to the range [ ⁇ 1, 1].
- the same hyperparameters are adopted for the context network and 3-level GRU architecture.
- the network architecture of the disclosure is trained for 20 epochs, with an initial learning rate of 1e-4 and decayed by half at epoch 4 th and 8 th , respectively.
- the baselines PairNet and IterMVS are trained on the same training samples of ScanNet for 20 epochs, using the official codes and Adam Optimizer.
- the suggested learning rate scheduler in their paper is used.
- embodiments of the disclosure provide a method for predicting depth map via multi-view stereo system, an electronic apparatus and a storage medium.
- the disclosure estimates the depth maps from a set of posed multi-view images (one as the reference and others as the sources images), and exploits learning-to-optimize paradigm that iteratively indexes a plane- sweeping cost volume and regresses depth maps via convolutional GRUs.
- the cost volume construction is further improved via the incorporation of a transformer block to the reference image and a residual pose network to correct the relative poses. [0053] Since the cost volume plays a paramount role in encoding the multi-view geometry, the disclosure aims to improve its construction both in pixel- and frame-levels.
- a transformer layer is introduced to the reference image (but not to the source images) to break the symmetry of the Siamese network (which is typically used in MVS to extract image features).
- Siamese network which is typically used in MVS to extract image features.
- Such an asymmetric volume allows the network to extract global features from the reference image to predict its depth map.
- a residual pose network is incorporated to correct the relative poses. This essentially rectifies the cost volume in the frame-level.
Landscapes
- Engineering & Computer Science (AREA)
- Theoretical Computer Science (AREA)
- Physics & Mathematics (AREA)
- General Physics & Mathematics (AREA)
- Evolutionary Computation (AREA)
- Health & Medical Sciences (AREA)
- Artificial Intelligence (AREA)
- Computing Systems (AREA)
- General Health & Medical Sciences (AREA)
- Software Systems (AREA)
- Data Mining & Analysis (AREA)
- Computational Linguistics (AREA)
- Mathematical Physics (AREA)
- General Engineering & Computer Science (AREA)
- Life Sciences & Earth Sciences (AREA)
- Biomedical Technology (AREA)
- Biophysics (AREA)
- Molecular Biology (AREA)
- Computer Vision & Pattern Recognition (AREA)
- Multimedia (AREA)
- Medical Informatics (AREA)
- Databases & Information Systems (AREA)
- Image Analysis (AREA)
- Image Processing (AREA)
Abstract
A method for predicting depth map via multi-view stereo system, an electronic apparatus and a storage medium are provided. The method for predicting depth maps via the multi-view stereo system performed on the electronic apparatus comprises: extracting source features from source images, and extracting an aggregated reference feature from a reference image; constructing a cost volume based on the source features and the aggregated reference feature; performing an iterative estimation having multiple iterations based on the cost volume to obtain a series of index fields, the iterative estimation comprising: for each iteration, predicting a residual value through a gated recurrent neural network by using the last index field, and obtaining the current index field according to the residual value and the last index field; and estimating a first depth map based on the final index field.
Description
METHOD FOR PREDICTING DEPTH MAP VIA MULTI-VIEW STEREO SYSTEM, ELECTRONIC APPARATUS AND STORAGE MEDIUM CROSS-REFERENCE TO RELATED APPLICATION This application claims the priority benefit of US provisional application serial no. 63/343,910, filed on May 19, 2022. The entirety of the above-mentioned patent application is hereby incorporated by reference herein and made a part of this specification. Technical Field [0001] The disclosure relates to a three-dimensional (3D) reconstruction technology, and in particular to a method for predicting depth map via the multi-view stereo system, an electronic apparatus and a non-transitory computer readable storage medium. Related Art [0002] Multi-view stereo (MVS) aims to recover dense 3D geometry from multiple images captured from different viewpoints with calibrated cameras. It is a fundamental problem in computer vision and has wide applications ranging from autonomous driving, remote sensing, augmented reality, to robotics. Following the seminal MVSNet, many learning-based methods have been proposed, achieving great improvements against their traditional counterparts, in terms of accuracy or efficiency. [0003] Most of learning-based MVS methods rely on traditional plane-sweeping approach to generate a cost volume by comparing the convolutional neural network (CNN) features of reference image and source images at several depth planes, and then apply 2D or 3D convolutional encoder-decoder architectures to aggregate and regularize the cost volume. [0004] The 2D CNN methods use multi-level features as the skip connections to help decode the cost volume for depth regression. Even though the skip-connections improve the depth maps,
they weaken the role of cost volume and the geometry knowledge embedded therein to some extent. Hence, 2D CNN methods suffer from degraded generalization when testing on unseen domains. [0005] The 3D CNN methods use soft-argmin to regress the depth map as the expectation from the cost volume distribution, and hence cannot predict the best candidate but instead an averaged one when dealing with a flat or multi-modal distribution caused by textureless, repeated, or occluded regions, etc. Therefore, when this situation happens, the soft-argmin cannot well classify to target the best candidate, but instead gives an average prediction, by aggregating the unseen best candidate, the worst ones and the ones in the middle. [0006] Therefore, how to improve the accuracy and generalization ability of the multi-view stereo is one of the problems to be solved at present. SUMMARY OF INVENTION [0007] The disclosure provides a method for predicting depth map via a multi-view stereo system, electronic apparatus and storage medium to predict the depth accurately. [0008] A method for predicting depth map via a multi-view stereo system performed on an electronic apparatus according to the disclosure, comprises: extracting source features from a plurality of source images, and extracting an aggregated reference feature from a reference image, wherein the reference image is one of a plurality of captured images of the same scene with different camera poses, and the source images are remaining captured images; constructing a cost volume based on the source features and the aggregated reference feature; performing an iterative estimation having a plurality of iterations based on the cost volume to obtain a series of index fields, the iterative estimation comprising: for each of iterations, predicting a residual value through a recurrent neural network by using an index field obtained last time, and obtaining an index field of current iteration according to the residual value and the index field obtained last time; and estimating a first depth map based on the index field obtained finally in the series of
index fields. [0009] An electronic apparatus comprises: a storage, configured to store a program; and a processor, coupled to the storage, and configured to execute the program to: extract source features from a plurality of source images, and extracting an aggregated reference feature from a reference image, wherein the reference image is one of a plurality of captured images of the same scene with different camera poses, and the source images are remaining captured images; construct a cost volume based on the source features and the aggregated reference feature; perform an iterative estimation having a plurality of iterations based on the cost volume to obtain a series of index fields, the iterative estimation comprising: for each of iterations, predicting a residual value through a recurrent neural network by using an index field obtained last time, and obtaining an index field of current iteration according to the residual value and the index field obtained last time; and estimate a first depth map based on the index field obtained finally in the series of index fields. [0010] Based on the above description, the disclosure exploits a recurrent neural network to iteratively optimize a final index fields obtained based on the cost volume for depth regression. Accordingly, the depth can be predicted via learning to recurrently index an asymmetric cost volume, leading to improve accuracy and generalization. BRIEF DESCRIPTION OF DRAWINGS [0011] The accompanying drawings are included to provide a further understanding of the invention, and are incorporated in and constitute a part of this specification. The drawings illustrate embodiments of the invention and, together with the description, serve to explain the principles of the invention. [0012] FIG. 1 is a block diagram of a user equipment according to an embodiment of the disclosure.
[0013] FIG. 2 is a flowchart of a method for predicting depth map via the multi-view stereo system according to an embodiment of the disclosure. [0014] FIG.3 is a schematic diagram illustrating feature extraction and cost volume construction according to an embodiment of the disclosure. [0015] FIG. 4 is a schematic diagram illustrating depth prediction using iterative estimation according to an embodiment of the disclosure. [0016] FIG.5 is a schematic diagram illustrating depth prediction using iterative estimation and residual pose estimation according to an embodiment of the disclosure. DESCRIPTION OF EMBODIMENTS [0017] FIG. 1 is a block diagram of a user equipment according to an embodiment of the disclosure. Please refer to FIG. 1, an electronic apparatus 100 is an apparatus having an arithmetic capability. The electronic apparatus 100 may be, for example, a server, a desktop computer, a laptop computer, a network computer, a workstation, a personal digital assistant (PDA), a tablet personal computer (PC), and the like. [0018] The electronic apparatus 100 comprises a processor 110 and a storage 120. The processor 110 is coupled to the storage 120. The processor 110 is, for example, a central processing unit (CPU), a physics processing unit (PPU), a programmable microprocessor, an embedded control chip, a digital signal processor (DSP), an application specific integrated circuit (ASIC), or other similar devices. [0019] The storage 120 is, for example, any type of fixed or removable random-access memory (RAM), read-only memory (ROM), flash memory, hard disk drive, other similar apparatuses, or a combination of the apparatuses. The storage 120 stores a plurality of code fragments, and the code fragments are executed by the processor 110 after being installed, so as to execute the method for predicting depth map via the multi-view stereo system.
[0020] In the following embodiments, depth prediction is implemented by learning to optimize the cost volume directly to iteratively estimate a series of index fields. To facilitate the optimization, the cost volume in pixel- and frame levels are improved respectively. In the pixel level, a transformer layer is asymmetrically applied to the reference view (but not to source views) to build an asymmetric cost volume to store more accurate matching similarity cues. In the frame level, a residual pose network is provided to rectify the camera poses, which are usually obtained via Visual SLAM and inevitably contain noise, to more accurately backward warp the reference features to match its counterparts in source views. [0021] FIG. 2 is a flowchart of a method for predicting depth map via the multi-view stereo system according to an embodiment of the disclosure. In the embodiment, the method for predicting depth map would be roughly divided into feature extraction, cost volume construction and depth estimation. Details will be discussed below. [0022] Please refer to FIG. 1 and FIG. 2. In step S205, the processor 110 extracts source features from a plurality of source images, and extracts an aggregated reference feature from a reference image. In one embodiment, at least one imaging sensor (ex. calibrated camera) is used to capture a set of captured images from different viewpoints of the same scene with known camera poses, and the set of captured images is denoted by I={I0, I1, I2, …, IN-2, IN-1}. One of the captured images is used as the reference image, and other remaining captured images are used as the source images. For example, the reference image is the first captured image denoted by I0 and the source images are other captured images I1 to IN-1 denoted by . Then, feature extraction is
 performed to extract source features (denoted by fS) from the source images IS, and extract the aggregated reference feature (denoted by ) from the reference image I0.
 [0023] Next, in step S210, the processor 110 constructs a cost volume based on the source features and the aggregated reference feature. In one embodiment, the cost volume is defined on a 3D view frustum attached to the camera in perspective projection, and it is generated by plane-
sweep stereo. [0024] FIG.3 is a schematic diagram illustrating feature extraction and cost volume construction according to an embodiment of the disclosure. Please refer to FIG.3, a feature extractor 310 is configured for the source features, and a feature extractor 320 and a transformer layer 330 are configured for the reference image. In one embodiment, the feature extractors 310 and 320 are based on PairNet. The PairNet is a lightweight feature pyramid network (FPN) on top of first fourteen layers of MnasNet. The transformer layer 330 may be implemented by four-head self- attention with positional encoding. The feature extractor 310 is used for extracting source features from the source images IS. The feature extractor 320 is
 used for extracting a matching feature f0 from the reference image I0 and the transformer layer 330 is used to construct the aggregated reference feature based on the matching feature f0.
 [0025] Specifically, in one embodiment, the reference image is spatially scaled down
 until 1/32 scale, and recovered up to 1/2 scale, resulting in multi-scale features
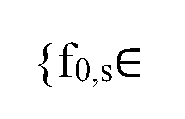 (s=2, 4, 8, 16 and F0=32 for feature channels). In the feature extractor 320, a
 fusion layer G is provided to aggregate 1/2 scale feature f0,2 and other features (f0,4, f0,8, f0,16) into the matching feature f0 at 1/4 scale, as: . The fusion layer G is
 a sequence of operation of Conv3×3 function, batch normalization, rectified linear unit (ReLU), and Conv1×1. Herein, ↓x and ↑x are downsampling and upsampling by scale x respectively,
 is concatenation along channel dimension, and with F1=128. Similarly, the
 feature extractor 310 (with shared weights as that for I0) is also applied to source images IS to extract a set of source features fS. [0026] Besides the local pixel-wise features (matching feature f0) extracted from feature extractor 320, the transformer layer 330 is used to leverage global long-range information to better guide the feature matching. The transformer layer 330 is applied to the matching feature (local
feature) f0 of the reference image I0, to construct the aggregated reference feature
 as equation (1):

 where σ(∙) is the softmax operator, ωα is a learned scalar weight that is initialized to zero, and WQ, WK and WV are the projections matrices for query, key and values, with h=4 for multi- head attention.
 and
 . [0027] The final output (reference feature
 ) of the transformer layer 330 contains both local and global information, which are balanced by the scalar weight ωα, to enhance the following cost volume construction. [0028] The transformer layer 330 is only applied to the reference image I0, while the source features
 still possess the local representations from the feature extractor 310. The asymmetric employment of the transformer layer 330 provides the capability to better balance the high-frequency features (by high-pass CNNs) and the low-frequency features by self-attention. The high-frequency features are beneficial to image matching at local and structural regions, while the low-frequency ones, with noisy information suppressed by spatial smoothing (serving as a low-pass filter) of the transformer layer 330, provides more global context cues for robust matching, especially for the areas full of low-texture, repeated patterns, and occlusion, etc. Therefore, the network architecture containing the feature extractor 320 and the transformer layer 330 can learn where to rely on global features over local features, and vice versa. [0029] Next, the source features fS and the aggregated reference feature are used to
 construct the cost volume C0. In one embodiment, the cost volume C0 is generated by running the traditional plane-sweep stereo which uniformly samples M0=64 depth hypotheses in the inverse depth space, s.t.1/d ~ U(dmin, dmax). Here, dmin and dmax are the near and far planes of the
3D frustum respectively. [0030] For a given depth hypothesis d and known camera intrinsic matrices K={Ki} (i=0, 1, 2, …, N-1) and original relative poses between the reference image I0 and the
 source images Ii. Herein, R0.i represents a rotation matrix between the reference image I0 and the source images Ii, and t0,i represents a translation vector between the reference image I0 and the source images Ii.
 is a collection of . θ1 represents the relative pose the
 reference image I0 and the source image I1, θ2 represents the relative pose the reference image I0 and the source image I2, …, θN-1 represents the relative pose the reference image I0 and the source image IN-1. A cost map is computed by warping source feature fi into the reference image I0 and calculating the similarity between the aggregated reference feature and the warped feature .

 A homography is used as a backward 2D grid sampling to generate the warped feature
 . Here, B0 represents a set of depth planes,
 represents the original set of relative poses. Specifically, a pixel in the reference image I0 will be warped to its counterpart in

 source image Ii as equation (2):
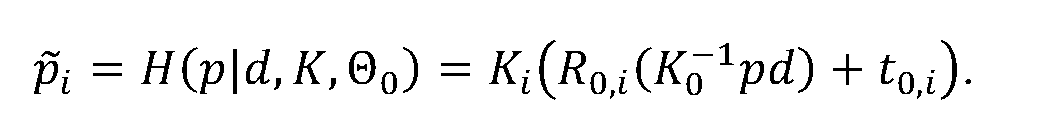 [0031] Then the warped feature
 is bilinearly sampled from as Given the

 warped feature
 and the aggregated reference feature
 , the cost volume is formulated as equation (3):
 [0032] The cost volume C0 is constructed for all depth planes ,
 resulting in a 3D tensor, denoted as
 [0033] After constructing the cost volume C0, in step S215, the processor 110 performs an iterative estimation having a plurality of iterations based on the cost volume C0 to obtain a series
of index fields. Then, in step S220, the processor 110 estimates a first depth map based on the index field obtained finally in the series of index fields. In the iterative estimation, for each of iterations, a residual value is predicted through a recurrent neural network (ex. gated recurrent unit (GRU)) by using an index field obtained last time, and an index field of current iteration is obtained according to the residual value and the index field obtained last time. For example, in the first iteration, an updated index filed for the current iteration is obtained using the predicted residual value and the initial index field. In each of other iterations except the first iteration, an updated index filed for the current iteration is obtained using the predicted residual value and the index field from last iteration. In one embodiment, the index field of the current iteration is obtained by adding the residual value and the index field obtained last time. [0034] In the embodiment, the processor 110 learns to index the cost volume C0 by approaching correct depth planes per pixel via an index field. The proposed iterative estimate of index field (a grid of indices to identify the depth planes) enables the learning to be anchored at the cost volume domain. Specifically, it recurrently predicts the residual value, so as to retrieve cost features for the next iteration in a descent direction of cost volume, but also to directly index (i.e., sampling via linear interpolation) depth planes to render a depth map, which is iteratively optimized to approach the ground truth depth, making the system end-to-end trainable. [0035] FIG. 4 is a schematic diagram illustrating depth prediction using iterative estimation according to an embodiment of the disclosure. In the embodiment, in order to optimize the dense stereo matching problem, semi-global matching (SGM) is adopted. In SGM, the cost volume C0 is iteratively aggregated by summing the costs (of all 1D minimum cost paths that end in pixel p at disparity d) when traversing from pixel p-r to pixel p in a direction r (out of sixteen directions) and the best disparity at each pixel p is given by d*(p)=argmind(C’(p, d)), with C’ being the aggregated cost volume. Similar to SGM, in the embodiment, the argmin is replaced with softargmin when predicting the disparity from the cost volume C0, but still i) the update direction
r when traversing from pixel p-r to p needs to be predefined, and ii) the softargmin focuses on measuring the distance of the expectation of disparity map to the ground truth disparity, and hence cannot handle multi-modal distributions in C0 well. [0036] Please refer FIG.4, the architecture for predicting depth map further includes a context feature network 410 and a GRU-based module 420. The context feature network 410 is used to extract a context feature from the reference image I0. For example, the context feature
 network 410 consists of several residual blocks. And the GRU-based module 420 is used to implicitly optimize the cost volume C0. A sequence of index fields are estimated by unrolling the optimization problem to iterative updates. [0037] The GRU-based module 420 estimates a series of index fields in
 a plurality of iterations from an initial index field . Specifically, before performing the
 iterations, an initial value is determined from the cost volume C0 by sof-argmin function as the initial index field
 . Then at each iteration t (assuming T iterative updates, t=1, 2, ... , T), the index field is estimated as a grid of indices to iteratively better approach (i.e., closer to the ground truth) depth planes having a lower matching cost. [0038] In one embodiment, a four-layer matching pyramid is built by repeated pooling
 the cost volume C0 along the depth dimension with kernel 2. To index the matching pyramid, lookup operator L is defined for retrieving cost features from the cost volume C0 according
 to the index field obtained last time. For example, in the iteration 1, the lookup operator L retrieves cost features from the cost volume C0 according to the index field , in the iteration
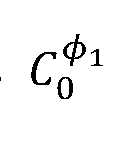
 2 the lookup operator L retrieves cost features from the cost volume C0 according to the
 index field and in the iteration T the lookup operator L retrieves cost features from

 the cost volume C0 according to the index field .
[0039] The index field
 , the retrieved cost features and the context feature
 are
 concatenated, and fed into the GRU module 420, together with a latent hidden state ht. The GRU module 420 outputs a residual value Δϕt-1 and a new hidden state ht+1:
 [0040] The first depth map DT at iteration T is estimated by sampling the depth hypotheses via linear interpolation given the index field ϕT obtained finally. In one embodiment, assuming the index field is at 1/4 resolution, a upsampling operator U (ex. a convex combination of a 3×3 neighbors) is used to upsample the index field to full resolution. For example, weight mask
 is predicted from the hidden state ht using two convolutional layers and
 softmax is performed over the weights of those 9 neighbors. The final high resolution index field (upsampled index field
 ) is obtained by taking a weighted combination over the 9 neighbors, and reshaping to the resolution H×W. Convex combination can be implemented using the einsum function in PyTorch. [0041] In one embodiment, a set of depth planes is used to construct
 the cost volume C0. A small M0 helps reduce the computation and space. The spatial upsampling is performed for the depth planes B0 to obtain depth planes

 . The depth index fields are adjusted by a scale . To mimic the convex
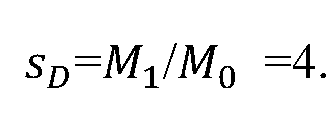 combination before mentioned, a similar weighted summation is applied along the depth dimension when sampling depth from depth planes B1. Specifically, another mask W1 ∈
 predicted from the hidden state using three convolutional layers, and further reshaped to . Given a pixel p, and the upsampled index field , the final depth (first

 depth map DT) is estimated as equation (4):
 where, the neighbors are aggregated within a radius r=4 centered at the index field
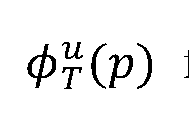 for a given pixel p, and ⌊ ⌋ gives a greatest integer less than or equal to i, and [i] means to index the depth planes B1 via linear interpolation, due to index i being a real number. [0042] The iterative estimate of the index field enables the learning to be directly anchored at the cost volume domain. This indexing paradigm differentiates our approach from other depth estimation methods, such as the convolution-based depth regression which fuses cost volume and the skipped multi-level features by 2D CNNs, or soft-argmin based depth regression after cost volume aggregation and regularization by 3D CNNs. [0043] In another embodiment, an accurate cost volume benefits the GRU-based iterative optimization. The quality of the generated cost volume C0 is not only determined by the aggregated reference feature and the source features fS (for which an asymmetric employment
 of the transformer layer is proposed), but also by the homography warping. In practice, the camera poses are usually obtained by visual SLAM (simultaneous localization and mapping) algorithms and inevitably contains noise. Accordingly, a residual pose network is provided to rectify the camera poses for accurately backward warping the reference feature to match the corresponding features in the source images. [0044] FIG.5 is a schematic diagram illustrating depth prediction using iterative estimation and residual pose estimation according to an embodiment of the disclosure. The embodiment shown in FIG. 5 is based on the architecture of FIG. 4. The system architecture (including feature extractors 310 and 320, the transformer layer 330, context feature extractor 410, GRU-based iterative optimization layers 420, and the residual pose network 520, etc.) are trained to minimize the loss between the predicted depth maps and the ground truth depth. [0045] Herein, in view of inaccuracy of poses between reference image and source images, a
residual pose network 520 is incorporated to correct the relative poses. This essentially rectifies the cost volume in the frame-level. Another round of GRU-based iterative updates will be performed based on the new cost volume and the depth maps will be predicted as the final output. [0046] After estimating the first depth map DT (for details, please refer to FIG.4), an updated cost volume C1 is constructed based on a residual pose adjusted by the first depth map DT. Then, the iterative estimation based on the updated cost volume C1 is re-performed to obtain another series of index fields and a second depth map
 is estimated based on the index
 field (ϕ"T) obtained finally in the another series of index fields. The evaluation of the second depth map is analogous to the evaluation of the first depth map DT. [0047] Before constructing the updated cost volume C1, the source images IS are warped respectively to obtain a plurality of warped source images (i.e.,
 warped , and the residual pose network 520 is used to encode the reference image
 I0 and the warped source images with at least one of the first depth map DT, a camera pose (i.e.
 the original relative poses
 ) and a ground truth depth
 , and obtaining the residual pose
 . Here, represents a collection of relative poses between the reference image I0 and the source images I1 to IN-1. In the embodiment, the residual pose network 520 can be implemented using an image-net pre-trained residual neural network (ResNet) backbone. [0048] Specifically, given a depth map DT (currently estimated) at iteration t in the first iterative estimation and the ground truth depth Dgt, a source image Ii is warped into the reference image I0 through the equation (2) with (noisy) ground truth camera poses, i.e., original relative poses Θ0 and DT or Dgt. A probability prob(DT)=0.6 during the network training is used to randomly select one between DT and Dgt, while the depth map DT is always chosen during network inference, i.e., probability prob(DT)=1 during the network inference. The input to the residual pose network 520 is the concatenated result obtained by concatenating the reference image I0 and
 warped source images , and the output is an axis-angle representation, which is further converted
 to a residual rotation matrix (residual pose) for an updated relative pose θ . Here, ∆θi
 is the residual pose of the relative pose θi (i=1, …, N-1). The collection of residual poses for each pair of each source image and the reference image, and perform the
 rectification as . The collection of updated poses is used to implement
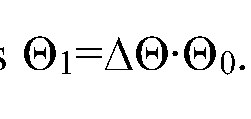
 an updated homography
 ( , ), and a more accurate cost volume, i.e. updated cost volume C1 is obtained using the updated homography
 based on the equations (2) and (3). [0049] Then, the iterative estimation is re-performed based on the updated cost volume C1 to obtain another series of index fields. Similar to that described in shown in FIG.4, an initial value is determined from the updated cost volume C1 by the sof-argmin function as the initial index field . Then at each iteration t (assuming T iterative updates, t=1, 2, ... , T), a residual value
 is obtained through the GRU-based module 420 by inputting the cost features, retrieved from the updated cost volume C1 according to the index field ϕ"t-1 obtained last time, and the context feature . Afterwards, the index field ϕ"t is estimated by adding the residual value and the index
 field obtained last time. [0050] Extensive experiments on real-world MVS datasets are conducted to show that the disclosure achieves state-of-the-art performance in terms of both within-dataset evaluation and cross-dataset generalization. [0051] The disclosure is implemented in PyTorch, and trained end-to-end with a mini-batch size of 8 per NVIDIA RTX A6000 GPU. During training, the AdamW optimizer is used and gradients are clipped to the range [−1, 1]. When generating the cost volume by plane-sweep stereo, the plane hypotheses number is set as M1=256. The same hyperparameters are adopted for the context network and 3-level GRU architecture. In the training schedule, the network architecture of the disclosure is trained for 20 epochs, with an initial learning rate of 1e-4 and
decayed by half at epoch 4th and 8th, respectively. For fair comparison, the baselines PairNet and IterMVS are trained on the same training samples of ScanNet for 20 epochs, using the official codes and Adam Optimizer. For the baseline PairNet, the suggested learning rate scheduler in their paper is used. And for the baseline Iter-MVS, a learning rate of 1e-4 is used, which is decayed by half at epoch 4th and 8th. The disclosure can make more accurate and sharp depth prediction, especially for regions near boundary and edges. For both near and far objects, our method outperforms the baselines IterMVS and Pair-Net. [0052] To sum up, embodiments of the disclosure provide a method for predicting depth map via multi-view stereo system, an electronic apparatus and a storage medium. The disclosure estimates the depth maps from a set of posed multi-view images (one as the reference and others as the sources images), and exploits learning-to-optimize paradigm that iteratively indexes a plane- sweeping cost volume and regresses depth maps via convolutional GRUs. The cost volume construction is further improved via the incorporation of a transformer block to the reference image and a residual pose network to correct the relative poses. [0053] Since the cost volume plays a paramount role in encoding the multi-view geometry, the disclosure aims to improve its construction both in pixel- and frame-levels. In the pixel level, a transformer layer is introduced to the reference image (but not to the source images) to break the symmetry of the Siamese network (which is typically used in MVS to extract image features). Such an asymmetric volume allows the network to extract global features from the reference image to predict its depth map. Moreover, in the frame-level, in view of inaccuracy of poses between reference and source images, a residual pose network is incorporated to correct the relative poses. This essentially rectifies the cost volume in the frame-level. [0054] The extensive experiments on ScanNet, DTU, 7-Scenes, and RGB-D Scenes V2 have demonstrated the superior accuracy and cross-dataset generalization capability of our method. [0055] It will be apparent to those skilled in the art that various modifications and variations can
be made to the disclosed embodiments without departing from the scope of the disclosure. In view of the foregoing, it is intended that the disclosure covers modifications and variations provided that they fall within the scope of the following claims and their equivalents.
Claims
WHAT IS CLAIMED IS: 1. A method for predicting depth map via a multi-view stereo system performed on an electronic apparatus, comprising: extracting source features from a plurality of source images, and extracting an aggregated reference feature from a reference image, wherein the reference image is one of a plurality of captured images of a same scene with different camera poses, and the source images are remaining captured images; constructing a cost volume based on the source features and the aggregated reference feature; performing an iterative estimation having a plurality of iterations based on the cost volume to obtain a series of index fields, the iterative estimation comprising: for each of iterations, predicting a residual value through a recurrent neural network by using an index field obtained last time, and obtaining an index field of current iteration according to the residual value and the index field obtained last time; and estimating a first depth map based on the index field obtained finally in the series of index fields.
2. The method for predicting depth map via the multi-view stereo system according to claim 1, further comprising: extracting a context feature from the reference image by using a context feature network; wherein the iterative estimation further comprises: before performing the iterations, determining an initial value from the cost volume by soft- argmin function as an initial index field of the series of index fields; and for each of the iterations, comprising: retrieving cost features from the cost volume according to the index field obtained last time; inputting the cost features and the context feature to the recurrent neural network and
obtaining the residual value; and obtaining the index field of the current iteration by adding the residual value and the index field obtained last time.
3. The method for predicting depth map via the multi-view stereo system according to claim 1, wherein after estimating the first depth map, the method further comprises: constructing a updated cost volume based on a residual pose adjusted by the first depth map; re-performing the iterative estimation based on the updated cost volume to obtain another series of index fields; and estimating a second depth map based on the index field obtained finally in the another series of index fields.
4. The method for predicting depth map via the multi-view stereo system according to claim 3, wherein before calculating the updated cost volume, the method further comprises: warping the source images to obtain a plurality of warped source images; and using a residual pose network to encode the reference image and the warped source images with at least one of the first depth map, a camera pose and a ground truth depth, and obtaining the residual pose.
5. The method for predicting depth map via the multi-view stereo system according to claim 1, wherein extracting the aggregated reference feature from the reference image comprises: extracting a matching feature from the reference image by a feature extractor; and constructing the aggregated reference feature based on the matching feature by a transformer layer.
6. The method for predicting depth map via the multi-view stereo system according to claim 1, wherein estimating the first depth map comprises: estimating the first depth map by sampling a plurality of depth planes via linear interpolation with the index field obtained finally in the series of index fields.
7. An electronic apparatus, comprising: a storage, configured to store a program; and a processor, coupled to the storage, and configured to execute the program to: extract source features from a plurality of source images, and extracting an aggregated reference feature from a reference image, wherein the reference image is one of a plurality of captured images of a same scene with different camera poses, and the source images are remaining captured images; construct a cost volume based on the source features and the aggregated reference feature; perform an iterative estimation having a plurality of iterations based on the cost volume to obtain a series of index fields, the iterative estimation comprising: for each of iterations, predicting a residual value through a recurrent neural network by using an index field obtained last time, and obtaining an index field of current iteration according to the residual value and the index field obtained last time; and estimate a first depth map based on the index field obtained finally in the series of index fields.
8. The electronic apparatus according to claim 7, wherein the processor is configured to execute the program to: extract a context feature from the reference image by using a context feature network, wherein the iterative estimation comprises: before performing the iterations, determine an initial value from the cost volume by soft- argmin function as an initial index field of the series of index fields; and for each of the iterations, comprising: retrieving cost features from the cost volume according to the index field obtained last time; inputting the cost features and the context feature to the recurrent neural network and
obtaining the residual value; and obtaining the index field of the current iteration by adding the residual value and the index field obtained last time.
9. The electronic apparatus according to claim 7, wherein the processor is configured to execute the program to: construct a updated cost volume based on a residual pose adjusted by the first depth map; re-perform the iterative estimation based on the updated cost volume to obtain another series of index fields; and estimate a second depth map based on the index field obtained finally in the another series of index fields.
10. The electronic apparatus according to claim 9, wherein the processor is configured to execute the program to: warp the source images to obtain a plurality of warped source images; and use a residual pose network to encode the reference image and the warped source images with at least one of the first depth map, a camera pose and a ground truth depth, and obtaining the residual pose.
11. The electronic apparatus according to claim 7, wherein the processor is configured to execute the program to: extract a matching feature from the reference image; and construct the aggregated reference feature based on the matching feature by a transformer layer.
12. The electronic apparatus according to claim 7, wherein the processor is configured to execute the program to: estimate the first depth map by sampling a plurality of depth planes via linear interpolation with the index field obtained finally in the series of index fields.
13. A non-transitory computer readable storage medium, wherein the non-transitory computer readable storage medium records at least one programmed instruction, and after being loaded into an electronic apparatus, the at least one programmed instruction performs the following steps: extracting source features from a plurality of source images, and extracting an aggregated reference feature from a reference image, wherein the reference image is one of a plurality of captured images of a same scene with different camera poses, and the source images are remaining captured images; constructing a cost volume based on the source features and the aggregated reference feature; performing an iterative estimation having a plurality of iterations based on the cost volume to obtain a series of index fields, the iterative estimation comprising: for each of iterations, predicting a residual value through a recurrent neural network by using an index field obtained last time, and obtaining an index field of current iteration according to the residual value and the index field obtained last time; and estimating a first depth map based on the index field obtained finally in the series of index fields.
Priority Applications (1)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| CN202380039497.5A CN119173906A (en) | 2022-05-19 | 2023-05-18 | Method, electronic device and storage medium for predicting depth map by multi-view stereo vision system |
Applications Claiming Priority (2)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| US202263343910P | 2022-05-19 | 2022-05-19 | |
| US63/343,910 | 2022-05-19 |
Publications (1)
| Publication Number | Publication Date |
|---|---|
| WO2023225235A1 true WO2023225235A1 (en) | 2023-11-23 |
Family
ID=88836000
Family Applications (1)
| Application Number | Title | Priority Date | Filing Date |
|---|---|---|---|
| PCT/US2023/022791 Ceased WO2023225235A1 (en) | 2022-05-19 | 2023-05-18 | Method for predicting depth map via multi-view stereo system, electronic apparatus and storage medium |
Country Status (2)
| Country | Link |
|---|---|
| CN (1) | CN119173906A (en) |
| WO (1) | WO2023225235A1 (en) |
Cited By (5)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN117649436A (en) * | 2023-12-12 | 2024-03-05 | 清华大学深圳国际研究生院 | A fast binocular stereo matching method |
| CN117830774A (en) * | 2023-12-13 | 2024-04-05 | 浙江吉利控股集团有限公司 | A method and device for obtaining key information features for three-dimensional reconstruction |
| CN119963731A (en) * | 2025-01-09 | 2025-05-09 | 北京大学 | A three-dimensional point cloud reconstruction method, device and electronic equipment |
| US20250238945A1 (en) * | 2024-01-19 | 2025-07-24 | Toyota Research Institute, Inc. | Learned Stereo Architecture |
| US12511753B2 (en) * | 2022-05-24 | 2025-12-30 | Alibaba (China) Co., Ltd. | Image processing method, apparatus and non-transitory computer readable medium for performing image processing |
Citations (4)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US20200193623A1 (en) * | 2018-12-18 | 2020-06-18 | Samsung Electronics Co., Ltd. | Method and apparatus for calculating depth map |
| US20200320781A1 (en) * | 2015-07-17 | 2020-10-08 | Bao Tran | Systems and Methods for Fitting Product |
| US20210279904A1 (en) * | 2020-03-05 | 2021-09-09 | Magic Leap, Inc. | Systems and methods for depth estimation by learning triangulation and densification of sparse points for multi-view stereo |
| US20220026920A1 (en) * | 2020-06-10 | 2022-01-27 | AI Incorporated | Light weight and real time slam for robots |
-
2023
- 2023-05-18 WO PCT/US2023/022791 patent/WO2023225235A1/en not_active Ceased
- 2023-05-18 CN CN202380039497.5A patent/CN119173906A/en active Pending
Patent Citations (4)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US20200320781A1 (en) * | 2015-07-17 | 2020-10-08 | Bao Tran | Systems and Methods for Fitting Product |
| US20200193623A1 (en) * | 2018-12-18 | 2020-06-18 | Samsung Electronics Co., Ltd. | Method and apparatus for calculating depth map |
| US20210279904A1 (en) * | 2020-03-05 | 2021-09-09 | Magic Leap, Inc. | Systems and methods for depth estimation by learning triangulation and densification of sparse points for multi-view stereo |
| US20220026920A1 (en) * | 2020-06-10 | 2022-01-27 | AI Incorporated | Light weight and real time slam for robots |
Non-Patent Citations (2)
| Title |
|---|
| JIAYU YANG; WEI MAO; JOSE M. ALVAREZ; MIAOMIAO LIU: "Cost Volume Pyramid Based Depth Inference for Multi-View Stereo", ARXIV, 18 December 2019 (2019-12-18), pages 1 - 10, XP081562243 * |
| XIAOXIAO LONG; LINGJIE LIU; WEI LI; CHRISTIAN THEOBALT; WENPING WANG: "Multi-view Depth Estimation using Epipolar Spatio-Temporal Networks", ARXIV, 12 July 2021 (2021-07-12), pages 1 - 10, XP091001899 * |
Cited By (5)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US12511753B2 (en) * | 2022-05-24 | 2025-12-30 | Alibaba (China) Co., Ltd. | Image processing method, apparatus and non-transitory computer readable medium for performing image processing |
| CN117649436A (en) * | 2023-12-12 | 2024-03-05 | 清华大学深圳国际研究生院 | A fast binocular stereo matching method |
| CN117830774A (en) * | 2023-12-13 | 2024-04-05 | 浙江吉利控股集团有限公司 | A method and device for obtaining key information features for three-dimensional reconstruction |
| US20250238945A1 (en) * | 2024-01-19 | 2025-07-24 | Toyota Research Institute, Inc. | Learned Stereo Architecture |
| CN119963731A (en) * | 2025-01-09 | 2025-05-09 | 北京大学 | A three-dimensional point cloud reconstruction method, device and electronic equipment |
Also Published As
| Publication number | Publication date |
|---|---|
| CN119173906A (en) | 2024-12-20 |
Similar Documents
| Publication | Publication Date | Title |
|---|---|---|
| US12616559B2 (en) | Object detection and instance segmentation of 3D point clouds based on deep learning | |
| Wang et al. | Multi-view stereo in the deep learning era: A comprehensive review | |
| Liang et al. | Deep continuous fusion for multi-sensor 3d object detection | |
| Shen et al. | Digging into uncertainty-based pseudo-label for robust stereo matching | |
| Eldesokey et al. | Propagating confidences through cnns for sparse data regression | |
| Bloesch et al. | Codeslam—learning a compact, optimisable representation for dense visual slam | |
| EP4246458A1 (en) | System for three-dimensional geometric guided student-teacher feature matching (3dg-stfm) | |
| CN111325797A (en) | A Pose Estimation Method Based on Self-Supervised Learning | |
| WO2021018811A1 (en) | Generative adversarial networks for image segmentation | |
| Qu et al. | Depth completion via deep basis fitting | |
| CN119173906A (en) | Method, electronic device and storage medium for predicting depth map by multi-view stereo vision system | |
| CN119580985B (en) | Robot-assisted wound treatment method and system based on multi-mode image analysis | |
| CN115331009A (en) | Medical image segmentation method based on multi-task MeanTeacher | |
| CN110781894B (en) | Point cloud semantic segmentation method, device and electronic device | |
| CN114445480A (en) | Transformer-based thermal infrared image stereo matching method and device | |
| CN115346207B (en) | Method for detecting three-dimensional target in two-dimensional image based on example structure correlation | |
| CN118037989B (en) | A multi-view neural implicit surface reconstruction method based on prior-driven | |
| CN116798016A (en) | Multimodal three-dimensional target detection method, system and storage medium for autonomous driving | |
| dos Santos Rosa et al. | Sparse-to-continuous: Enhancing monocular depth estimation using occupancy maps | |
| CN116310812A (en) | Semantic Change Detection Method for High-Resolution Remote Sensing Images Based on Semi-supervised Semantic Segmentation Contrastive Learning | |
| US20250157055A1 (en) | Method and apparatus with scene flow estimation | |
| CN116403068B (en) | Lightweight monocular depth prediction method based on multi-scale attention fusion | |
| CN114372523A (en) | An Uncertainty Estimation Method for Binocular Matching Based on Evidence Deep Learning | |
| CN116824330A (en) | A small-sample cross-domain target detection method based on deep learning | |
| CN111062406B (en) | A semi-supervised optimal transmission method for heterogeneous domain adaptation |
Legal Events
| Date | Code | Title | Description |
|---|---|---|---|
| 121 | Ep: the epo has been informed by wipo that ep was designated in this application |
Ref document number: 23808334 Country of ref document: EP Kind code of ref document: A1 |
|
| NENP | Non-entry into the national phase |
Ref country code: DE |
|
| 122 | Ep: pct application non-entry in european phase |
Ref document number: 23808334 Country of ref document: EP Kind code of ref document: A1 |