WO2010119233A1 - A data retrieval and indexing method and apparatus - Google Patents
A data retrieval and indexing method and apparatus Download PDFInfo
- Publication number
- WO2010119233A1 WO2010119233A1 PCT/GB2009/000977 GB2009000977W WO2010119233A1 WO 2010119233 A1 WO2010119233 A1 WO 2010119233A1 GB 2009000977 W GB2009000977 W GB 2009000977W WO 2010119233 A1 WO2010119233 A1 WO 2010119233A1
- Authority
- WO
- WIPO (PCT)
- Prior art keywords
- vector
- file
- feature
- features
- data
- Prior art date
- Legal status (The legal status is an assumption and is not a legal conclusion. Google has not performed a legal analysis and makes no representation as to the accuracy of the status listed.)
- Ceased
Links
Classifications
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F16/00—Information retrieval; Database structures therefor; File system structures therefor
- G06F16/60—Information retrieval; Database structures therefor; File system structures therefor of audio data
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F16/00—Information retrieval; Database structures therefor; File system structures therefor
- G06F16/20—Information retrieval; Database structures therefor; File system structures therefor of structured data, e.g. relational data
- G06F16/22—Indexing; Data structures therefor; Storage structures
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F16/00—Information retrieval; Database structures therefor; File system structures therefor
- G06F16/30—Information retrieval; Database structures therefor; File system structures therefor of unstructured textual data
- G06F16/31—Indexing; Data structures therefor; Storage structures
- G06F16/313—Selection or weighting of terms for indexing
-
- G—PHYSICS
- G10—MUSICAL INSTRUMENTS; ACOUSTICS
- G10L—SPEECH ANALYSIS TECHNIQUES OR SPEECH SYNTHESIS; SPEECH RECOGNITION; SPEECH OR VOICE PROCESSING TECHNIQUES; SPEECH OR AUDIO CODING OR DECODING
- G10L15/00—Speech recognition
- G10L15/06—Creation of reference templates; Training of speech recognition systems, e.g. adaptation to the characteristics of the speaker's voice
-
- G—PHYSICS
- G10—MUSICAL INSTRUMENTS; ACOUSTICS
- G10L—SPEECH ANALYSIS TECHNIQUES OR SPEECH SYNTHESIS; SPEECH RECOGNITION; SPEECH OR VOICE PROCESSING TECHNIQUES; SPEECH OR AUDIO CODING OR DECODING
- G10L15/00—Speech recognition
- G10L15/08—Speech classification or search
- G10L15/18—Speech classification or search using natural language modelling
- G10L15/183—Speech classification or search using natural language modelling using context dependencies, e.g. language models
Definitions
- the present invention relates to the field of data retrieval and indexing, more specifically the present invention is concerned with a linear semantic method which can be used in text searching, speech processing, image processing etc.
- BoW bag-of-words
- the bag-of-words method has been widely used in natural language processing (NLP) where the data object is provided by the text documents and the items are an unordered collection of words which occur in the documents. It is also used in the computer vision area, where the data object is an image and the items are codewords from a codebook.
- NLP natural language processing
- the BoW method expresses the document as a bunch of individual words. However, the bag of words may not sufficiently express the semantic information sufficiently. For example, if there is a document containing the date "September 11", neither "September” nor "11" correctly conveys the real information of the document. If the BoW method is used to select similar documents, many unrelated documents such as "oceans eleven" or "black September” are selected. Meanwhile, because of polysemy, a word may lead to some semantic ambiguity. For example, "curry” can be a kind of food or the name of an IT shop. This kind of ambiguity influences the performance of BoW type analysis.
- BoWP bag-of-wordpairs
- the present invention provides a method of searching a plurality of data files, wherein each data file comprises a plurality of features; determining a plurality of feature groups, wherein each feature group comprises n features and n is an integer of 2 or more; expressing each data file as a file vector with components of the vector indicating the frequency of a feature group within the data file, wherein the n features which constitute a feature group do not have to be located adjacent to one another; expressing a search query using said feature groups as a vector; and searching said plurality of data files by comparing the search query expressed as a vector with said file vectors.
- the proposed method extends the traditional BoW method to represent the object as an unordered collection of item pairs or groups. It is important to note that the features within the feature group do not have to be located next to each other or provided in any particular order. By doing so, in the domain of NLP and language modelling, more complicated semantic information in the text can be modelled.
- the present invention may be applied to a plurality of fields, for example Natural language processing (NLP), Information retrieval (IR), document classification, computer vision, language modelling, speech recognition, speech-to-speech translation, OCR, handwriting recognition, or other applications using statistical language model information.
- NLP Natural language processing
- IR Information retrieval
- document classification computer vision
- language modelling computer vision
- speech recognition speech-to-speech translation
- OCR handwriting recognition
- handwriting recognition or other applications using statistical language model information.
- the data files may be selected from documents, corpus for speech processing, image data files, telemetric data from machines or any monitoring device, measurements, records or meter reading.
- the feature group will be a feature pair.
- the feature may be a word, phrase, codeword in an image etc.
- the search query may be expressed as a file vector itself.
- the components of the search query vector are the same as those of the file vectors.
- the comparison may be performed by determining the separation between the file vector of the search query and the file vectors of the data files. The cosine of the angle between the two vectors may be calculated to quantify this separation.
- the search query is also possible to express the search query as a feature group vector where the components of the feature group vector indicate the occurrence of the feature group in a document.
- two feature group vectors maybe constructed using the occurrence of each feature group over documents/data files.
- the present invention provides a method of searching a plurality of data files, wherein each data file comprises a plurality of features; determining a plurality of feature groups, wherein each feature group comprises n features and n is an integer of 2 or more; expressing each feature group as a feature group vector with components of the vector indicating data files where the feature group occurs, wherein the n features which constitute a feature group do not have to be located adjacent to one another in a data file; expressing a search query using said feature groups as a vector; and searching said plurality of data files by comparing the search query expressed as a vector with said feature group vectors.
- the above may also be used for document and data clustering. Also, the above may also be used for word clustering based on this measurement, the synonymy and polysemy can be detected.
- determining a plurality of feature groups comprises pruning feature groups from all possible feature groups on the basis of association between the features in said feature groups.
- Determining a plurality of feature groups may also comprise removing feature groups which contain features which are repeated frequently in the data file. For example, if the data file is a text document and the features are words, removing words such as "a” or "the” will yield better results.
- the file vectors are arranged in a matrix to provide lateral semantic analysis (LSA) method. Said matrix may be factorised by a technique such as SVD.
- the above method may be used for building a domain dependent statistical language model (LM) for ASR, the LM can catch more semantic information of the target domain.
- LM domain dependent statistical language model
- the present invention provides a method of selecting training corpora for processing speech relating to a specific subject matter, the method comprising: providing a plurality of general training corpora; inputting at least one data file relating to the specific subject matter; and searching the plurality of general training corpora for corpus relating to the subject matter using the method according to the first aspect of the invention, wherein the search query is the data file relating to the specific subject matter and the plurality of data files to be searched are the plurality of general training corpora.
- the present invention provides a method of speech processing comprising selecting a training corpora as described above; training a language model for speech processing using said selected corpora; and processing speech using said language model.
- the above speech processing may be applied to automatic speech recognition (ASR) where an input speech signal is output as a text data file or it may be applied to text-to-speech systems where input text is converted into an audio speech file.
- ASR automatic speech recognition
- the training of language model using the above may also be applied to handwriting recognition, OCR etc.
- a language model trained using a method which selects documents on the basis of feature groups may also be combined with a language model trained using other documents. Such a method will allow the mixture between the complex semantic information captured using feature groups and other methods to be realised.
- training said language model may comprise training a first language model using the training corpora selected as described above; training a second language model using a training corpora selected according to a different method; and interpolating said first and second language models.
- the training corpora for said second language model maybe selected by providing a plurality of general training corpora; inputting at least one data file relating to the subject matter of the speech processing method; expressing each corpus in the corpora as a file vector with components of the vector indicating the frequency of each word within the corpus, expressing the data file relating to the subject matter of the speech processing method in the same form as said file vectors; and searching said corpora by comparing the search query expressed as a vector with said file vectors.
- training the language model may further comprise: expressing the probability of a current word w; in a language model as: where d is a document, h is the word history and:
- training the language model further comprises: expressing the probability of a current word w; in a language model as:
- d is a document
- h is the word history
- the present invention provides a method of indexing data files, wherein each data file comprises a plurality of features, the method comprising: determining a plurality of feature groups, wherein each feature group comprises n features and n is an integer of 2 or more; and expressing each data file as a file vector where each component of the vector indicates the frequency of a feature group within the data file, wherein the n features which constitute a feature group do not have to be located adjacent to one another, wherein each file vector provides an index for said data file.
- the present invention also provides an improved database. Therefore, in a sixth aspect, the present invention provides a database comprising a plurality of data files, wherein each data file comprises a plurality of features and an index, each index comprising a file vector where each component of the vector indicates the frequency of a feature group within the data file and each feature group comprises n features where n is an integer of 2 or more, the n features which constitute a feature group do not have to be located adjacent to one another.
- the present invention provides an apparatus for searching a plurality of data files, wherein each data file comprises a plurality of features
- the apparatus comprising a processor configured to: determine a plurality of feature groups, wherein each feature group comprises n features and n is an integer of 2 or more; express each data file as a file vector with components of the vector indicating the frequency of a feature group within the data file, wherein the n features which constitute a feature group do not have to be located adjacent to one another; express a search query using said feature groups as a vector; and search said plurality of data files by comparing the search query expressed as a vector with said file vectors.
- the present invention provides a speech processing apparatus, comprising: a processor configured to select training corpora; train a language model for speech processing using said selected corpora; and process speech using said language model, wherein selecting training corpora comprises: inputting at least one data file relating to the subject matter of the speech to be processed; expressing each corpus in the corpora as a file vector with components of the vector indicating the frequency of each word group within the corpus, wherein each word group comprises n words and n is an integer of at least 2, expressing the data file relating to the subject matter of the speech processing method in the same form as said file vectors; and searching said corpora by comparing the search query expressed as a vector with said file vectors.
- the present invention can be implemented either in hardware or on software in a general purpose computer. Further the present invention can be implemented in a combination of hardware and software. The present invention can also be implemented by a single processing apparatus or a distributed network of processing apparatuses.
- the present invention can be implemented by software, the present invention encompasses computer code provided to a general purpose computer on any suitable carrier medium.
- the carrier medium can comprise any storage medium such as a floppy disk, a CD ROM, a magnetic device or a programmable memory device, or any transient medium such as any signal e.g. an electrical, optical or microwave signal.
- Figure 1 is a schematic of a system which may be used with a method in accordance with an embodiment of the present invention
- Figure 2 is a flow chart of a document indexing method in accordance with an embodiment of the present invention.
- Figure 3 is a flow chart of a search method in accordance with an embodiment of the present invention.
- Figure 4 is a document retrieval system in accordance with an embodiment of the present invention
- Figure 5 is a speech processing system in accordance with an embodiment of the present invention.
- Figure 1 is a schematic of a data search or indexing system.
- the system 1 comprises a processor 3 which executes a program 5.
- Data system 1 further comprises storage 7.
- the storage 7 stores a plurality of data files which are indexed and searched by program 5.
- the data system 1 further comprises an input/output module 9.
- the input/output module 9 provides an interface to the processor.
- a search query may be input via a keyboard, network, external storage media, audio input etc.
- the results may be output visually or provided as a data file.
- text such as a sentence, paragraph etc
- the term "document” is used to encompass text of any length from a phrase to a book.
- the BoW model is a dictionary-based model. Each document is treated like a "bag” (thus the order is not considered) which contains some words from the dictionary. For example, suppose that there are 2 simple text documents
- each document is represented by a 16-entry vector:
- LSA latent semantic analysis
- the value of every cell corresponds to some suitable function of the word count.
- the number of times each word appears in each document, the word count is usually normalised by the document length and word entropy.
- a suitable expression for the (ij) cell of A is
- Ci j is the number of times word w, occurs in document dj itj is the total number of words present in d j 6, is the normalized entropy of w,- in the corpus
- e can be calculated as: 1 N r r
- the (MxN) word document matrix A defines 2 vector representations for the words and the documents.
- Each word w can be uniquely associated with a row vector of dimension N
- each document d j can be uniquely associated with a column vector of dimension M.
- these vector presentations are impractical for 3 reasons. First the dimensions M and N can be extremely large; second, the vectors w, and d j are very sparse; third, the two spaces are distinct from one other.
- S is the (RxR) diagonal matrix of singular values
- U is the (MxR) left singular matrix with row vectors w, (1 ⁇ )
- V is (NxR) right singular matrix with row vectors vj (1 -3- ⁇ ).
- A is the i?-rank best approximation of original word document matrix A. It keeps the major structure of A and ignores the high order information.
- ⁇ is the matrix transposition.
- each word in the word- document matrix can be expressed as a row vector of matrix US and each document can be expressed as a row vector of matrix VS, i.e. the word W 1 can be expressed as a R-dimension vector UiS and a document d . can be expressed as a R-dimension vector vjS in LSA space.
- the dimension of the row vector of matrix US is R, which is much smaller than the original size of vocabulary M, meanwhile, the dimension of the row vector of row vector of VS is also R, which is much smaller than the original document number N.
- the similarity between 2 words can be calculated as the cosine of the angle between their feature vectors in LSA space, i.e.
- BoW LSA feature space provides a very powerful tool to analyze the relations between words, documents, or word and document.
- the above known method has also been used in speech processing.
- the role of the LM is providing the prior probability of the word sequence W.
- Conventional statistical speech recognisers use n-gram LMs which assume that the probability of each word depends on the previous n-1 words in the sequence, i.e.
- N N N p(W) Yl P (W 1 1 w, • • • w,_, ) ⁇ Yl p(w t I w.. ⁇ +1 • • • w M ) (7)
- Eqn 10 the calculation of p(w,
- Figure 2 is a flow chart illustrating an indexing method in accordance with an embodiment of the present invention.
- step SlOl data files which are to be indexed using the method will be collected. For example, if this system is to be used for document retrieval, the documents which are to be searched will be indexed in this manner.
- step S 103 word pairs are derived. These word pairs are then stored. Using the above example, take two simple text documents:
- each document may be represented by a 78-entry vector:
- AMI average mutual information
- the association between 2 words can also be calculated using a LSA based on BoW method. As described in section 6a, in the BoW based LSA feature space, if the feature vectors of 2 words are close, it means that these 2 words occur in same document frequently. Therefore Eqn 2 can be used to measure the association of 2 words.
- the general words such as ⁇ "a",”the” ⁇ do not contain plenty of semantic information. Therefore, the word pairs which contain the general words should not be selected.
- the generalisation of a word can be measured using inverse document frequency (IDF) value.
- WORDPAIR(d) as ⁇ w, , w 2 I w, e d, w 2 e d, idf(w x ) > a, idf(w 2 ) > a, (12) association ⁇ , W 2 ) > ⁇ ]
- association(w ⁇ ,w 2 ) is a certain measurement of association of 2 words, it can be the AMI, distance of feature vectors of 2 words in BoW feature space or other measurements.
- the ⁇ and ⁇ are empirical thresholds.
- each document is represented by a 16- component vector:
- a co-occurrence matrix of word pairs and documents is then constructed in step S 109.
- Each column of the matrix represents a document and each row of the matrix is associated to a word pair.
- the co-occurrence matrix of word pairs and the documents is shown below:
- the cell a(w t , w y . , ⁇ ) represents the normalized frequency of word pair "w ⁇ w" occurred in document n, i.e.
- ⁇ (w t , W j ) is the normalized entropy for "W J , w/ ⁇ i.e.
- Eqn 10 S is a R XR diagonal matrix, of the R biggest singular values.
- U said V are the left and right singular vectors respectively.
- each row vector of matrix US represented a word pair in LSA space, i.e.
- row(w, , w y . ) represented the row number of word pair "w,w,” in the wordpair document co-occurrence matrix. Meanwhile, each document is still represented as a column vector of matrix SV .
- data files may also be image data files, telemetric data from machines or any monitoring device, measurements, records or meter reading.
- the above method may be used to index files in a database where the index is provided by the file vectors.
- FIG. 3 shows a further method in accordance with an embodiment of the present invention where the data files are searched.
- like reference numerals will be used to denote like features.
- step Sl 11 the system receives a search query. Examples of different types of search queries will be discussed later.
- v(d) ⁇ C(w,.,w.,rf) . » row(W(,W/) w, ⁇ d&&W j ed
- the search results can then be output in step Sl 17.
- the above can also be used so that a document which is input in the form of a query can be compared with a word pair vector or a document which is input in the form of a word pair can be compared with the documents in the matrix in step Sl 15.
- Comparing word pairs has application for clustering and polysemy.
- the first example is information retrieval IR.
- the framework of IR using BoWP is shown in figure 4.
- the document pool 201 which contains large amount of documents are used to construct a word pair and document co-occurrence matrix as explained with reference to figure 2 and shown in step S 203.
- each document in document pool is represented as a LSA feature vector.
- a BoWP feature 211 is generated using the word pair dictionary. Then this BoWP feature is projected to the LSA feature space 213 as a new document vector. Then the documents in document pool 201 which match the topic of the query are selected based on the distance between their feature vectors and the feature vector 213 of query in LSA feature space 207 to output selected document 215.
- the second application is domain dependent language modelling for Automatic speech recognition (ASR) or text-to-speech systems (TTS).
- ASR Automatic speech recognition
- TTS text-to-speech systems
- the BoWP method is used to select a specialised training corpus automatically from a large general corpus.
- a corpus which may be, for example, the test corpus which a user reads to train an ASR system, is used as query and the domain dependent corpus which has same semantic information as query is selected from general corpus. Then, the domain dependent corpus is used to train the LM for speech recognition.
- the experiment framework is shown in Figure 5.
- the data selection can be viewed as a process of information retrieval which is shown in Figure 4.
- An in-domain query 301 is provided to perform selection of the domain dependent documents 303 from the general corpus 305. For example, if the domain or subject matter of the speech to be processed is "tourism", then in- domain training corpora which relate to tourism can be used as query Q to select the text corpus which has same domain information as query from a large general corpus.
- the Language model 307 is then trained on the selected data 303.
- the LM is a standard language model and the training of such a model is well known to those skilled in the art and will not be repeated here.
- an n-gram language model (LM) will be used as explained with reference to equations 6 to 10.
- model 307 Once the model 307 has been trained it can be used in conjunction with an acoustic model in a speech recognition system 309.
- the recognition error rate achieved using a given LM is the most important criterion.
- Table 1 The perplexity results based on different data selection methods.
- Table 1 showed that using the method of bag-of-wordpair, the size of selected corpus is only half of the one selected by bag-of-word method. While the perplexity results of mixture LMs based on bag-of-wordpairs is better than those based on bag-of-words. This result indicates that the bag-of-wordpairs method catch the semantic information more accurate than bag-of-words method.
- the second experiment is ASR. Using the LMs mentioned above to do the speech recognition. The results are shown in Table 2
- Table 2 The speech recognition results based on different data selection methods.
- the first row. gave the results of the general LM. Because the domain mismatch between gigaword corpus and tourism is big, the general LM got very poor results.
- the second and the third row gave the results of BoW data selection LM and BoWP data selection LM respectively.
- the results showed that the LM based on semantic data selection can improve the recognition rate significantly.
- the LMs based BoW method and BoWP method got comparable results.
- the LM which has been trained using data selected by the BoW method can be expressed as:
- the LM which has been trained using BoWP data selection can be expressed as: P(w ⁇ h,Data_BoWP).
- LMs may be combined by linear interpolation, i.e. generate a new LM which can be expressed as ⁇ * P(w ⁇ h,Data_BoW)+(l- ty x P(w ⁇ h,Data_BoWP)
- the interpolation weight may be selected to maximise accuracy.
Landscapes
- Engineering & Computer Science (AREA)
- Theoretical Computer Science (AREA)
- Physics & Mathematics (AREA)
- Data Mining & Analysis (AREA)
- Databases & Information Systems (AREA)
- General Engineering & Computer Science (AREA)
- General Physics & Mathematics (AREA)
- Software Systems (AREA)
- Multimedia (AREA)
- Artificial Intelligence (AREA)
- Computational Linguistics (AREA)
- Health & Medical Sciences (AREA)
- Audiology, Speech & Language Pathology (AREA)
- Human Computer Interaction (AREA)
- Acoustics & Sound (AREA)
- Information Retrieval, Db Structures And Fs Structures Therefor (AREA)
- Machine Translation (AREA)
- Image Analysis (AREA)
Abstract
Description

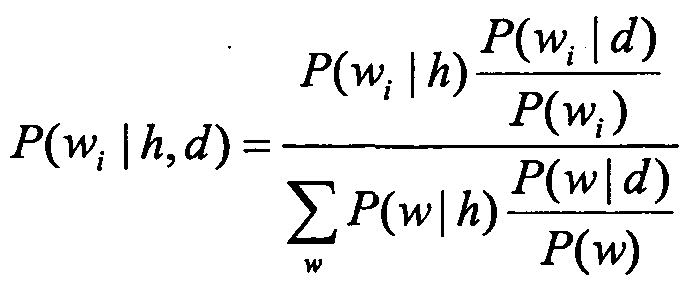


Claims


Priority Applications (4)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| JP2012505214A JP5537649B2 (en) | 2009-04-16 | 2009-04-16 | Method and apparatus for data retrieval and indexing |
| PCT/GB2009/000977 WO2010119233A1 (en) | 2009-04-16 | 2009-04-16 | A data retrieval and indexing method and apparatus |
| US13/264,845 US9223850B2 (en) | 2009-04-16 | 2009-04-16 | Data retrieval and indexing method and apparatus |
| GB1119833.0A GB2482630B (en) | 2009-04-16 | 2009-04-16 | A speech processing method and apparatus |
Applications Claiming Priority (1)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| PCT/GB2009/000977 WO2010119233A1 (en) | 2009-04-16 | 2009-04-16 | A data retrieval and indexing method and apparatus |
Publications (1)
| Publication Number | Publication Date |
|---|---|
| WO2010119233A1 true WO2010119233A1 (en) | 2010-10-21 |
Family
ID=41213186
Family Applications (1)
| Application Number | Title | Priority Date | Filing Date |
|---|---|---|---|
| PCT/GB2009/000977 Ceased WO2010119233A1 (en) | 2009-04-16 | 2009-04-16 | A data retrieval and indexing method and apparatus |
Country Status (4)
| Country | Link |
|---|---|
| US (1) | US9223850B2 (en) |
| JP (1) | JP5537649B2 (en) |
| GB (1) | GB2482630B (en) |
| WO (1) | WO2010119233A1 (en) |
Cited By (1)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| EP3195146A4 (en) * | 2014-09-18 | 2018-04-18 | Empire Technology Development LLC | Three-dimensional latent semantic analysis |
Families Citing this family (27)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US8543398B1 (en) | 2012-02-29 | 2013-09-24 | Google Inc. | Training an automatic speech recognition system using compressed word frequencies |
| JP5914054B2 (en) * | 2012-03-05 | 2016-05-11 | 日本放送協会 | Language model creation device, speech recognition device, and program thereof |
| US8996371B2 (en) * | 2012-03-29 | 2015-03-31 | Nice-Systems Ltd. | Method and system for automatic domain adaptation in speech recognition applications |
| US8374865B1 (en) * | 2012-04-26 | 2013-02-12 | Google Inc. | Sampling training data for an automatic speech recognition system based on a benchmark classification distribution |
| US8805684B1 (en) | 2012-05-31 | 2014-08-12 | Google Inc. | Distributed speaker adaptation |
| US8571859B1 (en) | 2012-05-31 | 2013-10-29 | Google Inc. | Multi-stage speaker adaptation |
| US8880398B1 (en) | 2012-07-13 | 2014-11-04 | Google Inc. | Localized speech recognition with offload |
| US9123333B2 (en) | 2012-09-12 | 2015-09-01 | Google Inc. | Minimum bayesian risk methods for automatic speech recognition |
| US9519858B2 (en) * | 2013-02-10 | 2016-12-13 | Microsoft Technology Licensing, Llc | Feature-augmented neural networks and applications of same |
| US9727619B1 (en) * | 2013-05-02 | 2017-08-08 | Intelligent Language, LLC | Automated search |
| US9251139B2 (en) * | 2014-04-08 | 2016-02-02 | TitleFlow LLC | Natural language processing for extracting conveyance graphs |
| US9665628B1 (en) | 2015-12-06 | 2017-05-30 | Xeeva, Inc. | Systems and/or methods for automatically classifying and enriching data records imported from big data and/or other sources to help ensure data integrity and consistency |
| US10586528B2 (en) * | 2017-02-02 | 2020-03-10 | Adobe Inc. | Domain-specific speech recognizers in a digital medium environment |
| US11567914B2 (en) | 2018-09-14 | 2023-01-31 | Verint Americas Inc. | Framework and method for the automated determination of classes and anomaly detection methods for time series |
| US11334832B2 (en) | 2018-10-03 | 2022-05-17 | Verint Americas Inc. | Risk assessment using Poisson Shelves |
| KR102659494B1 (en) * | 2019-01-21 | 2024-04-23 | 삼성전자주식회사 | Electronic apparatus and control method thereof |
| EP3706017A1 (en) | 2019-03-07 | 2020-09-09 | Verint Americas Inc. | System and method for determining reasons for anomalies using cross entropy ranking of textual items |
| EP3987429A1 (en) * | 2019-06-18 | 2022-04-27 | Verint Americas Inc. | Detecting anomalies in textual items using cross-entropies |
| US11308090B2 (en) | 2019-12-26 | 2022-04-19 | Snowflake Inc. | Pruning index to support semi-structured data types |
| US11567939B2 (en) | 2019-12-26 | 2023-01-31 | Snowflake Inc. | Lazy reassembling of semi-structured data |
| US10997179B1 (en) | 2019-12-26 | 2021-05-04 | Snowflake Inc. | Pruning index for optimization of pattern matching queries |
| US10769150B1 (en) | 2019-12-26 | 2020-09-08 | Snowflake Inc. | Pruning indexes to enhance database query processing |
| US11372860B2 (en) | 2019-12-26 | 2022-06-28 | Snowflake Inc. | Processing techniques for queries where predicate values are unknown until runtime |
| US11681708B2 (en) | 2019-12-26 | 2023-06-20 | Snowflake Inc. | Indexed regular expression search with N-grams |
| US12050605B2 (en) | 2019-12-26 | 2024-07-30 | Snowflake Inc. | Indexed geospatial predicate search |
| US11610581B2 (en) * | 2021-02-05 | 2023-03-21 | International Business Machines Corporation | Multi-step linear interpolation of language models |
| US11880369B1 (en) | 2022-11-21 | 2024-01-23 | Snowflake Inc. | Pruning data based on state of top K operator |
Family Cites Families (10)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US6026388A (en) * | 1995-08-16 | 2000-02-15 | Textwise, Llc | User interface and other enhancements for natural language information retrieval system and method |
| US6418431B1 (en) * | 1998-03-30 | 2002-07-09 | Microsoft Corporation | Information retrieval and speech recognition based on language models |
| JP3921837B2 (en) | 1998-09-30 | 2007-05-30 | 富士ゼロックス株式会社 | Information discrimination support device, recording medium storing information discrimination support program, and information discrimination support method |
| US6360215B1 (en) * | 1998-11-03 | 2002-03-19 | Inktomi Corporation | Method and apparatus for retrieving documents based on information other than document content |
| JP2000137718A (en) | 1998-11-04 | 2000-05-16 | Nippon Telegr & Teleph Corp <Ntt> | Word similarity determination method and recording medium storing word similarity determination program |
| US7424150B2 (en) * | 2003-12-08 | 2008-09-09 | Fuji Xerox Co., Ltd. | Systems and methods for media summarization |
| US7551780B2 (en) * | 2005-08-23 | 2009-06-23 | Ricoh Co., Ltd. | System and method for using individualized mixed document |
| US8010534B2 (en) * | 2006-08-31 | 2011-08-30 | Orcatec Llc | Identifying related objects using quantum clustering |
| US7831587B2 (en) * | 2007-05-10 | 2010-11-09 | Xerox Corporation | Event hierarchies and memory organization for structured data retrieval |
| WO2012083540A1 (en) * | 2010-12-23 | 2012-06-28 | Nokia Corporation | Method and apparatus for providing token-based classification of device information |
-
2009
- 2009-04-16 GB GB1119833.0A patent/GB2482630B/en not_active Expired - Fee Related
- 2009-04-16 US US13/264,845 patent/US9223850B2/en not_active Expired - Fee Related
- 2009-04-16 WO PCT/GB2009/000977 patent/WO2010119233A1/en not_active Ceased
- 2009-04-16 JP JP2012505214A patent/JP5537649B2/en not_active Expired - Fee Related
Non-Patent Citations (2)
| Title |
|---|
| BAEZA-YATES R ET AL: "MODERN INFORMATION RETRIEVAL, Chapter 2: Modeling", MODERN INFORMATION RETRIEVAL, HARLOW : ADDISON-WESLEY, GB, 1 January 1999 (1999-01-01), pages COMPLETE58, XP002299413, ISBN: 978-0-201-39829-8 * |
| FAGAN J L: "The effectiveness of a nonsyntactic approach to automatic phrase indexing for document retrieval", JOURNAL OF THE AMERICAN SOCIETY FOR INFORMATION SCIENCE, vol. 40, no. 2, 1989, pages 115 - 132, XP002553020, Retrieved from the Internet <URL:http://www3.interscience.wiley.com/journal/114270252/abstract?CRETRY=1&SRETRY=0> [retrieved on 20091029] * |
Cited By (1)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| EP3195146A4 (en) * | 2014-09-18 | 2018-04-18 | Empire Technology Development LLC | Three-dimensional latent semantic analysis |
Also Published As
| Publication number | Publication date |
|---|---|
| GB2482630B (en) | 2014-12-24 |
| JP5537649B2 (en) | 2014-07-02 |
| US20120109651A1 (en) | 2012-05-03 |
| GB2482630A (en) | 2012-02-08 |
| JP2012524314A (en) | 2012-10-11 |
| US9223850B2 (en) | 2015-12-29 |
| GB201119833D0 (en) | 2011-12-28 |
Similar Documents
| Publication | Publication Date | Title |
|---|---|---|
| US9223850B2 (en) | Data retrieval and indexing method and apparatus | |
| CN108363790B (en) | Method, device, equipment and storage medium for evaluating comments | |
| US7542966B2 (en) | Method and system for retrieving documents with spoken queries | |
| CN106326303B (en) | A kind of spoken semantic analysis system and method | |
| Sethy et al. | Building topic specific language models from webdata using competitive models. | |
| CN114036930A (en) | Text error correction method, device, equipment and computer readable medium | |
| CN105243143A (en) | Recommendation method and system based on instant voice content detection | |
| CN110674252A (en) | High-precision semantic search system for judicial domain | |
| CN106096066A (en) | The Text Clustering Method embedded based on random neighbor | |
| CN111027323A (en) | Entity nominal item identification method based on topic model and semantic analysis | |
| CN117421393B (en) | A generative search method and system for patents | |
| CN111858842A (en) | A Judicial Case Screening Method Based on LDA Topic Model | |
| CN118152428A (en) | A method and device for predicting and enhancing query instructions of power customer service system | |
| CN118259886A (en) | API sequence recommendation method and device based on retrieval enhancement and temperature loss | |
| Monisha et al. | Classification of bengali questions towards a factoid question answering system | |
| CN114064861A (en) | Query statement generation method and device | |
| CN119886120B (en) | Detection method for large language model to generate Chinese paper module | |
| Sangati et al. | Multiword expression identification with recurring tree fragments and association measures | |
| Winarko et al. | Indonesian abstractive text summarization using stacked embeddings and transformer decoder. | |
| CN120144876B (en) | Data vectorization tag processing method and device based on search self-feedback | |
| Chiu et al. | Word topical mixture models for dynamic language model adaptation | |
| CN115221871A (en) | Keyword Extraction Method of English Sci-tech Documents Based on Multi-feature Fusion | |
| CN111767388B (en) | Candidate pool generation method | |
| CN118350368B (en) | Multi-document select and edit method of large language model based on NLP technology | |
| CN115827988B (en) | Self-media content heat prediction method |
Legal Events
| Date | Code | Title | Description |
|---|---|---|---|
| 121 | Ep: the epo has been informed by wipo that ep was designated in this application |
Ref document number: 09784563 Country of ref document: EP Kind code of ref document: A1 |
|
| WWE | Wipo information: entry into national phase |
Ref document number: 2012505214 Country of ref document: JP |
|
| NENP | Non-entry into the national phase |
Ref country code: DE |
|
| ENP | Entry into the national phase |
Ref document number: 1119833 Country of ref document: GB Kind code of ref document: A Free format text: PCT FILING DATE = 20090416 |
|
| WWE | Wipo information: entry into national phase |
Ref document number: 1119833.0 Country of ref document: GB |
|
| WWE | Wipo information: entry into national phase |
Ref document number: 13264845 Country of ref document: US |
|
| 122 | Ep: pct application non-entry in european phase |
Ref document number: 09784563 Country of ref document: EP Kind code of ref document: A1 |