JP2013109475A - Document analysis system, document analysis method and program - Google Patents
Document analysis system, document analysis method and program Download PDFInfo
- Publication number
- JP2013109475A JP2013109475A JP2011252657A JP2011252657A JP2013109475A JP 2013109475 A JP2013109475 A JP 2013109475A JP 2011252657 A JP2011252657 A JP 2011252657A JP 2011252657 A JP2011252657 A JP 2011252657A JP 2013109475 A JP2013109475 A JP 2013109475A
- Authority
- JP
- Japan
- Prior art keywords
- word
- ambiguous
- concept
- document
- estimated key
- Prior art date
- Legal status (The legal status is an assumption and is not a legal conclusion. Google has not performed a legal analysis and makes no representation as to the accuracy of the status listed.)
- Granted
Links
Images




Landscapes
- Machine Translation (AREA)
- Document Processing Apparatus (AREA)
- Information Retrieval, Db Structures And Fs Structures Therefor (AREA)
Abstract
【課題】 曖昧語を含む文書について、各使用場面で曖昧語が文書の品質に与える影響の大きさを考慮して、精度よく文書の優先的な修正点や品質を推定する技術を提供する。
【解決手段】 本発明における文書分析システムは、外部から入力された文書を構成する文章に使用されている各単語の単語情報に基づいて、文書中における曖昧語を検索し、曖昧語が有る場合は当該曖昧語を抽出する曖昧語検索部と、推定鍵語を抽出するための推定鍵語抽出ルールに基づいて、文書から各曖昧語に対するそれぞれの推定鍵語を抽出する推定鍵語抽出部と、概念規模推定ルールに基づいて、推定鍵語抽出部で抽出された推定鍵語の概念の規模である概念規模指標を推定する概念規模推定部と、概念規模指標に基づいて、各曖昧語と推定鍵語との組合せ毎に曖昧性情報を算出する曖昧性算出部と、を含む。
【選択図】 図1PROBLEM TO BE SOLVED: To provide a technique for accurately estimating preferential correction points and quality of a document including ambiguous words in consideration of the influence of the ambiguous word on the document quality in each use scene.
A document analysis system according to the present invention searches an ambiguous word in a document based on word information of each word used in a sentence constituting an externally input document, and there is an ambiguous word. Is an ambiguous word search unit that extracts the ambiguous word, an estimated key word extraction unit that extracts each estimated key word for each ambiguous word from the document based on an estimated key word extraction rule for extracting the estimated key word; A concept scale estimation unit that estimates a concept scale index, which is the scale of the concept of the estimated key word extracted by the estimation key word extraction unit based on the concept scale estimation rule, and each ambiguous word based on the concept scale index. An ambiguity calculation unit that calculates ambiguity information for each combination with the estimated key word.
[Selection] Figure 1
Description
本発明は、文書分析システム、文書分析方法およびプログラムに関し、文書の優先的な修正点や品質を推定する文書分析システム、文書分析方法およびプログラムに関する。 The present invention relates to a document analysis system, a document analysis method, and a program, and more particularly to a document analysis system, a document analysis method, and a program for estimating preferential correction points and quality of a document.
近年、情報処理装置を用いて、自然言語で書かれた文書を分析して、その文書の優先的な修正点や品質を分析する技術が開発されている。文書分析技術の一例が、特許文献1に「日本語文章修正装置、日本語文章修正方法および日本語文章修正のためのプログラム」として開示されている。
2. Description of the Related Art In recent years, a technology has been developed that uses an information processing apparatus to analyze a document written in a natural language and analyze preferential correction points and quality of the document. An example of the document analysis technique is disclosed in
この特許文献1に開示された日本語文章修正装置は、機械翻訳し易い構成に関するルールが登録された文章構成データベースと、機械翻訳し易い用字・用語に関するルールが登録された用字・用語データベースと、機械翻訳し易いスタイルに関するルールが登録されたスタイルデータベースと、修正箇所抽出手段と、表示手段と、修正手段と、出力手段と、を有する。このような構成を有する類似表現抽出装置は、次のように動作する。
The Japanese sentence correction device disclosed in
修正箇所抽出手段は、読み込む日本語原文章から、「文を、述語の数だけ作成する」といった上記構成に関するルール、「文は、当て字、誤字、脱字を含まない」といった上記用字・用語に関するルール、または「文は、曖昧な語句を含まない」といった上記スタイルに関するルールに反する構成、用字・用語またはスタイルを抽出する。 The correction part extraction means relates to the above-mentioned rules such as “create a sentence by the number of predicates” from the original Japanese text to be read, and the above-mentioned script / terms such as “the sentence does not include any characters, typographical errors, or omissions”. A configuration, script, term, or style that violates a rule or a rule relating to the style such as “the sentence does not include an ambiguous phrase” is extracted.
表示手段は、上記抽出された構成、用字・用語またはスタイルを表示する。 The display means displays the extracted configuration, script / term or style.
修正手段は、外部から入力されたデータを用いて上記抽出された構成、用字・用語またはスタイルを訂正、追加または削除して上記日本語原文章を修正する。 The correcting means corrects the original Japanese sentence by correcting, adding, or deleting the extracted configuration, script, term, or style using data input from the outside.
出力手段は、修正により得られた翻訳易文章を出力する。 The output means outputs an easy-to-translate sentence obtained by the correction.
このような構成により、日本語原文章から上記各ルールに反するポイントを抽出・表示し、外部からの訂正、追加、削除といった修正を支援している。 With this configuration, points that violate the above rules are extracted and displayed from the original Japanese text, and corrections such as external correction, addition, and deletion are supported.
さらに、文書分析技術の他の例が、特許文献2〜特許文献5に開示されている。
Further, other examples of the document analysis technique are disclosed in
特許文献2は、データベースに管理されている情報の概念を、各概念の抽象度に応じた配列でオントロジーに登録することで、多種多様なデータベースの追加や削除が頻繁に行われるような場合であっても、データベース選択メニューの維持管理が容易となる技術を開示する。
In
特許文献3は、検索に際して単語間の概念階層を考慮することにより、適切な検索が可能となる技術を開示する。
特許文献4は、次に入力したい単語の最初の読み情報の所定前に位置する単語からデータベースを参照して入力したい単語を予測表示することで、ユーザがより容易に文章を作成可能な技術を開示する。
特許文献5は、テキスト文書作成時に、作成中のテキスト文書中の任意の文字列に機械的処理に有用な情報(付加情報)を埋め込む等することにより、自動翻訳、自動抄録作成処理等の機械的処理に適したテキスト文書を作成可能な技術を開示する。
特許文献1〜5に記載の技術の課題は、「等」、「など」、「とか」又は「以外」といった曖昧語を含む文書の優先的な修正点や品質の推定の精度が低いことである。
The problem of the techniques described in
その理由は、「等」、「など」、「とか」又は「以外」といった省略された概念を文脈から読み手に推定させる作用を持つ曖昧語は、文章内での使われ方で文書の品質に与える影響の大きさが異なるためである。そのため、特許文献1に記載の技術のように登録された曖昧語の有無を検出する方法では、各使用場面で曖昧語が文書の品質に与える影響の大きさを考慮できない。
The reason for this is that ambiguous words that have the effect of causing the reader to infer the abbreviated concepts such as “etc.”, “etc.”, “toka” or “other than” are used in the text to improve the quality of the document. This is because the magnitude of the effect is different. Therefore, the method for detecting the presence or absence of a registered ambiguous word as in the technique described in
なお、ここでの文書の品質とは、文書の書き手と読み手の間における理解の齟齬の起きにくさや、文書の読み手にとっての理解のしやすさといった、少なくとも非曖昧さを含む特徴であって、文書の情報伝達の性能に関わる特徴を指す。 Note that the quality of the document here is a feature that includes at least unambiguous characteristics such as difficulty of understanding between the writer and reader of the document and ease of understanding for the reader of the document. This refers to the characteristics related to the performance of document information transmission.
以上より、本発明の目的は、曖昧語を含む文書について、各使用場面で曖昧語が文書の品質に与える影響の大きさを考慮して、精度よく文書の優先的な修正点や品質を推定することが可能な文書分析システム、文書分析方法およびプログラムを提供することにある。 As described above, the object of the present invention is to accurately estimate preferential correction points and quality of a document including ambiguous words in consideration of the magnitude of the influence of ambiguous words on the quality of the document in each use scene. An object of the present invention is to provide a document analysis system, a document analysis method, and a program that can be used.
上記目的を達成するため、本発明に係る文書分析システムは、外部から入力された文書を構成する文章に使用されている各単語の単語情報に基づいて、前記文書中における、省略された概念を文脈から読み手に推定させる作用を持つ単語である曖昧語を検索し、曖昧語が有る場合は当該曖昧語を抽出する曖昧語検索部と、前記曖昧語抽出部が抽出した各曖昧語よって省略された概念を読み手が推定する際に手掛かりとなる単語である推定鍵語を抽出するための推定鍵語抽出ルールに基づいて、文書から前記各曖昧語に対するそれぞれの推定鍵語を抽出する推定鍵語抽出部と、推定鍵語の概念の規模を推定するための概念規模推定ルールに基づいて、前記推定鍵語抽出部で抽出された推定鍵語の概念の規模である概念規模指標を推定する概念規模推定部と、前記概念規模指標に基づいて、前記各曖昧語と推定鍵語との組合せ毎に曖昧性情報を算出する曖昧性算出部と、を含む
上記目的を達成するため、本発明に係る文書分析方法は、外部から入力された文書を構成する文章に使用されている各単語の単語情報に基づいて、前記文書中における、省略された概念を文脈から読み手に推定させる作用を持つ単語である曖昧語を検索し、曖昧語が有る場合は当該曖昧語を抽出し、前記抽出した各曖昧語によって省略された概念を読み手が推定する際に手掛かりとなる単語である推定鍵語を抽出するための推定鍵語抽出ルールに基づいて、文書から前記各曖昧後に対するそれぞれの推定鍵語を抽出し、推定鍵語の概念の規模を推定するための概念規模推定ルールに基づいて、前記抽出した推定鍵語の概念の規模である概念規模指標を推定し、前記概念規模指標に基づいて、前記各曖昧語と推定鍵語との組合せ毎に曖昧性情報を算出する。
In order to achieve the above object, the document analysis system according to the present invention is based on word information of each word used in a sentence constituting a document input from the outside, and omits the omitted concept in the document. An ambiguous word, which is a word that has an action to be estimated by the reader from the context, is searched. Estimated key word that extracts each estimated key word for each ambiguous word from a document based on an estimated key word extraction rule for extracting an estimated key word that is a word that becomes a clue when a reader estimates the concept A concept for estimating a concept scale index, which is a scale of the concept of the estimated key word extracted by the estimated key word extraction section, based on a concept scale estimation rule for estimating the scale of the concept of the estimated key word Rule An ambiguity calculation unit that calculates ambiguity information for each combination of each of the ambiguous words and the estimated key word based on the concept scale index. The document analysis method is a word having an action of causing a reader to estimate an omitted concept from a context based on word information of each word used in a sentence constituting a document inputted from the outside. A certain ambiguous word is searched, and when there is an ambiguous word, the ambiguous word is extracted, and an estimated key word that is a clue when a reader estimates a concept omitted by each extracted ambiguous word is extracted. Based on the estimated key word extraction rule for extracting each estimated key word for each after ambiguity from the document and extracting based on the concept size estimation rule for estimating the size of the concept of the estimated key word Estimated Estimates the concept scale index is a scale word concept, on the basis of the concept scale index is calculated ambiguity information the every combination of the ambiguous word and the estimated key word.
上記目的を達成するため、本発明に係るプログラムは、外部から入力された文書を構成する文章に使用されている各単語の単語情報に基づいて、前記文書中における、省略された概念を文脈から読み手に推定させる作用を持つ単語である曖昧語を検索し、曖昧語が有る場合は当該曖昧語を抽出し、前記抽出した各曖昧語によって省略された概念を読み手が推定する際に手掛かりとなる単語である推定鍵語を抽出するための推定鍵語抽出ルールに基づいて、文書から前記各曖昧後に対するそれぞれの推定鍵語を抽出し、推定鍵語の概念の規模を推定するための概念規模推定ルールに基づいて、前記抽出した推定鍵語の概念の規模である概念規模指標を推定し、前記概念規模指標に基づいて、前記各曖昧語と推定鍵語との組合せ毎に曖昧性情報を算出する、処理をコンピュータに実行させる。 In order to achieve the above object, the program according to the present invention is based on the word information of each word used in the sentence constituting the document input from the outside, and omits the omitted concept in the document from the context. Search for ambiguous words, which are words that have an action to be estimated by the reader. If there is an ambiguous word, the ambiguous word is extracted, and this is a clue when the reader estimates a concept omitted by each extracted ambiguous word. Based on an estimated key word extraction rule for extracting an estimated key word that is a word, each estimated key word for each after ambiguity is extracted from the document, and a concept scale for estimating the concept size of the estimated key word Based on the estimation rule, a concept scale index that is the scale of the concept of the extracted estimated key word is estimated, and based on the concept scale index, ambiguity information is obtained for each combination of each ambiguous word and the estimated key word. And out, to perform the processing to computer.
本発明によれば、曖昧語を含む文書について、各使用場面で曖昧語が文書の品質に与える影響の大きさを考慮して、精度よく文書の優先的な修正点や品質を推定することができる。 According to the present invention, it is possible to accurately estimate preferential correction points and quality of a document including ambiguous words in consideration of the magnitude of influence of the ambiguous word on the document quality in each use scene. it can.
[実施形態1]
まず、本発明の実施形態1について、図1〜図3を参照して説明する。
[Embodiment 1]
First,
図1は、本発明の実施形態1に係る文書分析システム100の構成を示すブロック図である。
FIG. 1 is a block diagram showing a configuration of a
図1を参照すると、本発明の実施形態1に係る文書分析システム100は、文書入力部10、単語分析部20、曖昧語検索部30、推定鍵語抽出部40、概念規模推定部50、曖昧性算出部60、曖昧性出力部70、曖昧語データベース110及び概念データベース120を含む。文書分析システム100は、上述の各構成要素を、単一の電子機器内又はサーバ及び電子機器並びにこれらを相互に接続するインターネット等の情報通信ネットワークからなるシステム内に、含んでいても良い。
Referring to FIG. 1, a
文書分析システム100は、曖昧語を含む文書について、各使用場面で曖昧語が文書の品質に与える影響の大きさを考慮し、文書の優先的な修正点や品質を推定する、文書分析システムである。ここで、「曖昧語」とは、「等」、「など」、「とか」又は「以外」といった省略された概念を文脈から読み手に推定させる作用を持つ単語をいう。
The
単一の電子機器で文書分析システム100を構成する場合、文書分析システム100は、プログラム制御により動作するコンピュータで実現可能である。
When the
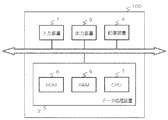
図2は、文書分析システム100を単一の電子機器で実現する場合のハードウェア構成を示す図である。図2に示すように、文書分析システム100は、データを入力する入力装置1、データ処理装置2、データ処理装置2での処理結果を出力する出力装置3及び種々のデータベースとして働く記憶装置4を含む。
FIG. 2 is a diagram showing a hardware configuration when the
データ処理装置2は、プログラムを記憶するリードオンリメモリ5(ROM5)、データを一時的に記憶するワークエリアとして使用されるランダムアクセスメモリ6(RAM6)及びROM5に記憶されたプログラムに従って、RAM6に記憶されているデータを処理する中央処理装置7(CPU7)を含む。
The
入力装置1は、文書入力部10の一部を構成する。また、データ処理装置2は、文書入力部10、単語分析部20、曖昧語検索部30、推定鍵語抽出部40、概念規模推定部50及び曖昧性算出部60として動作し、記憶装置4は曖昧語データベース110及び概念データベース120として動作し、出力装置3は曖昧性出力部70として動作しても良い。
The
次に、文書分析システム100を構成する各構成要素についてさらに詳細に説明する。
Next, each component constituting the
文書入力部10は、文書データを受け付ける。文書入力部10がデータとして受け付ける文書は、どのような文書であっても良いが、基本的には曖昧語を含む可能性が有り優先的な修正点や品質を分析する対象とする文書である。また、ここで言う文書は、複数の文書の束である文書群でも良い。具体的には、文書入力部10は、入力装置1とCPU7とを含む。入力装置1が文書を入力すると、CPU7は、その文書データをRAM6に格納する。
The
単語分析部20は、文書入力部10で入力された文書(文書データ)から、当該文書を構成する文章に使用されている単語に関する情報である単語情報を抽出する。この抽出は、データ処理部のCPU7によるプログラム制御に基づいて実行される。単語分析部20は、入力された文書を構成する文章に対して、例えば形態素解析や構文解析を適用することで、各文章に使用されている全単語の単語情報の抽出を行っても良い。
The
ここで、単語は名詞、動詞、形容詞など単独で意味をなす自立語だけでなく、助詞などを含んでも良い。単語情報は、使用されている単語そのものの情報を含む。単語情報は、単語の存在位置に関する情報を含んでも良い。単語の存在位置に関する情報とは、使用箇所が同定可能な情報であればよく、単語の存在する文の出現順位や頁、目次上の章や節、項などが該当する。 Here, the word may include not only a self-supporting independent word such as a noun, a verb, and an adjective, but also a particle. The word information includes information on the word itself being used. The word information may include information regarding the location of the word. The information related to the position of the word may be information that can identify the use location, and corresponds to the order of appearance of the sentence in which the word exists, the page, the chapter, the section, and the item on the table of contents.
また、単語情報は、必要に応じて単語毎の品詞、格、組み合される助詞、単語間の係り受け関係などを含めても良い。 Further, the word information may include a part of speech, a case, a particle to be combined, a dependency relationship between words, and the like as necessary.
曖昧語データベース110は、曖昧語を格納する。曖昧語データベース110は、特定の単語に関する後述する曖昧語検索部30からの問い合わせに対し、問い合わせ対象の単語が曖昧語として登録されているか検索し応答するデータベースであっても良い。なお、曖昧語データベース110は、インターネット上のデータベースであっても良い。
The
曖昧語検索部30は、曖昧語データベース110を参照して、単語分析部20で抽出された単語情報、すなわち、各文章に使用されている全単語の単語情報に基づいて、曖昧語を検索する。さらに、検索の結果、曖昧語が曖昧語データベース110に有る場合、曖昧語検索部30は、当該曖昧語を抽出する。また、曖昧語検索部30は、曖昧語と合わせて、曖昧語を含む文の出現順位や頁、目次上の章や節、項などに関する情報である、曖昧語の存在位置に関する情報を抽出しても良い。
The ambiguous
推定鍵語抽出部40は、曖昧語検索部30が抽出した各曖昧語について、推定鍵語抽出ルールに基づいて、文書から推定鍵語を抽出する。推定鍵語とは、曖昧語によって省略された概念を読み手が推定する際に手掛かりとなる単語である
ここで、推定鍵語抽出ルールは、曖昧語によって省略された概念を読み手が推定する際に手掛かりとなる単語を抽出するルールであればどの様なルールでも良い。推定鍵語抽出ルールは、例えば、曖昧語の直前に存在する単語又は曖昧語によって修飾される単語(被修飾語)を推定鍵語とするルールでも良い。推定鍵語抽出ルールは、曖昧語の直前に存在する単語と係り受けの関係にある単語又は曖昧語を含む文の主語や述語などのいずれかに該当する単語を推定鍵語とするルールでも良い。又は、推定鍵語抽出ルールは、上述の推定鍵語とされる単語の組合せを推定鍵語とするルールでも良い。
The estimated key
概念データベース120は、収集された単語の概念分類および一般的な同義語、類義語、用法などの一般概念情報を格納する。概念データベース120は、特定の単語に関する問い合わせに対し、単語の一般概念情報を検索し応答するデータベースであっても良い。概念データベース120は、単語の上位関係及び下位関係、部分関係及び全体関係、同義関係又は類義関係などによって単語を分類し、体系づけたシソーラスなどでも良い。なお、概念データベース120は、インターネット上のデータベースであっても良い。
The
概念規模推定部50は、推定鍵語抽出部40で抽出された推定鍵語を受信し、概念データベース120を参照することにより得られた、推定鍵語に関する一般概念情報、及び所定の概念規模推定ルールに基づいて、推定鍵語の概念の規模である概念規模指標を推定する。
The concept
ここで、概念規模指標の推定を行う「概念規模推定ルール」は、推定鍵語の概念の相対的な大きさを推定できるルールであれば良い。例えば、概念規模推定ルールは、同義語の個数または類義語の個数を概念規模指標とするルールでも良い。 Here, the “concept scale estimation rule” for estimating the concept scale index may be a rule that can estimate the relative size of the concept of the estimated key word. For example, the concept scale estimation rule may be a rule that uses the number of synonyms or the number of synonyms as a concept scale index.
又は、概念データベース120として複数の階層での概念が一般概念情報として登録されたシソーラスを用いて概念ベクトルを作成した場合、概念規模推定ルールは、階層の高さと単調増加の関係にある値を概念規模指標とするルールでも良い。具体的には、概念規模推定ルールは、各推定鍵語の属する最も高い概念分類上の階層を用いて、最も高い概念分類が大分類の場合は5、中分類の場合は4、小分類の場合は3、語句の場合は2、登録がない場合は1に設定する。このように、概念規模推定ルールは、階層の高さと単調増加の関係にある値を概念規模指標とするルールでも良い。又は、概念規模推定ルールは、各推定鍵語の属する概念分類の下位分類に登録されている単語の総数などを概念規模指標とするルールでも良い。
Alternatively, when a concept vector is created using a thesaurus in which concepts at a plurality of levels are registered as general concept information in the
曖昧性算出部60は、概念規模推定部50で推定した概念規模指標に基づいて、各推定鍵語と曖昧語の組合せ毎に曖昧性情報を算出する。
The
ここで、曖昧性情報は、各推定鍵語と曖昧語の組合せ毎の、曖昧性に関する指標である曖昧性指標でも良い。たとえば、曖昧性指標は、概念規模指標と単調増加の関係となる関数で導かれる曖昧性に関する指標である。曖昧性情報は、曖昧性指標に加えて、入力した文書における推定鍵語及び曖昧語の位置などに関する情報を含んでも良い。又は、曖昧性情報は、各推定鍵語と曖昧語の組合せ毎の曖昧性指標を、文書全体または任意の範囲で集計した指標であって、かつ、文書の品質を表す指標でも良い。 Here, the ambiguity information may be an ambiguity index that is an index related to ambiguity for each combination of each estimated key word and ambiguous word. For example, the ambiguity index is an index related to ambiguity that is derived by a function that has a monotonically increasing relationship with the concept scale index. In addition to the ambiguity index, the ambiguity information may include information on the estimated key word and the position of the ambiguous word in the input document. Alternatively, the ambiguity information may be an index that represents the ambiguity index for each combination of the estimated key word and the ambiguous word in the entire document or in an arbitrary range and represents the quality of the document.
曖昧性出力部70は、曖昧性算出部60で算出した曖昧性情報を出力する。出力形態は、所要の形態で出力すれば良い。例えば、曖昧性出力部70は、文書内における各推定鍵語と曖昧語の組合せについて、色分け、太字による強調又は文字の拡大などによる明示といった加工を施して、当該加工が施された文書全体を出力しても良い。
The
又は、曖昧性出力部70は、各推定鍵語と曖昧語の組合せを抽出した表を出力しても良い。曖昧性出力部70は、曖昧性指標が任意に設定された閾値より大きい各推定鍵語と曖昧語の組合せのみに限定して出力しても良い。曖昧性出力部70は、曖昧性指標に基づく色分けや、太字による強調、又は単語の文字の大きさへの強弱の付与などを行っても良い。
Alternatively, the
各推定鍵語と曖昧語の組合せ毎の曖昧性指標を文書全体または任意の範囲で集計した指標であって、文書の品質を表す指標を曖昧性情報として出力する場合、曖昧性出力部70は、曖昧性情報を表形式で出力しても良い。
When an ambiguity index for each combination of each estimated key word and ambiguous word is an index obtained by tabulating the entire document or an arbitrary range, and an index indicating the quality of the document is output as ambiguity information, the
または、曖昧性出力部70は、ユーザによる各出力形態の選択を受け付けて、ベースとなる表示形態から必要に応じて表に移行できるように構成されても良い。また、曖昧性出力部70は、必要に応じて動詞や名詞などを選択的に出力するようにしても良い。
Alternatively, the
曖昧性出力部70は、曖昧性情報を出力するとともに、ユーザによる文章の修正を受け付けても良い。
The
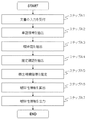
次に、図3のフローチャートを参照して、本発明の実施形態1に係る文書分析システム100の全体の動作について詳細に説明する。なお、図3に示すフローチャート及び以下の説明は処理の一例であり、適宜求める処理に応じて処理順等を入れ替えたり処理を戻したり繰り返したりすることを行っても良い。
Next, the overall operation of the
文書入力部10は、分析の対象とする文書の入力を受け付ける(ステップA1)。
The
単語分析部20は、文書を構成する各文章に形態素解析や構文解析を適用することで、各文章に使用されている全単語の単語情報の抽出を行う(ステップA2)。
The
曖昧語検索部30は、単語分析部20で抽出された各文章に使用されている全単語の単語情報に基づいて、文書中の曖昧語の有無について曖昧語データベース110を参照し、曖昧語が有る場合は当該曖昧語を抽出する(ステップA3)。
The ambiguous
推定鍵語抽出部40は、各曖昧語について推定鍵語抽出ルールに基づき、曖昧語によって省略された概念を読み手が推定する際に手掛かりとなる単語を推定鍵語として抽出する(ステップA4)。
The estimated key
概念規模推定部50は、推定鍵語の一般概念情報について概念データベース120を参照し、得られた一般概念情報及び所定の概念規模推定ルールに基づいて、推定鍵語の概念の規模である概念規模指標を推定する(ステップA5)。
The conceptual
曖昧性算出部60は、概念規模推定部50が推定した概念規模指標に基づいて、各推定鍵語と曖昧語の組合せ毎に曖昧性情報を算出する(ステップA6)。
The
曖昧性出力部70は、曖昧性算出部60が算出した曖昧性情報を出力する(ステップA7)。
The
以上説明したように、実施形態1に係る文書分析システム100によれば、曖昧語を含む文書について、各使用場面で曖昧語が文書の品質に与える影響の大きさを考慮し、精度よく文書の優先的な修正点や品質を推定することが可能になる。、
その理由は、推定鍵語抽出部40が文書において曖昧語によって省略された概念を読み手が推定する際に手掛かりとなる単語を推定鍵語として抽出し、概念規模推定部50が推定鍵語の概念の規模である概念規模指標を推定するからである。各推定鍵語と曖昧語の組合せ毎に曖昧性指標を算出することで、文書分析システム100は、文書の品質に影響を与える文章内での曖昧語の使われ方まで考慮した分析が可能になる。
As described above, according to the
The reason is that the estimated key
[実施形態2]
次に、本発明の実施形態2について、図4を参照して説明する。
[Embodiment 2]
Next,
図4は、本発明の実施形態2に係る文書分析システム200の構成を示すブロック図である。
FIG. 4 is a block diagram showing a configuration of the
図4を参照すると、本発明の実施形態2に係る文書分析システム200は、曖昧語検索部35、推定鍵語抽出部45、概念規模推定部55及び曖昧性算出部65を含む。
Referring to FIG. 4, the
曖昧語検索部35は、外部から入力された文書を構成する文章に使用されている各単語の単語情報に基づいて、文書中における、省略された概念を文脈から読み手に推定させる作用を持つ単語である曖昧語を検索し、曖昧語が有る場合は当該曖昧語を抽出する。
The ambiguous
推定鍵語抽出部45は、曖昧語抽出部35が抽出した各曖昧語によって省略された概念を読み手が推定する際に手掛かりとなる単語である推定鍵語を抽出するための推定鍵語抽出ルールに基づいて、文書から各曖昧語に対するそれぞれの推定鍵語を抽出する。
The estimated key
概念規模推定部55は、推定鍵語の概念の規模を推定するための概念規模推定ルールに基づいて、推定鍵語抽出部45で抽出された推定鍵語の概念の規模である概念規模指標を推定する。
The conceptual
曖昧性算出部65は、概念規模推定部55で推定された概念規模指標に基づいて、各推定鍵語と曖昧語の組合せ毎に曖昧性情報を算出する。
The
以上説明したように、文書分析システム200によれば、曖昧語を含む文書について、各使用場面で曖昧語が文書の品質に与える影響の大きさを考慮して、精度よく文書の優先的な修正点や品質を推定することができる。
As described above, according to the
なお、本発明に係る文書分析方法は、上述した文書分析システム100又は文書分析システム200が実行する動作方法である。また、本発明に係るプログラムは、実施形態1又は実施形態2において説明した各動作を、コンピュータに実行させるプログラムであれば良い。
The document analysis method according to the present invention is an operation method executed by the
[実施例]
次に、図5乃至図12を参照して、具体的な実施例を用いて、本発明の実施形態1に係る文書分析システム100の動作について説明する。
[Example]
Next, the operation of the
本実施例では、次のことを目的としている。 The purpose of this embodiment is as follows.
先ず、文書分析システム100は、情報システム構築に関する提案書や仕様書といった、曖昧な箇所を排除すべき文書D内で、曖昧語Waが文書Dの品質に与える曖昧性である曖昧性指標IAを各曖昧語Waの使用場面毎に算出する。曖昧語Waは、「等」、「など」、「とか」又は「以外」といった省略された概念を文脈から読み手に推定させる作用を持つ単語である。
First, the
文書分析システム100は、算出した曖昧性指標IAに基づき、各曖昧語の文書中の位置や曖昧性の程度に関する曖昧性情報Aを推定する。文書分析システム100は、推定された曖昧性情報Aを出力することで、文書Dにおける優先的に修正すべき曖昧箇所の把握や、複数の文書間の比較として品質の低い文書の明確化などを容易にし、文書の改善を効率化する。
Based on the calculated ambiguity index IA, the
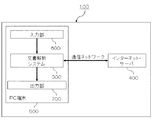
また、本実施例では、文書分析システム100は、図5に示されるように、文書解析システム300と、インターネット・サーバ400とを含むものとする。
In this embodiment, the
文書解析システム300は、分析実施者Bの持つPC端末500上で動作し、入力部600及び出力部700を介して、分析実施者Bが曖昧性指標Aを推定したい文書群を構成する文書の入力と、曖昧性情報Aの提示を実現する。
The
インターネット・サーバ400は、通信ネットワークを介して文書解析システム300を実装した分析実施者Bの持つPC端末500と接続されている。インターネット・サーバ400は、文書解析システム300からの単語の問い合わせに対し、曖昧語Waとしての登録の有無の検索を可能にする。また、インターネット・サーバ400は、単語の意味などの概念情報の問い合わせに対し、単語の概念分類や一般的な曖昧語や類義語、用法に関連する一般概念情報Cgの検索を可能にする。
The
次に、図5と図1との対応関係について説明する。 Next, the correspondence between FIG. 5 and FIG. 1 will be described.
文書入力部10、単語分析部20、曖昧語検索部30、推定鍵語抽出部40、概念規模推定部50及び曖昧性算出部60は、文書解析システム300内に含まれる。曖昧性出力部70は、出力部700として動作する。曖昧語データベース110及び概念データベース120は、インターネット・サーバ400内に含まれる。
The
この様な構成要素を含む文書解析システム300及びインターネット・サーバ400は、以下のように動作する。
The
文書解析システム300は、入力部600を介して、情報システム構築に関する提案書や仕様書といった、分析実施者Bが曖昧な箇所を排除するための曖昧性情報Aを得たい文書Dの入力を受け付ける。文書解析システム300は、文書Dを構成する文章毎に形態素解析及び構文解析を適用し、文書を構成する単語に分解し、その係り受け関係や格を解析することで、単語Wとその格、係り受け構造等を単語情報として抽出する。なお、ここでの「単語」は、「に関連する」のような複数の単語からなる表現などを含んでも良い。さらに、文書解析システム300は、文書の文の出現順に通し番号として文番号を付け、各単語を含む文の文番号を単語情報に加える。
The
インターネット・サーバ400は、省略された概念を文脈から読み手に推定させる作用を持つ曖昧語や曖昧表現に関する情報である曖昧語情報Caを格納する。また、インターネット・サーバ400は、任意の単語や表現の情報を抽出する検索エンジンなどの機能も有することで、文書解析システム300からの問い合わせに応じて、問い合わせ対象の単語が曖昧語情報Caに存在するかどうかを判定し、提示しても良い。
The
なお、抽出する曖昧語は省略された概念を文脈から読み手に推定させる作用を持つ曖昧語であれば何でも良い。曖昧語は、例えば、「等」、「など」、「とか」、「以外」、「といった」、「みたいな」などの単語が該当する。また、曖昧語は、「のような」、「に関する」、「に関連する」、「に関わる」などの助詞と組み合された複数の単語からなる表現などを含んでも良い。 The ambiguous word to be extracted may be any ambiguous word as long as it has the effect of allowing the reader to infer the omitted concept from the context. The ambiguous word corresponds to a word such as “etc.”, “etc.”, “toka”, “other than”, “like”, “like”, and the like. The ambiguous word may also include an expression made up of a plurality of words combined with particles such as “like”, “related”, “related to”, “related to” and the like.
文書解析システム300は、文書Dに含まれる全ての単語Wi(i=1、2、・・・、n)についてインターネット・サーバ400に曖昧語情報Caの曖昧語に該当する単語であるかどうかを問い合わせる。文書解析システム300は、曖昧語に該当するという判定結果となった単語Wj(j=1、2、・・・、m)を曖昧語Waj(j=1、2、・・・、m)とし、曖昧語の存在する文の文番号と共に抽出する。なお、文書D内に同一の曖昧語が複数回使用されていた場合も使用場面はそれぞれ異なるため、文書解析システム300は、複数の同一の曖昧語を別々に抽出する。
The
例えば、文書Dの一部が「本購買システムは国内拠点と海外支社間の物流業務の効率化を目的としている。開発担当者は本システムの性能を関連する文書等の要件を満たすようにすること。また要件に変更が有れば、都度協議する。協議結果、変更が生じた場合は議事録等に記載し、開発物はこの記載に沿うように開発を行う。開発システムの入力、出力等は旧システムと同じとする。新たな処理として新法に対応するため輸出規定に該当するかどうかの判定などが加わる。他にも簿価の計算式の係数などを旧版値から換算する必要がある。これらの処理の他には機能面に大きな変化などは無い。」という文面からなる場合を考える。この文書に関して、文書解析システム300は、図6に示すように、一文毎に文番号を付与し、曖昧語が存在する文に関しては、各文の文番号に対応して曖昧語Wajを記載した表を作成することで、曖昧語を抽出しても良い。
For example, a part of document D is “This purchasing system is aimed at improving the efficiency of logistics operations between domestic bases and overseas branches. The developer should satisfy the requirements of the related documents etc. for the performance of this system. If there are any changes in the requirements, we will discuss each case.If there are any changes, we will describe the changes in the minutes, etc., and develop the developed product according to this description. As a new process, it will be necessary to convert the coefficient of the book value calculation formula from the old version value in order to comply with the new law as a new process. There is no major change in the functional aspects other than these processes. " As shown in FIG. 6, the
文書解析システム300は、曖昧語によって省略された概念を読み手が推定する際に手掛かりとなる推定鍵語Wbjとして、曖昧語Wajの直前に存在する単語を抽出する。例えば、図6の事例で有れば、文書解析システム300は、推定鍵語Wbjとして図7の一番右の列に示すような単語を抽出する。
The
曖昧語Wajの直前に存在する単語を推定鍵語Wbjとすることが有効な理由は、「文書等」という表記が有った時、読み手は「文書」に類するその他のものを推定することになるためである。 The reason why it is effective to use the word existing immediately before the ambiguous word Waj as the estimated key word Wbj is that when there is a notation “document etc.”, the reader estimates other things similar to “document”. It is to become.
又は、文書解析システム300は、曖昧語Wajの直前に存在する単語と係り受け関係を持っている単語を推定鍵語Wbjとして抽出しても良い。例えば、図6の事例で有れば、文書解析システム300は、推定鍵語Wbjとして図8の一番右の列に示すような単語を抽出する。
Alternatively, the
曖昧語Wajの直前に存在する単語と係り受け関係を持っている単語を推定鍵語Wbjとすることが有効な理由は、「係数などを旧版値から換算する」という表記が有った時、読み手は「換算する」という動作がそぐうものを推定することになるためである。 The reason why it is effective to use the word having a dependency relationship with the word existing immediately before the ambiguous word Waj as the estimated key word Wbj is that there is a notation of “convert coefficients from old version values”, This is because the reader estimates that the operation of “converting” is appropriate.
なお、推定鍵語Wbjは曖昧語Wajに対して少なくとも一つ抽出されれば良いが、文書解析システム300は、一つの曖昧語に対して複数の推定鍵語Wbjを抽出しても良い。
Note that at least one estimated key word Wbj may be extracted for the ambiguous word Waj, but the
インターネット・サーバ400は、単語の一般的な上位関係及び下位関係、部分関係及び全体関係、同義関係又は類義関係などによって単語を分類し、体系づけたシソーラスの一般概念情報Cgを格納する。また、インターネット・サーバ400は、任意の単語の情報を抽出する検索エンジンなどの機能も有することで、文書解析システム300からの問い合わせに応じて、一般概念情報Cgを抽出し、提示しても良い。具体的には、インターネット・サーバ400は、問い合わせ対象の単語の一般的な概念分類として「大分類」、「中分類」、「小分類」、「語句」といった分類及び当該分類に帰属する単語の数を一般概念情報Cgとして抽出し、提示しても良い。
The
文書解析システム300は、推定鍵語Wbjのそれぞれの一般概念情報Cgについてインターネット・サーバ400に問い合わせを行う。文書解析システム300は、インターネット・サーバ400内に保存されたシソーラスの一般概念情報Cgの分類体系から、各推定鍵語Wbjが属する最も高い概念分類を抽出する。文書解析システム300は、その概念分類の下位分類に登録されている単語の個数を概念規模指標Ibjの値として抽出する。
The
例えば、「文書」という推定鍵語Wbjが一般概念情報Cgの分類体系では「小分類」に分類されている場合、その下位分類である「語句」とその同義語として登録されている単語を抽出する。「文書」という推定鍵語Wbjの下位分類である語句とその同義語として、例えば「書状」、「書類」、「ドキュメント」、「公文書」、「私文書」、「私書」、「契約書」、「覚書」、・・・・といった単語が、計156個存在するとする。本実施例においては、文書解析システム300は、156という値を概念規模指標Ibjの値とする。
For example, when the presumed key word Wbj “document” is classified as “small category” in the classification system of the general concept information Cg, the word “phrase” that is a subordinate category and the word registered as its synonym are extracted. To do. For example, “letter”, “document”, “document”, “official document”, “private document”, “private document”, “contract” are terms and synonyms that are subclasses of the presumed key word Wbj “document”. It is assumed that there are a total of 156 words such as “call”, “memorandum”,. In this embodiment, the
また、「議事録」のように推定鍵語Wbjが一般概念情報Cgの分類体系で「語句」に分類されている場合、下位に帰属する単語は無いので、文書解析システム300は概念規模指標を1としても良い。又は、文書解析システム300は、「議事録」の同義語や類義語として登録されている語を一般概念情報Cgから抽出し、抽出できた単語の数を概念規模指標としても良い。例えば、「議事録」の同義語又は類義語として「メモ」、「記録」及び「会議録」の3語が得られたとすると、文書解析システム300は、概念規模指標Ibjの値を3としても良い。一般概念情報Cgの分類体系に存在しない単語の場合は帰属する単語は無いので、文書解析システム300は概念規模指標を1としても良い。
Further, when the estimated key word Wbj is classified as “word / phrase” in the classification system of the general concept information Cg as in “minutes”, the
図7の事例で有れば、概念規模指標Ibjは図9の一番右の列に示すように、図8の事例で有れば、概念規模指標Ibjは図10の一番右の列に示すように算出される。 In the case of FIG. 7, the conceptual scale index Ibj is shown in the rightmost column of FIG. 9, and in the case of FIG. 8, the conceptual scale index Ibj is in the rightmost column of FIG. Calculated as shown.
または、文書解析システム300は、曖昧語Wajの直前に存在した単語と、曖昧語Wajの直前に存在する単語と係り受け関係を持っている単語の両方を推定鍵語Wbjとして抽出しても良い。この場合は、文書解析システム300は、複数の概念規模指標Ibjと単調増加の関係が維持される相加平均や相乗平均のような関数で、同一の曖昧語Wajに関するそれぞれの推定鍵語Wbjに対応する概念規模指標Ibjを集約した値を、改めて最終的な概念規模指標Ibjとしても良い。
Alternatively, the
次に文書解析システム300は、推定した各曖昧語Wajに対応する概念規模指標Ibjを文書内での概念規模指標Ibの最大値Ibmaxで除して正規化した値を、各推定鍵語Wbjと曖昧語Wajの組合せ毎の曖昧性指標Iajとして算出する。文書解析システム300は、曖昧性指標Iaj及び曖昧語Wajの文番号を曖昧語Wajの曖昧性情報Ajとする。また、概念規模指標Ibjを文書全体で集計した値を文書Dの品質を表す曖昧性情報Adとして算出する。
Next, the
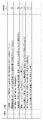
例えば、図9の事例で有れば、曖昧性情報Ajは図11のように算出される。図11は、「文書等」の部分が、「文書」という一般的な語では「等」の概念の推定範囲が広く曖昧性が高いことを示す。また、図10の事例で有れば、曖昧性情報Ajは図12のように算出される。図12は、「出力等は旧システムと同じ」の部分が、「同じ」という汎用性の高い語では「等」の概念を限定しにくく曖昧性が高いことを示す。 For example, in the case of FIG. 9, the ambiguity information Aj is calculated as shown in FIG. FIG. 11 shows that in the general word “document”, the “document etc.” part has a wide estimated range of the concept of “etc.” and is highly ambiguous. In the case of FIG. 10, the ambiguity information Aj is calculated as shown in FIG. FIG. 12 shows that the part of “the output etc. is the same as that of the old system” is highly ambiguous because it is difficult to limit the concept of “etc.” in the highly versatile word “same”.
文書解析システム300は、曖昧性情報Ajに基づき、「文書等」や「出力等は旧システムと同じ」など、文書D内における各推定鍵語Wbjと曖昧語Wajの組合せ部分を着色し明示することで、修正すべき曖昧な文の箇所を分かりやすくし表示する。また、文書解析システム300は、曖昧性情報Adに基づき、推定鍵語Wbjと曖昧語Wajの組合せの曖昧性情報Adを文書D全体および、目次の章単位などで集計して表もしくはグラフなどの形式で出力しても良い。当該出力により、文書解析システム300は、文書Dの品質を表すメトリクス(評価尺度)及び修正すべき曖昧な章を判断する情報を提供する。
Based on the ambiguity information Aj, the
以上、各実施形態及び実施例を参照して本発明を説明したが、本発明は以上の実施形態及び実施例に限定されるものではない。本発明の構成や詳細には、本発明のスコープ内で同業者が理解し得る様々な変更をすることができる。 As mentioned above, although this invention was demonstrated with reference to each embodiment and an Example, this invention is not limited to the above embodiment and Example. Various changes that can be understood by those skilled in the art can be made to the configuration and details of the present invention within the scope of the present invention.
本発明によれば、ソフトウェアやシステムの開発における要件定義などの作業においてやり取りされる各種文書に関して、文書の曖昧さを特に問題の大きい場所から優先的に修正することが可能になる。これにより文書作成や文書レビューの効率化に繋がる。また、複数の読み手の間に異なる解釈が起きる状況などが減少し、手戻りの減少や顧客満足の向上などシステム開発の効率化に関する用途に適用できる。 According to the present invention, it is possible to preferentially correct the ambiguity of various documents exchanged in operations such as requirement definition in software and system development from a particularly problematic place. This leads to the efficiency of document creation and document review. In addition, the situation in which different interpretations occur among multiple readers is reduced, and it can be applied to applications related to the efficiency of system development such as reduction of rework and improvement of customer satisfaction.
1 入力装置
2 データ処理装置
3 出力装置
4 記憶装置
5 ROM
6 RAM
7 CPU
10 文書入力部
20 単語分析部
30、35 曖昧語検索部
40、45 推定鍵語抽出部
50、55 概念規模推定部
60、65 曖昧性算出部
70 曖昧性出力部
100、200 文書分析システム
110 曖昧語データベース
120 概念データベース
300 文書解析システム
400 インターネット・サーバ
500 PC端末
600 入力部
700 出力部
1
6 RAM
7 CPU
DESCRIPTION OF
Claims (10)
前記曖昧語抽出部が抽出した各曖昧語よって省略された概念を読み手が推定する際に手掛かりとなる単語である推定鍵語を抽出するための推定鍵語抽出ルールに基づいて、文書から前記各曖昧語に対するそれぞれの推定鍵語を抽出する推定鍵語抽出部と、
推定鍵語の概念の規模を推定するための概念規模推定ルールに基づいて、前記推定鍵語抽出部で抽出された推定鍵語の概念の規模である概念規模指標を推定する概念規模推定部と、
前記概念規模指標に基づいて、前記各曖昧語と推定鍵語との組合せ毎に曖昧性情報を算出する曖昧性算出部と、
を含む文書分析システム。 Based on the word information of each word used in the sentences that make up the document input from the outside, search for ambiguous words that are words that have the effect of causing the reader to infer the omitted concepts from the context. When there is an ambiguous word, an ambiguous word search unit that extracts the ambiguous word,
Based on an estimated key word extraction rule for extracting an estimated key word that is a word that becomes a clue when a reader estimates a concept omitted by each ambiguous word extracted by the ambiguous word extraction unit, An estimated key word extraction unit that extracts each estimated key word for an ambiguous word;
A concept scale estimation unit for estimating a concept scale index, which is a concept scale of the estimated key word extracted by the estimated key word extraction unit, based on a concept size estimation rule for estimating a concept size of the estimated key word; ,
Based on the conceptual scale index, an ambiguity calculation unit that calculates ambiguity information for each combination of the ambiguous word and the estimated key word;
Document analysis system including.
前記文書から、当該文書を構成する文章に使用されている単語に関する情報である単語情報を抽出する単語分析部と、
省略された概念を文脈から読み手に推定させる作用を持つ単語である曖昧語を格納する曖昧語データベースと、
単語の一般概念情報を蓄積する概念データベースと、
曖昧性情報を出力する曖昧性出力部と、
をさらに含み、
前記曖昧語検索部は、前記単語分析部が抽出した単語情報及び前記曖昧語データベースに基づいて、前記曖昧語を抽出し、
前記概念規模推定部は、前記概念データベース及び所定の概念規模推定ルールに基づいて、前記概念規模指標を推定する、
請求項1に記載の文書分析システム。 A document input unit that accepts input of a document;
A word analysis unit that extracts word information, which is information about words used in sentences constituting the document, from the document;
An ambiguous word database that stores ambiguous words that are words that have the effect of causing the reader to infer the omitted concepts from the context;
A concept database that stores general concept information of words;
An ambiguity output unit that outputs ambiguity information;
Further including
The ambiguous word search unit extracts the ambiguous word based on the word information extracted by the word analysis unit and the ambiguous word database,
The conceptual scale estimation unit estimates the conceptual scale index based on the conceptual database and a predetermined conceptual scale estimation rule;
The document analysis system according to claim 1.
請求項1又は2に記載の文書分析システム。 The predetermined estimated key word extraction rule in the estimated key word extraction unit is a rule for extracting a word existing immediately before the ambiguous word or a word modified by the ambiguous word as the estimated key word.
The document analysis system according to claim 1 or 2.
前記推定鍵語抽出部における所定の推定鍵語抽出ルールは、曖昧語の直前に存在する単語と係り受けの関係にある単語又は曖昧語を含む文の主語若しくは述語を推定鍵語として抽出するルールである、
請求項1〜3のいずれか1項に記載の文書分析システム。 The word analysis unit performs morphological analysis and syntax analysis on the sentences constituting the document, thereby extracting the part of speech of each word and the dependency relationship between the words as the word information,
The predetermined estimated key word extraction rule in the estimated key word extraction unit is a rule for extracting, as an estimated key word, a subject or predicate of a sentence including an ambiguous word or a word having a dependency relationship with a word existing immediately before the ambiguous word Is,
The document analysis system according to claim 1.
請求項1〜4のいずれか1項に記載の文書分析システム。 The concept database is a thesaurus that stores synonym relations, synonym relations, upper relations and lower relations or partial relations and whole relations between words as general concept information.
The document analysis system of any one of Claims 1-4.
請求項5に記載の文書分析システム。 The predetermined conceptual scale estimation rule in the conceptual scale estimation unit estimates a value that is in a monotonically increasing relationship with the height of the hierarchy as the conceptual scale index using the highest conceptual classification hierarchy to which each estimated key word belongs. Is a rule,
The document analysis system according to claim 5.
請求項5に記載の文書分析システム。 The predetermined concept scale estimation rule in the concept scale estimation unit is a rule that uses the total number of words registered in the subclass of the concept class to which each estimated key word belongs as a concept scale index.
The document analysis system according to claim 5.
前記概念規模推定部における所定の概念規模推定ルールは、前記複数抽出した各推定鍵語について算出した概念規模指標のそれぞれについて、単調増加の関係が維持される関数で同一の曖昧語に関する推定鍵語の概念規模指標を集約した値を、最終的な概念規模指標として抽出するルールである、
請求項1〜7のいずれか1項に記載の文書分析システム。 The estimated key word extraction unit extracts a plurality of estimated key words for each ambiguous word by having a plurality of estimated key word extraction rules,
The predetermined conceptual scale estimation rule in the conceptual scale estimation unit is an estimated key word related to the same ambiguous word with a function that maintains a monotonically increasing relationship for each of the conceptual scale indices calculated for each of the extracted extracted estimated key words. This is a rule that extracts a value that aggregates the conceptual scale index of as a final conceptual scale index.
The document analysis system according to claim 1.
前記抽出した各曖昧語によって省略された概念を読み手が推定する際に手掛かりとなる単語である推定鍵語を抽出するための推定鍵語抽出ルールに基づいて、文書から前記各曖昧後に対するそれぞれの推定鍵語を抽出し、
推定鍵語の概念の規模を推定するための概念規模推定ルールに基づいて、前記抽出した推定鍵語の概念の規模である概念規模指標を推定し、
前記概念規模指標に基づいて、前記各曖昧語と推定鍵語との組合せ毎に曖昧性情報を算出する、
文書分析方法。 Based on the word information of each word used in the sentences that make up the document input from the outside, search for ambiguous words that are words that have the effect of causing the reader to infer the omitted concepts from the context. If there is an ambiguous word, extract the ambiguous word,
Based on an estimated key word extraction rule for extracting an estimated key word, which is a word that becomes a clue when a reader estimates a concept omitted by each extracted ambiguous word, Extract the estimated key words,
Based on the concept size estimation rule for estimating the concept size of the estimated key word, a concept size index that is the size of the extracted estimated key word concept is estimated,
Based on the conceptual scale index, calculate ambiguity information for each combination of each ambiguous word and estimated key word,
Document analysis method.
前記抽出した各曖昧語によって省略された概念を読み手が推定する際に手掛かりとなる単語である推定鍵語を抽出するための推定鍵語抽出ルールに基づいて、文書から前記各曖昧後に対するそれぞれの推定鍵語を抽出し、
推定鍵語の概念の規模を推定するための概念規模推定ルールに基づいて、前記抽出した推定鍵語の概念の規模である概念規模指標を推定し、
前記概念規模指標に基づいて、前記各曖昧語と推定鍵語との組合せ毎に曖昧性情報を算出する、
処理をコンピュータに実行させるプログラム。 Based on the word information of each word used in the sentences that make up the document input from the outside, search for ambiguous words that are words that have the effect of causing the reader to infer the omitted concepts from the context. If there is an ambiguous word, extract the ambiguous word,
Based on an estimated key word extraction rule for extracting an estimated key word, which is a word that becomes a clue when a reader estimates a concept omitted by each extracted ambiguous word, Extract the estimated key words,
Based on the concept size estimation rule for estimating the concept size of the estimated key word, a concept size index that is the size of the extracted estimated key word concept is estimated,
Based on the conceptual scale index, calculate ambiguity information for each combination of each ambiguous word and estimated key word,
A program that causes a computer to execute processing.
Priority Applications (1)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| JP2011252657A JP5811795B2 (en) | 2011-11-18 | 2011-11-18 | Document analysis system, document analysis method and program |
Applications Claiming Priority (1)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| JP2011252657A JP5811795B2 (en) | 2011-11-18 | 2011-11-18 | Document analysis system, document analysis method and program |
Publications (2)
| Publication Number | Publication Date |
|---|---|
| JP2013109475A true JP2013109475A (en) | 2013-06-06 |
| JP5811795B2 JP5811795B2 (en) | 2015-11-11 |
Family
ID=48706184
Family Applications (1)
| Application Number | Title | Priority Date | Filing Date |
|---|---|---|---|
| JP2011252657A Expired - Fee Related JP5811795B2 (en) | 2011-11-18 | 2011-11-18 | Document analysis system, document analysis method and program |
Country Status (1)
| Country | Link |
|---|---|
| JP (1) | JP5811795B2 (en) |
Cited By (1)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN113723085A (en) * | 2021-08-26 | 2021-11-30 | 北京航空航天大学 | Pseudo-fuzzy detection method in privacy policy document |
Citations (2)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| JPH01220063A (en) * | 1988-02-29 | 1989-09-01 | Fujitsu Ltd | System for evaluating document quality |
| JP2007122660A (en) * | 2005-10-31 | 2007-05-17 | Toshiba Corp | Document data processing apparatus and document data processing program |
-
2011
- 2011-11-18 JP JP2011252657A patent/JP5811795B2/en not_active Expired - Fee Related
Patent Citations (2)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| JPH01220063A (en) * | 1988-02-29 | 1989-09-01 | Fujitsu Ltd | System for evaluating document quality |
| JP2007122660A (en) * | 2005-10-31 | 2007-05-17 | Toshiba Corp | Document data processing apparatus and document data processing program |
Non-Patent Citations (3)
| Title |
|---|
| JPN6015023316; 沼倉 靖弘: '適材適所! テストツール100%活用法' ソフトウェア・テストPRESS 第10巻, 20100910, 101-104ページ, (株)技術評論社 * |
| JPN6015023317; 天野 富夫: 'IBMプロフェッショナル論文 3' PROVISION No.67, 20101101, 94-100ページ, 日本アイ・ビー・エム株式会社 * |
| JPN6015023318; 田添 丈博: '"'名詞'のような'名詞'"の分類と比喩性の判定モデル' 情報処理学会研究報告 Vol.2001 No.9, 20010126, 27-32ページ, 社団法人情報処理学会 * |
Cited By (2)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN113723085A (en) * | 2021-08-26 | 2021-11-30 | 北京航空航天大学 | Pseudo-fuzzy detection method in privacy policy document |
| CN113723085B (en) * | 2021-08-26 | 2024-05-24 | 北京航空航天大学 | A pseudo-fuzzy detection method in privacy policy documents |
Also Published As
| Publication number | Publication date |
|---|---|
| JP5811795B2 (en) | 2015-11-11 |
Similar Documents
| Publication | Publication Date | Title |
|---|---|---|
| JP6187877B2 (en) | Synonym extraction system, method and recording medium | |
| WO2019169858A1 (en) | Searching engine technology based data analysis method and system | |
| CN110297880B (en) | Corpus product recommendation method, apparatus, device and storage medium | |
| JPWO2014002775A1 (en) | Synonym extraction system, method and recording medium | |
| JP4534666B2 (en) | Text sentence search device and text sentence search program | |
| JP2019082931A (en) | Retrieval device, similarity calculation method, and program | |
| CN120045582B (en) | Query method based on query auxiliary information | |
| CN119829022A (en) | Method for generating front-end prototype based on artificial intelligence technology | |
| CN111694933A (en) | Conversation control system, conversation control method, and storage medium | |
| CN112732743A (en) | Data analysis method and device based on Chinese natural language | |
| JPWO2014002774A1 (en) | Synonym extraction system, method and recording medium | |
| JP6108212B2 (en) | Synonym extraction system, method and program | |
| JP5780036B2 (en) | Extraction program, extraction method and extraction apparatus | |
| JP5204203B2 (en) | Example translation system, example translation method, and example translation program | |
| JP5811795B2 (en) | Document analysis system, document analysis method and program | |
| JP2021036408A (en) | Search support system, learning system, search support method, and program | |
| JP6707410B2 (en) | Document search device, document search method, and computer program | |
| JP2014235584A (en) | Document analysis system, document analysis method, and program | |
| JP6476638B2 (en) | Specific term candidate extraction device, specific term candidate extraction method, and specific term candidate extraction program | |
| JP2013137702A (en) | Document analysis system, document analysis method and program | |
| JP5137134B2 (en) | Kansei information extraction / retrieval device, method and program thereof | |
| JP2020170426A (en) | Table structure estimation system and table structure estimation method | |
| JPWO2016013157A1 (en) | Text processing system, text processing method, and text processing program | |
| JP2011233163A (en) | Sentence associating system and sentence associating program | |
| JP2013182580A (en) | Identity vector construction device, identity vector construction method, predicate similarity calculation device, predicate similarity calculation method and predicate similarity calculation program |
Legal Events
| Date | Code | Title | Description |
|---|---|---|---|
| A621 | Written request for application examination |
Free format text: JAPANESE INTERMEDIATE CODE: A621 Effective date: 20141017 |
|
| A977 | Report on retrieval |
Free format text: JAPANESE INTERMEDIATE CODE: A971007 Effective date: 20150605 |
|
| A131 | Notification of reasons for refusal |
Free format text: JAPANESE INTERMEDIATE CODE: A131 Effective date: 20150616 |
|
| A521 | Request for written amendment filed |
Free format text: JAPANESE INTERMEDIATE CODE: A523 Effective date: 20150806 |
|
| TRDD | Decision of grant or rejection written | ||
| A01 | Written decision to grant a patent or to grant a registration (utility model) |
Free format text: JAPANESE INTERMEDIATE CODE: A01 Effective date: 20150825 |
|
| A61 | First payment of annual fees (during grant procedure) |
Free format text: JAPANESE INTERMEDIATE CODE: A61 Effective date: 20150907 |
|
| R150 | Certificate of patent or registration of utility model |
Ref document number: 5811795 Country of ref document: JP Free format text: JAPANESE INTERMEDIATE CODE: R150 |
|
| LAPS | Cancellation because of no payment of annual fees |