CN116206611A - Method and device for automatically constructing case-related voiceprint library - Google Patents
Method and device for automatically constructing case-related voiceprint library Download PDFInfo
- Publication number
- CN116206611A CN116206611A CN202310100660.6A CN202310100660A CN116206611A CN 116206611 A CN116206611 A CN 116206611A CN 202310100660 A CN202310100660 A CN 202310100660A CN 116206611 A CN116206611 A CN 116206611A
- Authority
- CN
- China
- Prior art keywords
- voice
- voiceprint
- clustering
- library
- file
- Prior art date
- Legal status (The legal status is an assumption and is not a legal conclusion. Google has not performed a legal analysis and makes no representation as to the accuracy of the status listed.)
- Pending
Links
Images




Classifications
-
- G—PHYSICS
- G10—MUSICAL INSTRUMENTS; ACOUSTICS
- G10L—SPEECH ANALYSIS TECHNIQUES OR SPEECH SYNTHESIS; SPEECH RECOGNITION; SPEECH OR VOICE PROCESSING TECHNIQUES; SPEECH OR AUDIO CODING OR DECODING
- G10L17/00—Speaker identification or verification techniques
- G10L17/02—Preprocessing operations, e.g. segment selection; Pattern representation or modelling, e.g. based on linear discriminant analysis [LDA] or principal components; Feature selection or extraction
-
- G—PHYSICS
- G10—MUSICAL INSTRUMENTS; ACOUSTICS
- G10L—SPEECH ANALYSIS TECHNIQUES OR SPEECH SYNTHESIS; SPEECH RECOGNITION; SPEECH OR VOICE PROCESSING TECHNIQUES; SPEECH OR AUDIO CODING OR DECODING
- G10L17/00—Speaker identification or verification techniques
- G10L17/06—Decision making techniques; Pattern matching strategies
- G10L17/14—Use of phonemic categorisation or speech recognition prior to speaker recognition or verification
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04L—TRANSMISSION OF DIGITAL INFORMATION, e.g. TELEGRAPHIC COMMUNICATION
- H04L51/00—User-to-user messaging in packet-switching networks, transmitted according to store-and-forward or real-time protocols, e.g. e-mail
- H04L51/04—Real-time or near real-time messaging, e.g. instant messaging [IM]
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04M—TELEPHONIC COMMUNICATION
- H04M3/00—Automatic or semi-automatic exchanges
- H04M3/22—Arrangements for supervision, monitoring or testing
- H04M3/2281—Call monitoring, e.g. for law enforcement purposes; Call tracing; Detection or prevention of malicious calls
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04M—TELEPHONIC COMMUNICATION
- H04M3/00—Automatic or semi-automatic exchanges
- H04M3/42—Systems providing special services or facilities to subscribers
- H04M3/487—Arrangements for providing information services, e.g. recorded voice services or time announcements
- H04M3/493—Interactive information services, e.g. directory enquiries ; Arrangements therefor, e.g. interactive voice response [IVR] systems or voice portals
- H04M3/4936—Speech interaction details
-
- Y—GENERAL TAGGING OF NEW TECHNOLOGICAL DEVELOPMENTS; GENERAL TAGGING OF CROSS-SECTIONAL TECHNOLOGIES SPANNING OVER SEVERAL SECTIONS OF THE IPC; TECHNICAL SUBJECTS COVERED BY FORMER USPC CROSS-REFERENCE ART COLLECTIONS [XRACs] AND DIGESTS
- Y02—TECHNOLOGIES OR APPLICATIONS FOR MITIGATION OR ADAPTATION AGAINST CLIMATE CHANGE
- Y02D—CLIMATE CHANGE MITIGATION TECHNOLOGIES IN INFORMATION AND COMMUNICATION TECHNOLOGIES [ICT], I.E. INFORMATION AND COMMUNICATION TECHNOLOGIES AIMING AT THE REDUCTION OF THEIR OWN ENERGY USE
- Y02D30/00—Reducing energy consumption in communication networks
- Y02D30/70—Reducing energy consumption in communication networks in wireless communication networks
Landscapes
- Engineering & Computer Science (AREA)
- Human Computer Interaction (AREA)
- Signal Processing (AREA)
- Acoustics & Sound (AREA)
- Audiology, Speech & Language Pathology (AREA)
- Physics & Mathematics (AREA)
- Health & Medical Sciences (AREA)
- Multimedia (AREA)
- Computer Vision & Pattern Recognition (AREA)
- Business, Economics & Management (AREA)
- Game Theory and Decision Science (AREA)
- Computer Networks & Wireless Communication (AREA)
- Computer Security & Cryptography (AREA)
- Technology Law (AREA)
- Telephonic Communication Services (AREA)
Abstract
Description
技术领域technical field
本发明属于声纹技术的技术领域,具体涉及一种涉案声纹库自动构建的方法和装置。The invention belongs to the technical field of voiceprint technology, and in particular relates to a method and device for automatically constructing a voiceprint library involved in the case.
背景技术Background technique
随着近年来互联网相关案件呈现不断上升的趋势,声纹特征在公共安全领域的价值日益突出。声纹特征是人体重要的生物特征之一,声纹特征可以唯一确定用户的身份。声纹库建成以后可以直接服务于多个警种,将能有效提高相关机关侦查破案的效率和能力。当前全国相关机关声纹数据库百万级比对前十位命中率已达90%,首位命中率达到70%,且比对精准度还在逐年提升。因此电子数据勘查取证技术从手机、电脑等载体中提取声纹数据,利用声纹鉴定技术对相关案件中的涉案语音进行个体、团伙识别,能够准确认定特定人员身份,为侦查破案、案件诉讼提供更加有力的证据支撑。With the increasing trend of Internet-related cases in recent years, the value of voiceprint features in the field of public security has become increasingly prominent. The voiceprint feature is one of the important biological features of the human body, and the voiceprint feature can uniquely determine the identity of the user. After the voiceprint library is completed, it can directly serve multiple types of police, which will effectively improve the efficiency and ability of relevant agencies to investigate and solve crimes. At present, the hit rate of the top ten in the million-level comparison of the voiceprint database of relevant agencies across the country has reached 90%, and the hit rate of the first place has reached 70%, and the comparison accuracy is still improving year by year. Therefore, electronic data exploration and evidence collection technology extracts voiceprint data from mobile phones, computers and other carriers, and uses voiceprint identification technology to identify individuals and groups involved in the voices involved in related cases, which can accurately identify the identity of specific personnel, and provide services for investigation and case litigation. Stronger evidence support.
然而国内电子数据取证产品,国外Encase forensic、Recon imager等市场占有率较高的产品,均尚未具备从电子设备存储的数据中抽取语音文件自动构建声纹库的功能。However, domestic electronic data forensics products, foreign Encase forensic, Recon imager and other products with high market share have not yet had the function of extracting voice files from the data stored in electronic devices to automatically build a voiceprint library.
而且,目前声纹库在采集声纹的时候,更多的是依赖人工采集,采集后要手动填写被采集人的身份证号、姓名、性别等信息,这使得批量采集声纹数据比较繁琐而耗时;在实际的声纹采集过程中,声纹数据库质量往往参差不齐,声纹信息提取过程没有详尽的记录和归档,提取的声纹数据混乱,无法构建对应关系,从而导致识别准确率的降低,无法为声纹库的进一步应用提供数据基础。Moreover, the current voiceprint library relies more on manual collection when collecting voiceprints. After collection, it is necessary to manually fill in the ID number, name, gender and other information of the collected person, which makes batch collection of voiceprint data cumbersome and difficult. Time-consuming; in the actual voiceprint collection process, the quality of the voiceprint database is often uneven, the voiceprint information extraction process is not thoroughly recorded and archived, the extracted voiceprint data is chaotic, and the corresponding relationship cannot be established, resulting in a high recognition accuracy rate. The reduction cannot provide a data basis for the further application of the voiceprint library.
有鉴于此,提出一种涉案声纹库自动构建的方法和装置是非常具有意义的。In view of this, it is very meaningful to propose a method and device for automatically constructing the voiceprint database involved in the case.
发明内容Contents of the invention
为了解决现有批量采集声纹繁琐耗时且声纹库的质量不高等问题,本发明提供一种涉案声纹库自动构建的方法和装置,以解决上述存在的技术缺陷问题。In order to solve the existing problems of cumbersome and time-consuming batch collection of voiceprints and the low quality of the voiceprint library, the present invention provides a method and device for automatically constructing the voiceprint library involved in the case to solve the above-mentioned technical defects.
第一方面,本发明提出了一种涉案声纹库自动构建的方法,该方法包括如下步骤:In the first aspect, the present invention proposes a method for automatically constructing the voiceprint library involved in the case, which includes the following steps:
语音提取,获取有关人员的电子设备中保存的声音文件并进行提取,扫描出设备中符合要求的音频格式文件并保存作为相关人员声纹库的语音数据源;Voice extraction, obtain and extract the sound files stored in the electronic equipment of the relevant personnel, scan out the audio format files that meet the requirements in the equipment and save them as the voice data source of the voiceprint database of the relevant personnel;
语音切割,借助语音识别引擎ASR将提取到的所述语音文件切分为语音片段;Voice cutting, by means of the voice recognition engine ASR, the voice file extracted is divided into voice segments;
计算语音特征,利用梅尔频率倒谱系数MFCC作为声学特征,计算得到语音帧特征矢量并对声纹矢量量化;Calculate the speech features, use the Mel frequency cepstrum coefficient MFCC as the acoustic feature, calculate the speech frame feature vector and quantize the voiceprint vector;
语音聚类,根据计算得到的声纹矢量量化结果,进行PCA转换进行主成分分析,选择K均值算法对语音进行智能聚类,提取所有相关人员的语音特征,找到质量最好的语音片段组装成指定长度的语音文件作为聚类结果;Speech clustering, according to the calculated results of voiceprint vector quantization, PCA conversion is performed for principal component analysis, K-means algorithm is selected for intelligent clustering of voices, voice features of all relevant personnel are extracted, and voice fragments with the best quality are found and assembled into Voice files of specified length are used as clustering results;
构建声纹库,根据语音聚类的结果,提取聚类后语音文件的声纹特征,建立规范化的标准应用库。Build a voiceprint library, extract the voiceprint features of the clustered voice files according to the results of voice clustering, and establish a standardized standard application library.
优选的,在语音提取步骤中,若存在即时聊天软件,聊天语音加密保存在聊天文件中,需先解密聊天文件后对语音数据进行单独提取。Preferably, in the voice extraction step, if there is an instant chat software, the chat voice is encrypted and saved in the chat file, and the voice data needs to be extracted separately after the chat file is decrypted first.
进一步优选的,解密聊天文件后对语音数据进行单独提取具体包括:Further preferably, extracting the voice data separately after decrypting the chat file specifically includes:
通过动态污点分析方法对软件进程行为进行跟踪,并构建获取密钥行为的污点传播路径,系统自动记录每个环节的网络数据包和协议状态,通过对数据包和协议的分析完成协议模拟环境的搭建;The behavior of the software process is tracked through the dynamic taint analysis method, and the taint propagation path for obtaining the key behavior is constructed. The system automatically records the network data packets and protocol status of each link, and completes the protocol simulation environment by analyzing the data packets and protocols. build;
分析软件进程内存结构,从进程空间中获取当前登录令牌和其他环境变量;Analyze the memory structure of the software process, and obtain the current login token and other environment variables from the process space;
把令牌和变量设置到协议模拟环境中,开始模拟从服务端获取密钥的流程,密钥提取成功后对本地聊天记录文件进行解密和分析,查找到语音数据存储路径;Set the token and variables in the protocol simulation environment, and start to simulate the process of obtaining the key from the server. After the key is successfully extracted, the local chat record file is decrypted and analyzed, and the voice data storage path is found;
扫描设备中的所有文件,找出语音文件提取并记录。Scan all files in the device, find out voice files to extract and record.
进一步优选的,计算语音特征步骤具体包括:Further preferably, the step of calculating speech features specifically includes:
对语音片段进行预处理减少噪声;Preprocess the speech clips to reduce noise;
加Hamming窗减少Jibbs效应;Add Hamming window to reduce Jibbs effect;
进行离散傅里叶变换后,利用序列三角滤波器滤波处理;After the discrete Fourier transform is performed, the sequence triangular filter is used for filtering;
进行离散余弦变换DCT,得到语音帧特征矢量,并进行矢量量化。Carry out discrete cosine transform DCT to obtain the feature vector of the speech frame, and carry out vector quantization.
进一步优选的,在语音聚类步骤中,还可以根据需要对聚类后的语音进行多次智能分割后再次重新聚类,直到达到预期后结束。Further preferably, in the speech clustering step, the clustered speech may be intelligently segmented multiple times as required, and then re-clustered again until the desired result is achieved.
进一步优选的,声纹库的主要信息包括:声纹唯一ID标识值、语音聚类文件的存储路径、文件格式、语音时长、语音采集终端信息、语音来源信息、说话人信息;Further preferably, the main information of the voiceprint library includes: voiceprint unique ID identification value, storage path of voice clustering files, file format, voice duration, voice collection terminal information, voice source information, speaker information;
其中,语音采集终端信息你看手机或电脑、型号、系统信息;语音来源信息包括电话语音或即时通讯语音、具体应用、电话号码或者IP、语音产生时间;说话人信息包括说话人UUID、身份证号、电话号码。Among them, voice collection terminal information you look at mobile phone or computer, model, system information; voice source information includes telephone voice or instant messaging voice, specific application, phone number or IP, voice generation time; speaker information includes speaker UUID, ID card number, phone number.
第二方面,本发明实施例还提供一种涉案声纹库自动构建的装置,该装置具体包括:In the second aspect, the embodiment of the present invention also provides a device for automatically constructing the voiceprint library involved in the case, which specifically includes:
语音提取模块,用于获取有关人员的电子设备中保存的声音文件并进行提取,扫描出设备中符合要求的音频格式文件并保存作为相关人员声纹库的语音数据源;The voice extraction module is used to obtain and extract the sound files stored in the electronic equipment of the relevant personnel, scan out the audio format files that meet the requirements in the equipment, and save them as the voice data source of the voiceprint database of the relevant personnel;
语音切割模块,用于借助语音识别引擎ASR将提取到的所述语音文件切分为语音片段;Voice cutting module, for cutting the extracted described voice file into voice segments by means of voice recognition engine ASR;
计算语音特征模块,用于利用梅尔频率倒谱系数MFCC作为声学特征,计算得到语音帧特征矢量并对声纹矢量量化;Calculating the voice feature module, for using the Mel frequency cepstral coefficient MFCC as the acoustic feature, calculating the voice frame feature vector and quantizing the voiceprint vector;
语音聚类模块,用于根据计算得到的声纹矢量量化结果,进行PCA转换进行主成分分析,选择K均值算法对语音进行智能聚类,提取所有相关人员的语音特征,找到质量最好的语音片段组装成指定长度的语音文件作为聚类结果;The voice clustering module is used to perform PCA conversion for principal component analysis based on the calculated voiceprint vector quantization results, select the K-means algorithm to intelligently cluster the voices, extract the voice features of all relevant personnel, and find the voice with the best quality The fragments are assembled into a voice file of a specified length as the clustering result;
构建声纹库模块,用于根据语音聚类的结果,提取聚类后语音文件的声纹特征,建立规范化的标准应用库。Construct the voiceprint library module, which is used to extract the voiceprint features of the clustered voice files according to the results of voice clustering, and establish a standardized standard application library.
第三方面,本发明实施例提供了一种电子设备,包括:一个或多个处理器;存储装置,用于存储一个或多个程序,当一个或多个程序被一个或多个处理器执行,使得一个或多个处理器实现如第一方面中任一实现方式描述的方法。In a third aspect, an embodiment of the present invention provides an electronic device, including: one or more processors; a storage device for storing one or more programs, when one or more programs are executed by one or more processors , so that one or more processors implement the method described in any implementation manner of the first aspect.
第四方面,本发明实施例提供了一种计算机可读存储介质,其上存储有计算机程序,该计算机程序被处理器执行时实现如第一方面中任一实现方式描述的方法。In a fourth aspect, an embodiment of the present invention provides a computer-readable storage medium, on which a computer program is stored. When the computer program is executed by a processor, the method described in any implementation manner in the first aspect is implemented.
与现有技术相比,本发明的有益成果在于:Compared with the prior art, the beneficial results of the present invention are:
(1)通过将涉案人员的声纹信息加入人员信息数据库,后续案件侦破过程中可以通过声纹自动识别技术快速锁定犯罪嫌疑人,将侦查范围缩小至极小,极大地提升案件的侦破效率,该方法已经在美亚柏科神剑侦勘一体化项目中应用。(1) By adding the voiceprint information of the persons involved in the case into the personnel information database, the criminal suspect can be quickly identified through the voiceprint automatic recognition technology in the follow-up case detection process, the scope of investigation is reduced to a very small size, and the detection efficiency of the case is greatly improved. The method has been applied in the Meiya Pico Excalibur reconnaissance and reconnaissance integration project.
(2)本发明的方法采用一键式操作,自动快速提取设备中的语音文件(比如确认诈骗电话、疑似诈骗电话人语音录音等),同时支持对目前主流的即时通讯软件(包括QQ、微信、钉钉、Line、FeiQ、WhatApps等)中的聊天语音进行解密提取源语音数据,智能分割和聚类、提取声纹特征后构建声纹库,实用性较强且操作简单,满足声纹识别工作以及建库工作的需要。本方法不足之处是,随着用户对数据安全越来越重视以及即时通讯等软件种类越来越丰富,提取被加密地聊天语音文件也需要付出更多努力。(2) The method of the present invention adopts one-button operation to automatically and quickly extract the voice files in the device (such as confirming fraudulent calls, voice recordings of people suspected of fraudulent calls, etc.), and supports instant messaging software (comprising QQ, WeChat, etc.) , DingTalk, Line, FeiQ, WhatApps, etc.) to decrypt chat voices and extract source voice data, intelligently segment and cluster, and extract voiceprint features to build a voiceprint library, which is practical and easy to operate, and meets voiceprint recognition Work and the needs of building a database. The disadvantage of this method is that as users pay more and more attention to data security and the types of software such as instant messaging become more and more abundant, it will also require more efforts to extract encrypted chat voice files.
附图说明Description of drawings
包括附图以提供对实施例的进一步理解并且附图被并入本说明书中并且构成本说明书的一部分。附图图示了实施例并且与描述一起用于解释本发明的原理。将容易认识到其它实施例和实施例的很多预期优点,因为通过引用以下详细描述,它们变得被更好地理解。附图的元件不一定是相互按照比例的。同样的附图标记指代对应的类似部件。The accompanying drawings are included to provide a further understanding of the embodiments and are incorporated in and constitute a part of this specification. The drawings illustrate the embodiments and together with the description serve to explain principles of the invention. Other embodiments and many intended advantages of the embodiments will readily be appreciated as they become better understood by reference to the following detailed description. The elements of the drawings are not necessarily to scale relative to each other. Like reference numerals designate corresponding similar parts.
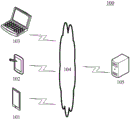
图1是本发明的一个实施例可以应用于其中的示例性装置架构图;Fig. 1 is an exemplary device architecture diagram in which an embodiment of the present invention can be applied;
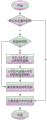
图2为本发明的实施例的涉案声纹库自动构建的方法的流程示意图;Fig. 2 is a schematic flow chart of the method for automatically constructing the voiceprint library involved in the case according to an embodiment of the present invention;
图3为本发明的实施例的涉案声纹库自动构建的方法中声纹库构建的流程示意图;Fig. 3 is a schematic flowchart of the construction of the voiceprint database in the method for automatically constructing the voiceprint database involved in the case according to the embodiment of the present invention;
图4为本发明的实施例的涉案声纹库自动构建的方法中语音提取的流程示意图;Fig. 4 is a schematic flowchart of speech extraction in the method for automatically constructing the voiceprint library involved in the case according to an embodiment of the present invention;
图5为本发明的实施例的涉案声纹库自动构建的方法中MFCC计算流程的示意图;5 is a schematic diagram of the MFCC calculation process in the method for automatically constructing the voiceprint library involved in the case according to an embodiment of the present invention;
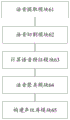
图6为本发明的实施例的涉案声纹库自动构建的装置的流程示意图;Fig. 6 is a schematic flow diagram of the device for automatically constructing the voiceprint library involved in the case according to an embodiment of the present invention;
图7是适于用来实现本发明实施例的电子设备的计算机装置的结构示意图。FIG. 7 is a schematic structural diagram of a computer device suitable for realizing the electronic equipment of the embodiment of the present invention.
具体实施方式Detailed ways
在以下详细描述中,参考附图,该附图形成详细描述的一部分,并且通过其中可实践本发明的说明性具体实施例来示出。对此,参考描述的图的取向来使用方向术语,例如“顶”、“底”、“左”、“右”、“上”、“下”等。因为实施例的部件可被定位于若干不同取向中,为了图示的目的使用方向术语并且方向术语绝非限制。应当理解的是,可以利用其他实施例或可以做出逻辑改变,而不背离本发明的范围。因此以下详细描述不应当在限制的意义上被采用,并且本发明的范围由所附权利要求来限定。In the following detailed description, reference is made to the accompanying drawings, which form a part hereof, and which show by way of illustration specific embodiments in which the invention may be practiced. In this regard, directional terms such as "top", "bottom", "left", "right", "upper", "lower", etc. are used with reference to the orientation of the figures being described. Because components of an embodiment may be positioned in several different orientations, directional terminology is used for purposes of illustration and is by no means limiting. It is to be understood that other embodiments may be utilized or logic changes may be made without departing from the scope of the present invention. The following detailed description should therefore not be taken in a limiting sense, and the scope of the invention is defined by the appended claims.
应该理解,图1中的终端设备、网络和服务器的数目仅仅是示意性的。根据实现需要,可以具有任意数目的终端设备、网络和服务器。It should be understood that the numbers of terminal devices, networks and servers in Fig. 1 are only illustrative. According to the implementation needs, there can be any number of terminal devices, networks and servers.
图1示出了可以应用本发明实施例的用于处理信息的方法或用于处理信息的装置的示例性系统架构100。Fig. 1 shows an
如图1所示,系统架构100可以包括终端设备101、102、103,网络104和服务器105。网络104用以在终端设备101、102、103和服务器105之间提供通信链路的介质。网络104可以包括各种连接类型,例如有线、无线通信链路或者光纤电缆等等。As shown in FIG. 1 , a
用户可以使用终端设备101、102、103通过网络104与服务器105交互,以接收或发送消息等。终端设备101、102、103上可以安装有各种通讯客户端应用,例如网页浏览器应用、购物类应用、搜索类应用、即时通信工具、邮箱客户端、社交平台软件等。Users can use
终端设备101、102、103可以是具有通信功能的各种电子设备,包括但不限于智能手机、平板电脑、膝上型便携计算机和台式计算机等等。The
服务器105可以是提供各种服务的服务器,例如对终端设备101、102、103发送的校验请求信息进行处理的后台信息处理服务器。后台信息处理服务器可以对接收到的校验请求信息进行分析等处理,并得到处理结果(例如用于表征校验请求为合法请求的校验成功信息)。The
需要说明的是,本发明实施例所提供的用于处理信息的方法一般由服务器105执行,相应地,用于处理信息的装置一般设置于服务器105中。另外,本发明实施例所提供的用于发送信息的方法一般由终端设备101、102、103执行,相应地,用于发送信息的装置一般设置于终端设备101、102、103中。It should be noted that the method for processing information provided by the embodiment of the present invention is generally executed by the
需要说明的是,服务器可以是硬件,也可以是软件。当服务器为硬件时,可以实现成多个服务器组成的分布式服务器集群,也可以实现成单个服务器。当服务器为软件时,可以实现成多个软件或软件模块(例如用来提供分布式服务),也可以实现成单个软件或多个软件模块,在此不做具体限定。It should be noted that the server may be hardware or software. When the server is hardware, it can be implemented as a distributed server cluster composed of multiple servers, or as a single server. When the server is software, it can be implemented as multiple software or software modules (for example, to provide distributed services), or can be implemented as a single software or multiple software modules, which are not specifically limited here.
当前构建声纹库的解决方案存在以下几点不足:The current solution for building a voiceprint library has the following deficiencies:
(1)批量采集声纹繁琐耗时:公安机关对采集样本有高质量的要求,录入的声纹必须具备有效性和针对性,方便后续快速声纹识别。目前声纹库在采集声纹的时候,更多的是依赖人工采集,采集后要手动填写被采集人的身份证号、姓名、性别等信息,这使得批量采集声纹数据比较繁琐而耗时。(1) Batch collection of voiceprints is cumbersome and time-consuming: Public security organs have high-quality requirements for collected samples, and the input voiceprints must be effective and targeted to facilitate subsequent rapid voiceprint recognition. At present, when the voiceprint library collects voiceprints, it relies more on manual collection. After collection, it is necessary to manually fill in the ID number, name, gender and other information of the collected person, which makes batch collection of voiceprint data cumbersome and time-consuming. .
(2)声纹库的质量不高:在实际的声纹采集过程中,声纹数据库质量往往参差不齐,声纹信息提取过程没有详尽的记录和归档,提取的声纹数据混乱,无法构建对应关系,从而导致识别准确率的降低,无法为声纹库的进一步应用提供数据基础。(2) The quality of the voiceprint database is not high: in the actual voiceprint collection process, the quality of the voiceprint database is often uneven, and the voiceprint information extraction process is not recorded and archived in detail, and the extracted voiceprint data is chaotic and cannot be constructed Correspondence, resulting in a reduction in recognition accuracy, unable to provide a data basis for the further application of the voiceprint library.
为有效解决以上问题,我们提出一种涉案声纹库自动构建的方法和装置。具体改进点如下:In order to effectively solve the above problems, we propose a method and device for automatically constructing the voiceprint database involved in the case. The specific improvements are as follows:
(1)一键式提取涉案电子设备中存储的通话录音文件、通讯语音文件等,自动整合所有语音数据作为声纹库构建的源。另外还能自动解密即时通讯软件中被加密存储的本地聊天记录文件,提取聊天中的语音数据,更加有针对性。(1) One-click extraction of call recording files, communication voice files, etc. stored in the electronic equipment involved in the case, and automatically integrate all voice data as the source of voiceprint database construction. In addition, it can automatically decrypt the encrypted and stored local chat record files in the instant messaging software, and extract the voice data in the chat, which is more targeted.
(2)自动计算声纹特征值,建立符合规范的标准声纹库,方便后续与后端平台进行数据对接,实现犯罪嫌疑人信息共享和事件其它参与者的身份溯源。例如,系统可通过声纹数据库引擎进行检索、查询、回传该诈骗人员参与的所有通话记录,反向溯源所有与该诈骗通话路径相关的通话行为,帮助公安机关发现真正的诈骗主谋。(2) Automatically calculate the characteristic value of the voiceprint, establish a standard voiceprint library that meets the specifications, facilitate subsequent data connection with the back-end platform, and realize information sharing of criminal suspects and identity tracing of other participants in the incident. For example, the system can search, inquire, and return all call records that the fraudster participated in through the voiceprint database engine, reversely trace all the call behaviors related to the fraudulent call path, and help the public security organs find the real fraud mastermind.
本方案主要提供了语音一键提取、语音智能聚类、自动构建声纹库等功能,用于实现一键提取涉案人员的语音数据并自动构建声纹库。该方法主要实现针对涉案电子物证原始数据进行自动化构建声纹库的过程。This solution mainly provides functions such as one-key extraction of voice, intelligent voice clustering, and automatic construction of voiceprint database, etc., which are used to realize one-key extraction of voice data of persons involved in the case and automatically build voiceprint database. This method mainly realizes the process of automatically constructing the voiceprint library for the original data of the electronic evidence involved in the case.
图2示出了本发明的实施例公开了一种涉案声纹库自动构建的方法,如图2和图3所示,该方法包括如下步骤:Fig. 2 shows that the embodiment of the present invention discloses a method for automatically constructing the voiceprint library involved in the case, as shown in Fig. 2 and Fig. 3, the method includes the following steps:
S1、语音提取,获取有关人员的电子设备中保存的声音文件并进行提取,扫描出设备中符合要求的音频格式文件并保存作为相关人员声纹库的语音数据源;S1, voice extraction, obtain and extract the sound files stored in the electronic equipment of the relevant personnel, scan out the audio format files that meet the requirements in the equipment and save them as the voice data source of the voiceprint database of the relevant personnel;
在具体实施例中,语音一键提取:依托电子取证的数据提取能力,自动全面地将涉案人员电子设备(包括Android、IOS操作系统智能手机、平板设备、笔记本电脑、台式电脑)中保存的声音文件进行有效地提取,扫描出设备中符合要求的音频格式文件(如wav、mp3、amr、silk、m4a、acc等)并保存作为涉案人声纹库的语音数据源。In a specific embodiment, one-key voice extraction: relying on the data extraction capability of electronic forensics, the voices stored in the electronic devices (including Android, IOS operating system smartphones, tablet devices, notebook computers, and desktop computers) of the persons involved in the case are automatically and comprehensively extracted. The files are effectively extracted, and the required audio format files (such as wav, mp3, amr, silk, m4a, acc, etc.) in the device are scanned and saved as the voice data source of the voiceprint database of the people involved in the case.
进一步的,如果存在即时聊天软件,聊天语音可能会加密保存在聊天文件中,针对这种情况,还需要先解密聊天文件后对语音数据进行单独提取,具体流程如图4所示。Furthermore, if there is an instant chat software, the chat voice may be encrypted and stored in the chat file. In this case, it is necessary to decrypt the chat file first and then extract the voice data separately. The specific process is shown in Figure 4.
具体的,即时通讯软件语音数据作为附件形式存在,随着应用厂商对数据保护的力度不断增强,存储路径越发不易查找,且很多本地数据都被加密处理,所以如果存在通讯数据会加密的即时通讯软件,还需要获取登录密钥再解密分析本地聊天记录,提取聊天中的语音文件。Specifically, the voice data of instant messaging software exists as an attachment. As application manufacturers continue to strengthen data protection, storage paths are becoming more difficult to find, and many local data are encrypted. The software also needs to obtain the login key to decrypt and analyze the local chat records, and extract the voice files in the chat.
①通过动态污点分析方法对软件进程行为进行跟踪,并构建获取密钥行为的污点传播路径,系统自动记录每个环节的网络数据包和协议状态,通过对数据包和协议的分析完成协议模拟环境的搭建;①Track the behavior of the software process through the dynamic taint analysis method, and construct the taint propagation path of the behavior of obtaining the key. The system automatically records the network data packets and protocol status of each link, and completes the protocol simulation environment through the analysis of the data packets and protocols construction;
②分析软件进程内存结构,从进程空间中获取当前登录令牌和其他环境变量;② Analyze the memory structure of the software process, and obtain the current login token and other environment variables from the process space;
③把令牌和变量设置到协议模拟环境中,开始模拟从服务端获取密钥的流程,密钥提取成功后对本地聊天记录文件进行解密和分析,查找到语音数据存储路径;③Set the token and variables into the protocol simulation environment, and start to simulate the process of obtaining the key from the server. After the key is successfully extracted, the local chat record file is decrypted and analyzed, and the voice data storage path is found;
④扫描设备中所有文件,找出语音文件提取并记录。④Scan all the files in the device, find out the voice files, extract and record them.
S2、语音切割,借助语音识别引擎ASR将提取到的所述语音文件切分为语音片段;S2, voice cutting, cutting the extracted voice file into voice segments by means of the voice recognition engine ASR;
具体的,语音智能切割:借助语音识别引擎(ASR)将提取到的语音文件切分为语音片段。ASR引擎对语音文件处理后,会得到语音识别的文字和文字对应的起止时间,根据这个时间信息,可以很容易将一段语音文件切割开来。这里需要强调的是,我们并不利用语音识别的文字结果,只需要知道每一个识别出来的文字的边界信息,即使识别有错误,对声纹库构建并不会造成任何影响,因为我们始终用的都是声音的声学信息,并不关心这段声音所对应的文字信息。Specifically, voice intelligent cutting: the extracted voice file is divided into voice segments by means of a voice recognition engine (ASR). After the ASR engine processes the audio file, it will get the speech recognition text and the corresponding start and end time of the text. According to this time information, a section of audio file can be easily cut. What needs to be emphasized here is that we do not use the text results of speech recognition, but only need to know the boundary information of each recognized text. Even if there is an error in the recognition, it will not have any impact on the construction of the voiceprint library, because we always use It is all about the acoustic information of the sound, and does not care about the text information corresponding to this sound.
S3、计算语音特征,利用梅尔频率倒谱系数MFCC作为声学特征,计算得到语音帧特征矢量并对声纹矢量量化;S3. Calculating speech features, using the Mel frequency cepstral coefficient MFCC as the acoustic feature, calculating the speech frame feature vector and quantizing the voiceprint vector;
具体的,如图5所示,我们选择梅尔频率倒谱系数(MFCC)作为声学特征。MFCC是在Mel标度频率域提取出来的倒谱参数,可以用来表征说话人信息的声学特征,可有效辨识某段音频的发声者。Specifically, as shown in Fig. 5, we choose the Mel-frequency cepstral coefficient (MFCC) as the acoustic feature. MFCC is a cepstrum parameter extracted in the Mel scale frequency domain, which can be used to characterize the acoustic characteristics of speaker information, and can effectively identify the speaker of a certain audio.
S4、语音聚类,根据计算得到的声纹矢量量化结果,进行PCA转换进行主成分分析,选择K均值算法对语音进行智能聚类,提取所有相关人员的语音特征,找到质量最好的语音片段组装成指定长度的语音文件作为聚类结果;S4. Speech clustering. According to the calculated voiceprint vector quantization results, perform PCA conversion for principal component analysis, select the K-means algorithm to intelligently cluster the voices, extract the voice features of all relevant personnel, and find the best quality voice clips Assemble into a voice file of specified length as the clustering result;
在具体实施例中,根据上述声纹矢量量化的结果,进行PCA转换后进行主成分分析,然后选择K均值算法对语音进行智能聚类,尽可能提取所有涉案人的语音特征,找到质量最好的语音片段组装成指定长度的语音文件作为聚类结果。为了提升语音特征提取和聚类的准确性,还可以根据需要对聚类后的语音多次智能分割后再次重新聚类,达到预期后结束。In a specific embodiment, according to the result of the vector quantization of the above-mentioned voiceprints, PCA conversion is performed and principal component analysis is performed, and then the K-means algorithm is selected to intelligently cluster the voices, so as to extract the voice features of all persons involved in the case as much as possible, and find out the voice features with the best quality. The speech fragments of the group are assembled into a speech file of a specified length as the clustering result. In order to improve the accuracy of speech feature extraction and clustering, the clustered speech can also be intelligently segmented multiple times according to needs, and then re-clustered again, and it ends when it reaches expectations.
S5、构建声纹库,根据语音聚类的结果,提取聚类后语音文件的声纹特征,建立规范化的标准应用库。S5. Construct a voiceprint library, extract the voiceprint features of the clustered voice files according to the result of voice clustering, and establish a standardized standard application library.
具体的,构建声纹库:根据语音聚类的结果,提取聚类后语音文件的声纹特征,建立规范化的标准应用库,声纹库的主要信息有:声纹唯一ID标识值、语音聚类文件的存储路径、文件格式、语音时长、语音采集终端信息(手机/电脑、型号、系统信息等)、语音来源信息(电话语音/即时通讯语音等、具体应用、电话号码或者IP、语音产生时间)、说话人信息(说话人UUID、身份证号、电话号码等)。Specifically, build a voiceprint library: According to the results of voice clustering, extract the voiceprint features of the clustered voice files, and establish a standardized standard application library. The main information of the voiceprint library includes: voiceprint unique ID value, voice clustering Class file storage path, file format, voice duration, voice collection terminal information (mobile phone/computer, model, system information, etc.), voice source information (telephone voice/instant messaging voice, etc., specific application, phone number or IP, voice generation Time), speaker information (speaker UUID, ID number, phone number, etc.).
第二方面,本发明实施例还公开了一种涉案声纹库自动构建的装置,如图6所示,该装置具体包括:语音提取模块61,语音切割模块62,计算语音特征模块63,语音聚类模块64以及构建声纹库模块65。In the second aspect, the embodiment of the present invention also discloses a device for automatically constructing the voiceprint library involved in the case. As shown in Figure 6, the device specifically includes: a voice extraction module 61, a voice cutting module 62, a voice feature calculation module 63, A clustering module 64 and a module 65 for constructing a voiceprint library.
在具体的实施例中,语音提取模块61,用于获取有关人员的电子设备中保存的声音文件并进行提取,扫描出设备中符合要求的音频格式文件并保存作为相关人员声纹库的语音数据源;语音切割模块62,用于借助语音识别引擎ASR将提取到的所述语音文件切分为语音片段;计算语音特征模块63,用于利用梅尔频率倒谱系数MFCC作为声学特征,计算得到语音帧特征矢量并对声纹矢量量化;语音聚类模块64,用于根据计算得到的声纹矢量量化结果,进行PCA转换进行主成分分析,选择K均值算法对语音进行智能聚类,提取所有相关人员的语音特征,找到质量最好的语音片段组装成指定长度的语音文件作为聚类结果;构建声纹库模块65,用于根据语音聚类的结果,提取聚类后语音文件的声纹特征,建立规范化的标准应用库。In a specific embodiment, the voice extraction module 61 is used to obtain and extract the sound files stored in the electronic equipment of the relevant personnel, scan out the audio format files that meet the requirements in the equipment, and save the voice data as the voiceprint library of the relevant personnel Source; voice cutting module 62, for cutting the extracted voice file into voice segments by means of voice recognition engine ASR; calculating voice feature module 63, for utilizing Mel frequency cepstral coefficient MFCC as acoustic features, calculated to obtain Speech frame feature vector and voiceprint vector quantization; Speech clustering module 64, for the voiceprint vector quantization result obtained according to calculation, carry out PCA transformation and carry out principal component analysis, select K-means algorithm to carry out intelligent clustering to speech, extract all According to the voice characteristics of relevant personnel, find the voice segment with the best quality and assemble it into a voice file of specified length as the clustering result; build the voiceprint library module 65, which is used to extract the voiceprint of the clustered voice file according to the voice clustering result Features, establish a standardized standard application library.
本发明的技术方案提供了一种涉案声纹库自动构建的方法和装置,该方法采用一键式操作,自动快速提取设备中的语音文件(比如确认诈骗电话、疑似诈骗电话人语音录音等),同时支持对目前主流的即时通讯软件(包括QQ、微信、钉钉、Line、FeiQ、WhatApps等)中的聊天语音进行解密提取源语音数据,智能分割和聚类、提取声纹特征后构建声纹库,实用性较强且操作简单,满足声纹识别工作以及建库工作的需要。本方法不足之处是,随着用户对数据安全越来越重视以及即时通讯等软件种类越来越丰富,提取被加密地聊天语音文件也需要付出更多努力。The technical solution of the present invention provides a method and device for automatically constructing the voiceprint library involved in the case. The method adopts one-button operation to automatically and quickly extract the voice files in the device (such as confirming fraudulent calls, voice recordings of suspected fraudulent callers, etc.) At the same time, it supports decrypting the chat voice in the current mainstream instant messaging software (including QQ, WeChat, DingTalk, Line, FeiQ, WhatApps, etc.), extracting source voice data, intelligently segmenting and clustering, and extracting voiceprint features to construct voice Texture database, with strong practicability and simple operation, meets the needs of voiceprint recognition and database construction. The disadvantage of this method is that as users pay more and more attention to data security and the types of software such as instant messaging become more and more abundant, it will also require more efforts to extract encrypted chat voice files.
本发明将涉案人员的声纹信息加入人员信息数据库,后续案件侦破过程中可以通过声纹自动识别技术快速锁定犯罪嫌疑人,将侦查范围缩小至极小,极大地提升案件的侦破效率,该方法已经在美亚柏科神剑侦勘一体化项目中应用。The present invention adds the voiceprint information of the persons involved in the case into the personnel information database, and in the subsequent case detection process, the criminal suspect can be quickly locked through the voiceprint automatic recognition technology, the investigation scope is reduced to a very small size, and the detection efficiency of the case is greatly improved. Applied in Meiya Pico Excalibur reconnaissance integration project.
下面参考图7,其示出了适于用来实现本发明实施例的电子设备(例如图1所示的服务器或终端设备)的计算机装置700的结构示意图。图7示出的电子设备仅仅是一个示例,不应对本发明实施例的功能和使用范围带来任何限制。Referring now to FIG. 7 , it shows a schematic structural diagram of a
如图7所示,计算机装置700包括中央处理单元(CPU)701和图形处理器(GPU)702,其可以根据存储在只读存储器(ROM)703中的程序或者从存储部分709加载到随机访问存储器(RAM)706中的程序而执行各种适当的动作和处理。在RAM 704中,还存储有装置700操作所需的各种程序和数据。CPU 701、GPU702、ROM 703以及RAM 704通过总线705彼此相连。输入/输出(I/O)接口706也连接至总线705。As shown in FIG. 7, a
以下部件连接至I/O接口706:包括键盘、鼠标等的输入部分707;包括诸如、液晶显示器(LCD)等以及扬声器等的输出部分708;包括硬盘等的存储部分709;以及包括诸如LAN卡、调制解调器等的网络接口卡的通信部分710。通信部分710经由诸如因特网的网络执行通信处理。驱动器711也可以根据需要连接至I/O接口706。可拆卸介质712,诸如磁盘、光盘、磁光盘、半导体存储器等等,根据需要安装在驱动器711上,以便于从其上读出的计算机程序根据需要被安装入存储部分709。The following components are connected to the I/O interface 706: an
特别地,根据本发明公开的实施例,上文参考流程图描述的过程可以被实现为计算机软件程序。例如,本发明公开的实施例包括一种计算机程序产品,其包括承载在计算机可读介质上的计算机程序,该计算机程序包含用于执行流程图所示的方法的程序代码。在这样的实施例中,该计算机程序可以通过通信部分710从网络上被下载和安装,和/或从可拆卸介质712被安装。在该计算机程序被中央处理单元(CPU)701和图形处理器(GPU)702执行时,执行本发明的方法中限定的上述功能。In particular, according to the disclosed embodiments of the present invention, the processes described above with reference to the flowcharts can be implemented as computer software programs. For example, the disclosed embodiments of the present invention include a computer program product, which includes a computer program carried on a computer-readable medium, where the computer program includes program codes for executing the methods shown in the flowcharts. In such an embodiment, the computer program may be downloaded and installed from a network via
需要说明的是,本发明所述的计算机可读介质可以是计算机可读信号介质或者计算机可读介质或者是上述两者的任意组合。计算机可读介质例如可以是——但不限于——电、磁、光、电磁、红外线、或半导体的装置、装置或器件,或者任意以上的组合。计算机可读介质的更具体的例子可以包括但不限于:具有一个或多个导线的电连接、便携式计算机磁盘、硬盘、随机访问存储器(RAM)、只读存储器(ROM)、可擦式可编程只读存储器(EPROM或闪存)、光纤、便携式紧凑磁盘只读存储器(CD-ROM)、光存储器件、磁存储器件、或者上述的任意合适的组合。在本发明中,计算机可读介质可以是任何包含或存储程序的有形介质,该程序可以被指令执行装置、装置或者器件使用或者与其结合使用。而在本发明中,计算机可读的信号介质可以包括在基带中或者作为载波一部分传播的数据信号,其中承载了计算机可读的程序代码。这种传播的数据信号可以采用多种形式,包括但不限于电磁信号、光信号或上述的任意合适的组合。计算机可读的信号介质还可以是计算机可读介质以外的任何计算机可读介质,该计算机可读介质可以发送、传播或者传输用于由指令执行装置、装置或者器件使用或者与其结合使用的程序。计算机可读介质上包含的程序代码可以用任何适当的介质传输,包括但不限于:无线、电线、光缆、RF等等,或者上述的任意合适的组合。It should be noted that the computer-readable medium in the present invention may be a computer-readable signal medium or a computer-readable medium or any combination of the above two. A computer readable medium can be, for example, but not limited to, an electrical, magnetic, optical, electromagnetic, infrared, or semiconductor device, device, or device, or a combination of any of the above. More specific examples of computer readable media may include, but are not limited to, electrical connections with one or more conductors, portable computer diskettes, hard disks, random access memory (RAM), read only memory (ROM), erasable programmable Read only memory (EPROM or flash memory), optical fiber, portable compact disk read only memory (CD-ROM), optical storage device, magnetic storage device, or any suitable combination of the above. In the present invention, a computer-readable medium may be any tangible medium that contains or stores a program that can be used by or in conjunction with an instruction execution device, device, or device. In the present invention, however, a computer-readable signal medium may include a data signal propagated in baseband or as part of a carrier wave, in which computer-readable program codes are carried. Such propagated data signals may take many forms, including but not limited to electromagnetic signals, optical signals, or any suitable combination of the foregoing. A computer-readable signal medium may also be any computer-readable medium other than a computer-readable medium that can transmit, propagate, or transport a program for use by or in conjunction with an instruction execution apparatus, apparatus, or device. Program code embodied on a computer readable medium may be transmitted using any appropriate medium, including but not limited to wireless, wireline, optical fiber cable, RF, etc., or any suitable combination of the foregoing.
可以以一种或多种程序设计语言或其组合来编写用于执行本发明的操作的计算机程序代码,所述程序设计语言包括面向对象的程序设计语言—诸如Java、Smalltalk、C++,还包括常规的过程式程序设计语言—诸如“C”语言或类似的程序设计语言。程序代码可以完全地在用户计算机上执行、部分地在用户计算机上执行、作为一个独立的软件包执行、部分在用户计算机上部分在远程计算机上执行、或者完全在远程计算机或服务器上执行。在涉及远程计算机的情形中,远程计算机可以通过任意种类的网络——包括局域网(LAN)或广域网(WAN)—连接到用户计算机,或者,可以连接到外部计算机(例如利用因特网服务提供商来通过因特网连接)。Computer program code for carrying out the operations of the present invention can be written in one or more programming languages, or combinations thereof, including object-oriented programming languages—such as Java, Smalltalk, C++, and conventional A procedural programming language—such as "C" or a similar programming language. The program code may execute entirely on the user's computer, partly on the user's computer, as a stand-alone software package, partly on the user's computer and partly on a remote computer or entirely on the remote computer or server. In cases involving a remote computer, the remote computer can be connected to the user computer through any kind of network, including a local area network (LAN) or a wide area network (WAN), or it can be connected to an external computer (such as through an Internet service provider). Internet connection).
附图中的流程图和框图,图示了按照本发明各种实施例的装置、方法和计算机程序产品的可能实现的体系架构、功能和操作。在这点上,流程图或框图中的每个方框可以代表一个模块、程序段、或代码的一部分,该模块、程序段、或代码的一部分包含一个或多个用于实现规定的逻辑功能的可执行指令。也应当注意,在有些作为替换的实现中,方框中所标注的功能也可以以不同于附图中所标注的顺序发生。例如,两个接连地表示的方框实际上可以基本并行地执行,它们有时也可以按相反的顺序执行,这依所涉及的功能而定。也要注意的是,框图和/或流程图中的每个方框、以及框图和/或流程图中的方框的组合,可以用执行规定的功能或操作的专用的基于硬件的装置来实现,或者可以用专用硬件与计算机指令的组合来实现。The flowchart and block diagrams in the figures illustrate the architecture, functionality and operation of possible implementations of apparatuses, methods and computer program products according to various embodiments of the present invention. In this regard, each block in a flowchart or block diagram may represent a module, program segment, or portion of code that contains one or more logical functions for implementing specified executable instructions. It should also be noted that, in some alternative implementations, the functions noted in the block may occur out of the order noted in the figures. For example, two blocks shown in succession may, in fact, be executed substantially concurrently, or they may sometimes be executed in the reverse order, depending upon the functionality involved. It should also be noted that each block in the block diagrams and/or flowcharts, and combinations of blocks in the block diagrams and/or flowcharts, can be implemented by a dedicated hardware-based device that performs the specified functions or operations , or may be implemented by a combination of dedicated hardware and computer instructions.
描述于本发明实施例中所涉及到的模块可以通过软件的方式实现,也可以通过硬件的方式来实现。所描述的模块也可以设置在处理器中。The modules involved in the embodiments described in the present invention may be implemented by software or by hardware. The described modules may also be provided in a processor.
作为另一方面,本发明还提供了一种计算机可读介质,该计算机可读介质可以是上述实施例中描述的电子设备中所包含的;也可以是单独存在,而未装配入该电子设备中。上述计算机可读介质承载有一个或者多个程序,当上述一个或者多个程序被该电子设备执行时,使得该电子设备:获取有关人员的电子设备中保存的声音文件并进行提取,扫描出设备中符合要求的音频格式文件并保存作为相关人员声纹库的语音数据源;借助语音识别引擎ASR将提取到的所述语音文件切分为语音片段;利用梅尔频率倒谱系数MFCC作为声学特征,计算得到语音帧特征矢量并对声纹矢量量化;根据计算得到的声纹矢量量化结果,进行PCA转换进行主成分分析,选择K均值算法对语音进行智能聚类,提取所有相关人员的语音特征,找到质量最好的语音片段组装成指定长度的语音文件作为聚类结果;根据语音聚类的结果,提取聚类后语音文件的声纹特征,建立规范化的标准应用库。As another aspect, the present invention also provides a computer-readable medium. The computer-readable medium may be included in the electronic device described in the above embodiments; or it may exist independently without being assembled into the electronic device. middle. The above-mentioned computer-readable medium carries one or more programs, and when the above-mentioned one or more programs are executed by the electronic device, the electronic device: obtains and extracts the sound files stored in the electronic device of the relevant person, scans out the device The audio format files that meet the requirements are saved as the voice data source of the voiceprint library of relevant personnel; the extracted voice files are divided into voice segments by means of the voice recognition engine ASR; the Mel frequency cepstral coefficient MFCC is used as the acoustic feature , calculate the feature vector of the voice frame and quantize the voiceprint vector; according to the calculated voiceprint vector quantization result, perform PCA conversion for principal component analysis, select the K-means algorithm to intelligently cluster the voice, and extract the voice features of all relevant personnel , find the best-quality speech fragments and assemble them into a speech file of a specified length as the clustering result; according to the speech clustering result, extract the voiceprint features of the clustered speech file, and establish a standardized standard application library.
以上描述仅为本发明的较佳实施例以及对所运用技术原理的说明。本领域技术人员应当理解,本发明中所涉及的发明范围,并不限于上述技术特征的特定组合而成的技术方案,同时也应涵盖在不脱离上述发明构思的情况下,由上述技术特征或其等同特征进行任意组合而形成的其它技术方案。例如上述特征与本发明中公开的(但不限于)具有类似功能的技术特征进行互相替换而形成的技术方案。The above description is only a preferred embodiment of the present invention and an illustration of the applied technical principle. It should be understood by those skilled in the art that the scope of the invention involved in the present invention is not limited to the technical solution formed by the specific combination of the above-mentioned technical features, and should also cover the technical solutions formed by the above-mentioned technical features or Other technical solutions formed by any combination of equivalent features. For example, a technical solution formed by replacing the above-mentioned features with technical features disclosed in the present invention (but not limited to) having similar functions.
Claims (9)
Priority Applications (1)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| CN202310100660.6A CN116206611A (en) | 2023-02-07 | 2023-02-07 | Method and device for automatically constructing case-related voiceprint library |
Applications Claiming Priority (1)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| CN202310100660.6A CN116206611A (en) | 2023-02-07 | 2023-02-07 | Method and device for automatically constructing case-related voiceprint library |
Publications (1)
| Publication Number | Publication Date |
|---|---|
| CN116206611A true CN116206611A (en) | 2023-06-02 |
Family
ID=86516749
Family Applications (1)
| Application Number | Title | Priority Date | Filing Date |
|---|---|---|---|
| CN202310100660.6A Pending CN116206611A (en) | 2023-02-07 | 2023-02-07 | Method and device for automatically constructing case-related voiceprint library |
Country Status (1)
| Country | Link |
|---|---|
| CN (1) | CN116206611A (en) |
Citations (3)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN107993663A (en) * | 2017-09-11 | 2018-05-04 | 北京航空航天大学 | A kind of method for recognizing sound-groove based on Android |
| CN111243601A (en) * | 2019-12-31 | 2020-06-05 | 北京捷通华声科技股份有限公司 | Voiceprint clustering method and device, electronic equipment and computer-readable storage medium |
| CN115273863A (en) * | 2022-06-13 | 2022-11-01 | 广东职业技术学院 | A composite online class attendance system and method based on voice recognition and face recognition |
-
2023
- 2023-02-07 CN CN202310100660.6A patent/CN116206611A/en active Pending
Patent Citations (3)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN107993663A (en) * | 2017-09-11 | 2018-05-04 | 北京航空航天大学 | A kind of method for recognizing sound-groove based on Android |
| CN111243601A (en) * | 2019-12-31 | 2020-06-05 | 北京捷通华声科技股份有限公司 | Voiceprint clustering method and device, electronic equipment and computer-readable storage medium |
| CN115273863A (en) * | 2022-06-13 | 2022-11-01 | 广东职业技术学院 | A composite online class attendance system and method based on voice recognition and face recognition |
Similar Documents
| Publication | Publication Date | Title |
|---|---|---|
| US10685657B2 (en) | Biometrics platform | |
| US10249304B2 (en) | Method and system for using conversational biometrics and speaker identification/verification to filter voice streams | |
| US9571652B1 (en) | Enhanced diarization systems, media and methods of use | |
| WO2021184837A1 (en) | Fraudulent call identification method and device, storage medium, and terminal | |
| US9336409B2 (en) | Selective security masking within recorded speech | |
| CN110659468B (en) | File encryption and decryption system based on C/S architecture and speaker recognition technology | |
| CN111405475B (en) | Multidimensional sensing data collision fusion analysis method and device | |
| CN110324314B (en) | User registration method and device, storage medium and electronic equipment | |
| WO2022142031A1 (en) | Invalid call determination method and apparatus, computer device, and storage medium | |
| WO2021174883A1 (en) | Voiceprint identity-verification model training method, apparatus, medium, and electronic device | |
| CN109634554B (en) | Method and device for outputting information | |
| CN116312559B (en) | Training method of cross-channel voiceprint recognition model, voiceprint recognition method and device | |
| CN113393318B (en) | Bank card application risk control method, device, electronic device and medium | |
| CN117155673A (en) | Login verification method and device based on digital human video, electronic equipment and medium | |
| CN115632862A (en) | Information security management method and system | |
| CN112926936A (en) | Bank business auditing method and device | |
| CN120633602A (en) | Method, device, electronic device and storage medium for obtaining property introduction speech | |
| US20260141061A1 (en) | Method and electronic device for handling anomaly detection | |
| CN115858619A (en) | Space-time trajectory accompanying analysis method and system based on multi-factor window | |
| WO2025126243A1 (en) | Method and electronic device for handling anomaly detection | |
| CN117354419A (en) | Voice telephone recognition processing method and device, electronic equipment and storage medium | |
| CN115547343A (en) | Voiceprint recognition method and device, edge device and voiceprint recognition system | |
| CN121387239A (en) | Aging-suitable anti-fraud intelligent protection system based on multi-mode detection and LSTM model | |
| CN118380000A (en) | Source object recognition method and device, electronic equipment, storage medium and computer program product | |
| CN117037800A (en) | Voiceprint recognition model training method, voiceprint recognition device and readable medium |
Legal Events
| Date | Code | Title | Description |
|---|---|---|---|
| PB01 | Publication | ||
| PB01 | Publication | ||
| SE01 | Entry into force of request for substantive examination | ||
| SE01 | Entry into force of request for substantive examination | ||
| CB02 | Change of applicant information | ||
| CB02 | Change of applicant information |
Country or region after: China Address after: 361000 Fujian Province Xiamen City Torch High-tech Industrial Development Zone Software Park Phase II Qianpu East Road 188, 19th Floor Applicant after: Guotou Intelligent Information Technology Co.,Ltd. Address before: 361000 unit 102-402, No.12, guanri Road, phase II, software park, Siming District, Xiamen City, Fujian Province Applicant before: XIAMEN MEIYA PICO INFORMATION Co.,Ltd. Country or region before: China |